Liquid AI launches LFM3 multimodal models for specialized AI
Liquid AI unveiled LFM3, a multimodal family of small open-weight models for specialized intelligence, with benchmarks and edge focus.
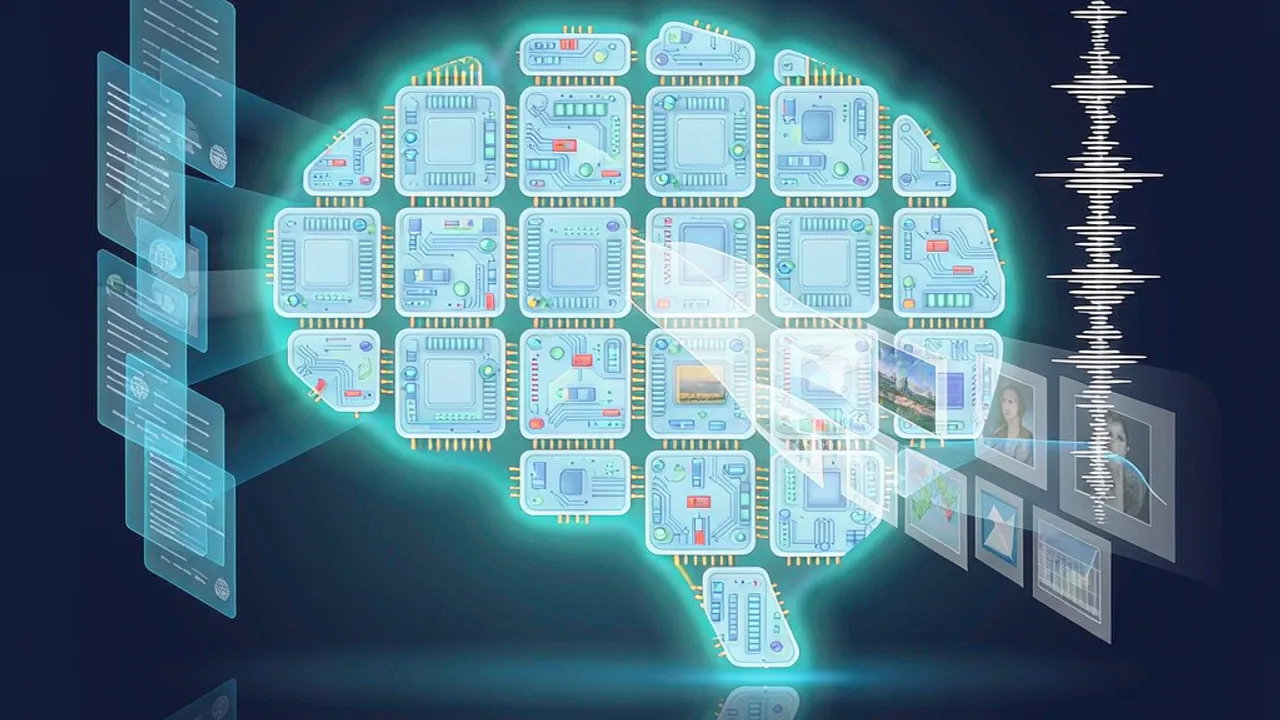
Liquid AI announced LFM3, a multimodal family of open-weight models for specialized intelligence, according to its blog at Liquid AI. The announcement matters because it describes a small model family that blends text, vision, audio, omni and decision capabilities on a shared architecture, while targeting fine-tuning and on-device deployment.
What was announced, and why it matters
Liquid AI said LFM3 is its new generation of Liquid Foundation Models. The first release covers models in the 2B parameter range. The family is multimodal by nature and brings text, vision, audio, omni and decision models onto one new shared backbone. It is built on a new hybrid architecture and 22T tokens of pre-training, and the company said it is more expressive than LFM2 while maintaining efficiency.
The base and post-trained models are open-weight and available on Hugging Face, Liquid AI Playground, and the Liquid AI API, according to the source. The reason this matters is that specialized intelligence often means smaller, task-focused systems rather than one giant general model. Liquid AI framed LFM3 as an attempt to put more capability into a small, fast model that can be fine-tuned locally and run on constrained hardware.
How does the LFM3 architecture improve capability and speed?
The architecture work centers on a hybrid design. LFM2 used short convolutions and attention. For LFM3, Liquid AI used automated hardware-in-the-loop architecture search and expanded the setup from earlier work on one phone and one laptop to 14 device and backend combinations, including phones, a Raspberry Pi 5, laptops, Arm and x86 cloud CPUs, GPUs, and a Qualcomm Hexagon NPU.
Liquid AI said gated short convolutions still made up over half the layers. The team tried swapping some for other sequence blocks and found sliding-window attention gave the best quality and speed tradeoff. The final design had 24 layers: 13 convolutions, 5 sliding-window attention layers with a 256-token window, and 6 global attention layers. The convolutions used a kernel size of 7, up from 3 in LFM2.
Other changes included head-wise gated attention, partial RoPE, and sandwich norm. The text model has a 256K token context window and uses the same 128K vocabulary as LFM2.5-8B-A1B. The source page includes a video at YouTube tied to the multimodal discussion.
What are the model variants and benchmark claims?
The first LFM3 release includes six 2B-class models branched from the same LFM3-1.7B-Base backbone. Four cover text, vision, audio, and omni, and two are decision models specialized from the vision and omni models, according to Liquid AI.
The text model, LFM3-1.7B, has a 256K context window and was post-trained for agentic harnesses such as Hermes Agent, Pi, and OpenClaw. Liquid AI said it can triage an inbox, manage a calendar, research topics, send briefings, and use tool search. The company said LFM3-1.7B outperforms its previous LFM2.5-2.6B while using 35% fewer parameters.
Benchmarks were presented in categories including agents, tool use, agentic coding, coding, instruction following, knowledge, and long context. Liquid AI said LFM3-1.7B competes with models several times its size on agentic tasks, leads on instruction following and function calling on some tests, and beats Qwen3.5-9B on long browser and business tasks. The source page includes a second video at YouTube and a third at YouTube. It also mentions grounded tool use from speech at YouTube.
How can developers and researchers use LFM3?
Liquid AI said every LFM3 instance is an ideal candidate for specialized intelligence. The models can be fine-tuned on a single GPU, and the text model fits in about 1 GB at 4-bit precision. The company said the models can be fine-tuned locally and deployed where the application runs. The final 3.5T tokens of pre-training were a mid-training stage on curated data, with more agentic traces and tool calls.
For practical deployment, Liquid AI said LFM3-1.7B can be served at low latency under random traffic and can support real-time use cases such as online fraud detection when run on Liquid RIPL. The source reported that on a single NVIDIA B300 with SGLang in BF16, LFM3-1.7B can produce 3.6 billion tokens per day at 1,024 concurrent requests, more than any other model in the comparison. The source also quoted AMD, Ambarella, and Qualcomm perspectives on edge AI.
How does this relate to Grafy?
Grafy does not appear to have a native LFM3 integration in the product list reviewed here. The genuine overlap is specialized, multimodal AI for agents and edge-adjacent deployment. For developers who want to explore instruction-tuned behavior or agent harnesses, Grafy Chat is the closest listed surface because it offers multi-model AI chat, and Grafy Code is an AI coding studio that installs packages and runs code. A reader could use Grafy Chat to assemble comparative prompts, though LFM3 availability would depend on the models enabled in a plan.
Frequently asked questions
What is LFM3?
Liquid AI introduced LFM3 as a multimodal family of open-weight models for specialized intelligence. The first release focused on 2B parameter models that combine text, vision, audio, omni, or decision capabilities, with a shared backbone and open weights. It was announced on October 27, 2026, according to the source.
Why is LFM3 significant?
It matters because it shows a small model family becoming more expressive and capable for agentic and specialized tasks while retaining efficiency. Liquid AI claimed LFM3-1.7B outperformed a larger prior model with fewer parameters and performed well in agentic benchmarks.
How can developers try the underlying ideas?
Developers could fine-tune LFM3 locally, run it on constrained devices, or adapt it for agentic harnesses. For immediate experimentation, the source suggests trying the API, Playground, or Hugging Face weights, while local fine-tuning is described as feasible on a single GPU.
Source: Hacker News — front page — Introducing LFM3: Every Modality for Specialized Intelligence
More news
Liquid AI launches LFM3: Six open‑weight 2B‑class multimodal models
Liquid AI unveiled LFM3, six open‑weight 2 billion‑parameter multimodal models for text.
DeepMind unveils Genie 4, a real‑time multimodal world simulation model
DeepMind announced Genie 4, a multimodal model that generates photorealistic visuals.
Krea 3 AI Model Claims 4× Faster Editing Than Competitors
Krea 3, a new AI image editing model, claims to be four times faster and cheaper than leading competitors.