New Benchmark Tests AI Agents on Full 3D Game Development
Researchers have launched 3D GameDev Arena to test if coding agents can build complex 3D games from scratch, moving beyond simple 2D templates.
 Source: Grafy Research Lab
Researchers have introduced a new benchmark designed to evaluate whether AI coding agents can handle the massive, multi-step complexity of building 3D games from scratch. While current agents can often fix small bugs or generate simple 2D programs, the ability to orchestrate assets, mechanics, and 3D scenes over a long period remains an unsolved challenge.
What is the 3D GameDev Arena?
According to the researchers, 3D GameDev Arena is a benchmark consisting of 108 different game-development tasks spanning 14 distinct genres. Unlike previous benchmarks that provide agents with ready-made templates, pre-loaded assets, or even working reference code, this arena requires agents to start from an empty folder.
To complete a task, an agent is provided only with a text specification and reference images for the user interface and experience. The agent must then navigate a "plan–implement–test–repair" pipeline to build a self-contained browser game. This process is computationally intensive; the researchers note that runs average approximately 1,000 Large Language Model (LLM) calls, with the most complex task requiring 14,407 calls, 2.13 billion tokens, and the management of 608 individual assets.
How are the generated games evaluated?
Because every agent creates a unique codebase, the evaluation process cannot rely on fixed interfaces. The researchers implemented a three-level evaluation system to ensure accuracy and quality.
First, the system performs non-visual functional evaluation. This involves a process where the testing rubric is frozen before the agent begins, and then specific test code is adapted to the game's unique structure after it is built to check if it meets the original specification.
Second, the benchmark uses agent-based QA to assess the 3D presentation and playability. As shown in Figure 4, this involves recording the browser gameplay and judging whether visual elements, such as tutorial panels, interfere with the player's ability to interact with the game.
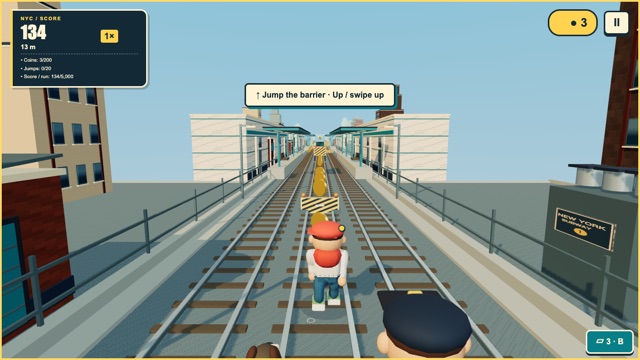
Third, the researchers utilize blind, pairwise human preference testing. This "public arena" uses the Bradley–Terry model to turn subjective human votes into reliable rankings, measuring whether a game is actually "fun" rather than just technically functional. Figure 1 provides an overview of this entire automated pipeline, from the initial task specification to the final scoring.
Can AI agents build high-quality 3D games?
Preliminary results suggest that long-horizon 3D game development is still a significant hurdle for current AI. The researchers found that code-level correctness does not always correlate with player enjoyment. In their testing, two different configurations might achieve the same functional score, yet one could be twice as preferred by human players.
Interestingly, the study found that the most successful agents were those that actively tested the running game during the development process, rather than those that only focused on verifying the underlying code. This highlights the importance of "playtesting" as a core part of the autonomous development loop. The data indicates that while agents are increasingly capable of retaining long-term goals, the tight coupling of 3D assets, interaction logic, and visual presentation remains a major difficulty.
Why does long-horizon development matter?
Most existing AI benchmarks are relatively short, often capping runs at a few hundred steps or one to two hours of work. The 3D GameDev Arena pushes into "extreme long-horizon" territory. This is critical because real-world software engineering—especially in game development—requires maintaining a consistent architectural plan over thousands of operations.
When an agent works on a project for several hours, it must manage a massive amount of context, organize dozens of 3D assets, and adapt its plan when a specific implementation fails. The ability to succeed in this environment is a much truer test of an agent's reasoning and planning capabilities than solving isolated coding problems.
Applying these concepts in Grafy
While the 3D GameDev Arena is a research benchmark for testing the limits of autonomous agents, the concept of turning a brief into a playable experience is central to the creative workflow. For those interested in exploring the current state of AI-driven game creation, Game Studio allows users to describe a game and see it rendered in the browser. While it does not use the specific benchmark pipeline described in the paper, it demonstrates the practical application of prompt-to-game technology.
Frequently asked questions
What does the 3D GameDev Arena measure?
The 3D GameDev Arena measures the ability of AI coding agents to develop complete 3D browser games from scratch. It evaluates them on three levels: functional correctness against a specification, the quality of 3D presentation and playability through agent-based QA, and human preference through blind pairwise testing.
How does this benchmark differ from previous ones?
This benchmark differs because it provides no starter code, templates, or pre-loaded assets, forcing agents to build everything from an empty folder. It also focuses on "extreme long-horizon" tasks that require thousands of model calls and hours of development, whereas previous benchmarks were much shorter and more constrained.
Do functional tests guarantee a fun game?
No, functional tests do not guarantee a fun game. The researchers found that an agent can pass all code-level and rule-based tests while still producing a game that humans find uninteresting. Player preference often depends on factors like 3D presentation and playability that go beyond simple code correctness.
More news
OpenComputer launches as open-source Devin alternative
DiggerHQ has released OpenComputer, an open-source coding agent designed to be faster than Devin and capable of self-hosting in private clouds.
Google's Gemini 4 Neon tops Models Engineering Index rankings
Google's Gemini 4 Neon has claimed the top spot on the Models Engineering Index. Learn how this new ranking evaluates AI performance and cost.

New DEO Method Fixes AI Retrieval Failures in Negation Queries
Researchers have introduced Direct Embedding Optimization (DEO) to solve how AI fails at exclusion queries. Learn how this training-free approach works.