DetourBench Introduces Exact Minimum-Action Evaluation for Interactive Agents
DetourBench, a new benchmark from the Grafy Research Lab, measures interactive AI agents by the exact number of actions needed.
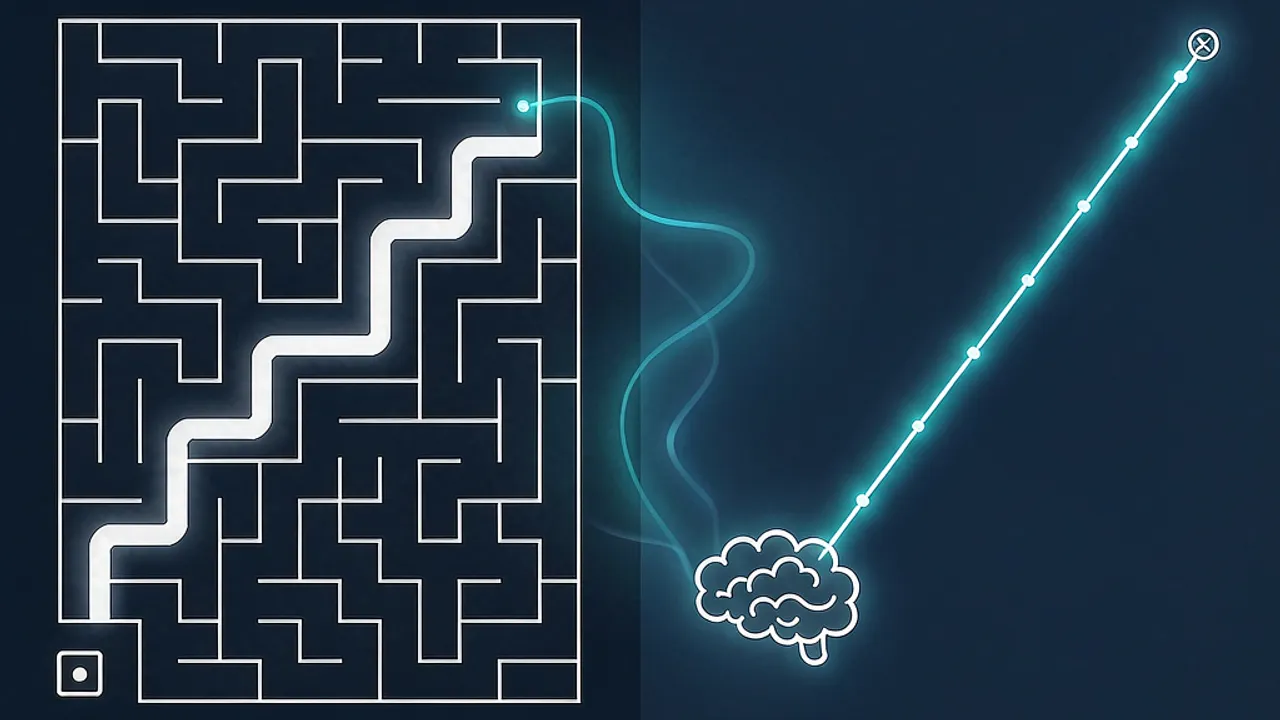 Source: Grafy Research Lab
DetourBench, announced by the Grafy Research Lab on arXiv, changes how interactive AI agents are judged by focusing on the exact number of actions required to solve a task rather than only on whether the final state is correct. This shift matters because it lets developers and researchers differentiate between agents that arrive at the right answer efficiently and those that waste steps, a distinction hidden by traditional endpoint‑only benchmarks.
What problem does DetourBench aim to solve?
Current evaluation suites for language‑model‑driven agents typically report a binary outcome: did the agent reach the target state or not. According to the paper, such endpoint scoring "cannot separate an agent that retrieved exactly the evidence a decision required from one that read most of the environment, nor an agent that never located the evidence from one that stopped a single action short." The lack of a reference cost means that authors can only prove a task is solvable, without showing that an agent followed the shortest possible route. DetourBench addresses this gap by constraining environments so that the minimum‑action path is computationally tractable, allowing a precise lower bound for each task.
How does DetourBench compute the minimum‑action bound?
The benchmark designs each task as a finite, fully observable decision problem. By limiting the state space and action set, the authors make it possible to run an exhaustive search or dynamic‑programming algorithm that yields the exact smallest number of steps needed to reach the goal. The paper notes that "each task is a finite, —" (the abstract truncates, but the intent is clear): the environment is deliberately simplified until the optimal trajectory can be calculated without approximation. This exact bound becomes a reference cost against which any agent’s trajectory can be compared.
Why does trajectory‑level evaluation matter for developers?
When an agent’s performance is measured against a known optimal action count, developers can pinpoint inefficiencies in planning, memory, or tool use. For example, an agent that reaches the correct final state in ten steps while the optimal path is five steps reveals a systematic detour—perhaps excessive searching or redundant tool calls. By exposing these gaps, DetourBench enables targeted improvements, such as refining the agent’s search strategy, adding better evidence‑retrieval modules, or tightening tool‑selection heuristics. In practice, this leads to agents that are not only correct but also faster and cheaper to run, an important factor for production deployments.
How can researchers use DetourBench to compare models?
Researchers can run multiple language‑model agents on the same set of DetourBench tasks and report the ratio of actual actions taken to the optimal action count. This ratio provides a normalized efficiency metric that is comparable across model sizes, prompting strategies, and toolkits. Because the benchmark supplies the exact minimum, statistical significance testing becomes more meaningful: a modest improvement in action count can be demonstrated as a genuine gain rather than noise. The authors also suggest that the benchmark can serve as a training signal—agents could be rewarded for staying close to the optimal trajectory, encouraging more disciplined planning.
Where does DetourBench fit within the Grafy ecosystem?
The benchmark’s focus on precise trajectory analysis aligns well with Grafy’s Graph app, which visualizes branching prompt flows and model outputs. By importing DetourBench task logs into the Graph workspace, creators can overlay the optimal path alongside the agent’s actual steps, making inefficiencies instantly visible. Additionally, the Reader app offers a convenient way to ingest the full arXiv paper, search for specific methodology details, and ask follow‑up questions about the benchmark construction. For developers wanting to prototype agents that respect the minimum‑action bound, the Code studio provides an environment to implement custom planning loops and test them against DetourBench tasks. Quick experimentation can also be done in Chat, where multiple model back‑ends can be queried about the optimal strategy for a given task, helping to generate baseline policies.
How can you start experimenting with DetourBench today?
- Read the paper: Open the arXiv entry in Grafy Reader ([/reader]) to explore the full description, task definitions, and the algorithm used to compute the optimal action count.
- Load a task: Use the Graph app ([/graph]) to import a JSON representation of a DetourBench task. The graph will display each possible action node and the optimal path highlighted.
- Build an agent: In Code ([/code]), write a simple loop that queries a language model (via the multi‑model Chat interface at [/chat]) for the next action, then executes it in the provided environment simulation. Compare the number of steps taken with the benchmark’s optimal count.
- Iterate: Adjust the agent’s prompting strategy, tool selection, or memory handling, and re‑run the task. Use the Graph view to see whether the new trajectory moves closer to the optimal bound.
By following these steps, creators, developers, and researchers can harness DetourBench to build agents that are not only correct but also action‑efficient, a quality that becomes increasingly important as AI systems are deployed at scale.
Frequently asked questions
How does DetourBench differ from existing interactive‑agent benchmarks?
Existing benchmarks usually score agents by whether they achieve the target state, ignoring how many intermediate steps were taken. DetourBench adds an exact minimum‑action bound for each task, enabling a direct comparison of an agent’s efficiency against the optimal trajectory.
Can DetourBench be used with any language model?
Yes. The benchmark defines the environment and optimal action count independently of the model. Any language‑model‑driven agent—whether accessed through Grafy Chat, a custom API, or an open‑source model—can be evaluated by measuring how many actions it needs relative to the provided optimal count.
Is the optimal action count always computable for real‑world tasks?
DetourBench deliberately constructs tasks where the state space is finite and the optimal path can be calculated exactly, often via exhaustive search or dynamic programming. For more complex, open‑ended problems the exact bound may be infeasible, but the benchmark’s design shows how to create tractable evaluation settings.
More news
Razavi‑Bench Shows Near‑Perfect AI Mastery of Analog Circuit Reasoning
A new benchmark based on Razavi's analog design questions tracks AI models improving from 28% to 98% accuracy.
ConvRSI introduces parallel self‑improvement for multi‑agent systems
A new framework called ConvRSI parallelizes multi‑agent self‑improvement using convolution.
Accelerate Bench evaluates AI coding agents on program optimization
Accelerate Bench, a new benchmark of 32 CPU‑level optimization tasks from scientific code.