Frontier3DBench Tests Whether Coding Agents Build 3D Worlds
Einsia's Frontier3DBench tests whether coding agents can build 3D objects, scenes and working worlds; GPT-6.1-sol led overall. See what it means.
 Source: Reddit ML
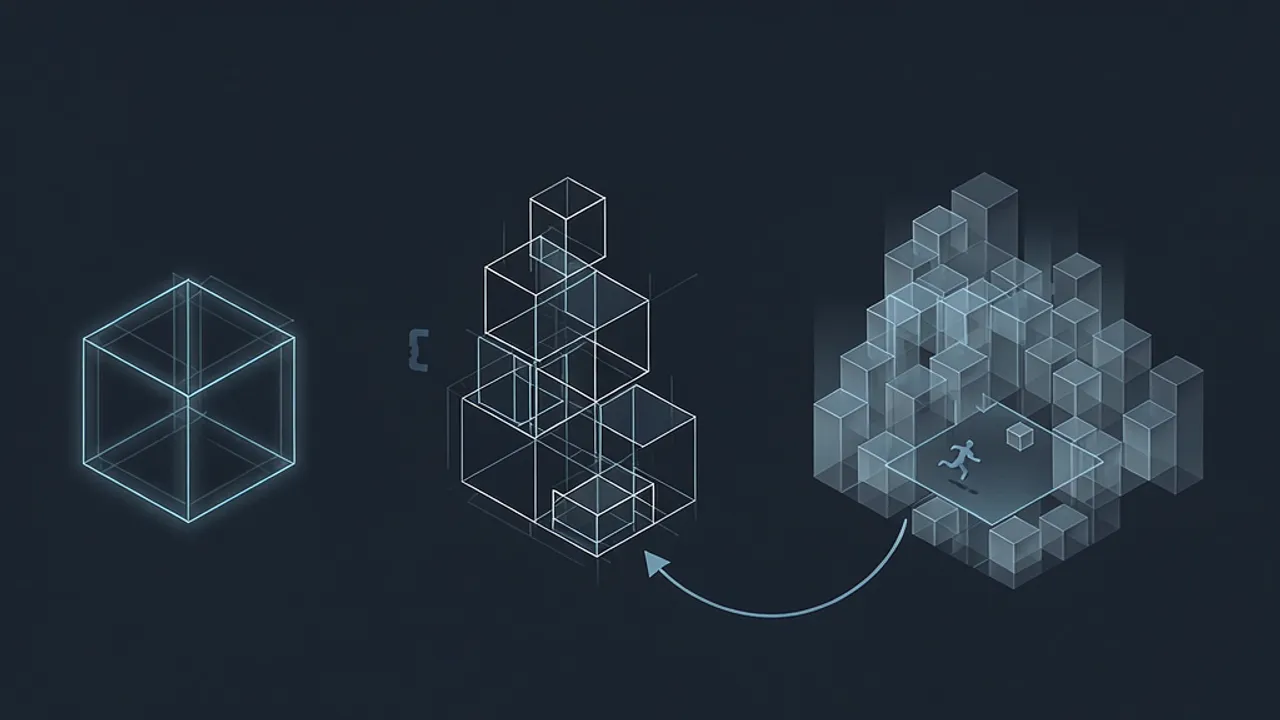
A new benchmark called Frontier3DBench sets out to measure whether today's coding agents can carry a 3D creation from a single object all the way to a full, interactive world — and its early results suggest they are much better at inventing from a text prompt than at faithfully rebuilding something from a reference. Released by a team at Einsia and shared on Reddit's r/MachineLearning, the evaluation matters because it targets the exact handoff that has been shaky for AI tools: turning code and prompts into 3D assets that not only look right but behave correctly once you run them.
What is Frontier3DBench?
According to the team at Einsia, Frontier3DBench is built to test a three-step progression: whether an agent can build a detailed 3D object, assemble those objects into a scene, and then make an interactive world that actually works. As described in the r/MachineLearning post, the benchmark contains 145 tasks spread across 9 categories. It compares 11 different model-and-harness configurations — pairings of a model with the scaffolding that lets it take actions — and asks each one to produce editable Blender projects and runnable Unreal Engine worlds.
The wording there is deliberate. "Editable" and "runnable" mean the outputs are meant to be opened, inspected and executed, not just admired as pictures. That framing is what gives the benchmark its edge over image-quality contests, because it forces the question of whether a generated asset holds up as a real, working piece of software.
How does the benchmark score a 3D result?
Instead of judging a single rendered frame, the evaluation looks at three dimensions — appearance, structure, and behavior — according to the post. Appearance and structure are assessed through rendered views and by inspecting the scene directly, while behavior is checked by running the generated world and seeing whether it functions at runtime.
That combination is the point. A model can produce something that looks convincing in a still image and still fall apart the moment the scene is opened or the world is set in motion. By scoring behavior separately, Frontier3DBench makes that gap visible rather than hiding it behind a flattering screenshot.
Which models came out on top?
The results split by task type rather than crowning one clean winner. According to the post, GPT-6.1-sol led overall and also topped the object and scene categories. For interactive worlds specifically, GPT-6-astra took the lead instead. One of the more telling placements was MiniMax-M3.1-Flash, which the team ranked sixth overall but second on scene editing — a reminder that a model's overall standing can mask genuine strength in a narrow slice of the work.
The write-up also reported results across 165 world submissions, focusing on how local mechanisms scored, though the specific figures were not part of the summary available. Taken together, the spread of leaders suggests that the "best model" depends heavily on which stage of the object-scene-world progression you care about.
What did the benchmark reveal about reconstruction versus generation?
One of the clearest patterns is a gap between two ways of making 3D content. According to the post, every configuration scored lower on reference-based reconstruction — rebuilding a specific object or scene from a provided example — than on text-driven generation, where the model invents from a written prompt. This held true for both object and scene tasks.
In practical terms, the agents were more comfortable designing something new from a description than reproducing something that already exists. That is worth noting because faithful reconstruction is often the harder and more commercially useful skill: matching a real product, a scanned prop, or an existing asset is a common production need, and it is exactly where these systems still trail their text-to-3D abilities.
How does this connect to Grafy?
For creators and developers who want to explore these ideas without standing up their own Blender and Unreal pipelines, Grafy offers a few relevant entry points. 3D Studio generates and edits 3D models, which maps to the object-and-scene end of the benchmark. Game Studio turns a written brief into a playable game, the closest parallel to building an interactive world that runs. And Grafy Code is an AI coding studio that can install packages and run your code — the kind of agentic, execute-and-check loop Frontier3DBench is designed to test. For a closer look at how an agent plans a 3D build and then carries it out, see An AI agent that plans your 3D build, then runs it. Grafy did not produce Frontier3DBench and is not part of the study; these are simply tools for trying the same ideas in practice.
Frequently asked questions
What does Frontier3DBench measure?
Frontier3DBench measures whether coding agents can build 3D content across three levels — a detailed object, an assembled scene, and a working interactive world. According to the r/MachineLearning post, it uses 145 tasks in 9 categories and 11 model–harness configurations, judging appearance, structure, and behavior through rendered views, scene inspection, and runtime tests.
Which model led Frontier3DBench overall?
According to the post, GPT-6.1-sol led the benchmark overall and also topped the object and scene categories. Interactive worlds were a separate story: GPT-6-astra led that category instead. So no single model won everything — leadership depended on whether the task was building objects and scenes or making a world that actually runs.
Did agents do better at generating from text or reconstructing from a reference?
They did better at text-driven generation. According to the post, every configuration scored lower on reference-based reconstruction — rebuilding a specific object or scene from an example — than on generating from a written prompt, and this held for both object and scene tasks. The agents were more capable of inventing new designs than of faithfully reproducing existing ones.
More news
Chrome's Modern Web Guidance hits 1.0, adds Firefox and Edge
Chrome released Modern Web Guidance 1.0, giving coding agents expert web best practices, now backed by Firefox and Edge. Here's what changed.

Anthropic launches Claude Fable 5.2, Mythos 5.2, cuts API prices 20%
Anthropic's Claude Fable 5.2 and Mythos 5.2 top several third-party benchmarks and cut API prices 20%. Here's what the effort settings mean for your bill.
United Won't Let AI Agents Book Flights on Its Site
United says AI assistants can browse its flights but can't complete bookings, citing privacy and regulatory worries. Here's what it means for agents.