Grafi Research Lab releases a human‑in‑the‑loop framework for AI and data science pipelines
A new human‑in‑the‑loop framework targets automation bias and tacit knowledge gaps in AI & data science, offering demos, code and data for practitioners.
 Source: Grafy Research Lab
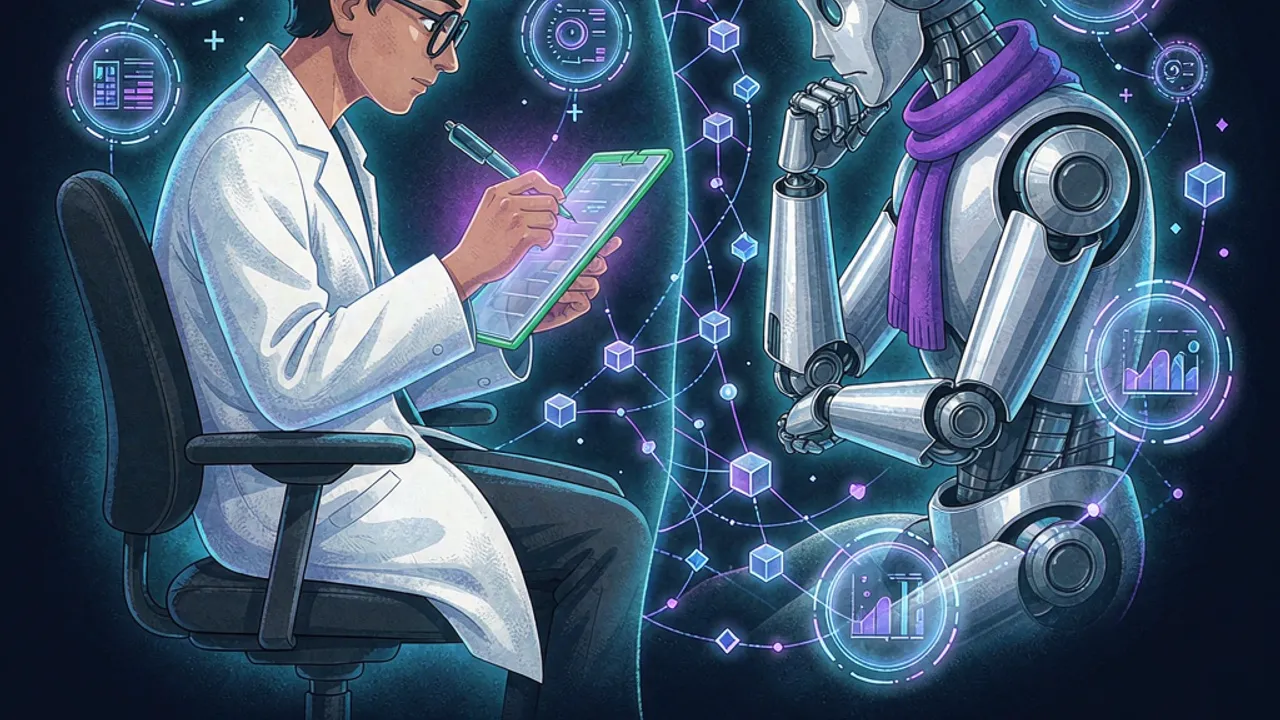
Human‑in‑the‑loop (HITL) methods are gaining traction as a way to address the blind spots of fully automated machine learning, and Grafi Research Lab has just released a new framework that puts people back at the center of AI and data‑science pipelines. The paper, titled Advancing Cognitive Pairwise Comparisons for Human‑Centric Artificial Intelligence and Data Science: A Human‑in‑the‑Loop Framework, details how iterative human input can improve predictive performance and reduce automation bias.
What is the new Human‑in‑the‑Loop framework?
The framework proposes a structured workflow where humans and AI models collaborate at key decision points. Rather than treating human feedback as a one‑off correction, the approach integrates pairwise comparisons—where users rank alternative data transformations, feature sets, or model configurations—into the learning loop. Each comparison informs the next round of model training, creating a feedback cycle that continuously refines the system. According to the paper, this cycle is designed to be "cognitive" because it leverages the way people naturally evaluate alternatives, making the process more intuitive and less error‑prone.
Why does human involvement matter for AI & data science?
Fully automated pipelines can suffer from automation bias, where users over‑trust model outputs even when they are flawed. Moreover, many domain insights are tacit—hard to encode in code but easy for experts to recognize when presented with examples. The framework argues that embedding human judgment directly into data transformation, feature selection, weighting and model selection steps helps capture this tacit knowledge. By doing so, it reduces the risk of blind spots that purely statistical methods might miss, and it keeps the development loop aligned with real‑world objectives.
Which stages of the AI&DS pipeline benefit most?
The authors identify four stages that traditionally demand the most human effort:
- Data transformations – deciding how to clean, normalize, or augment raw data.
- Feature selection – choosing which variables best capture the problem space.
- Feature weighting – assigning importance to features when models do not learn it automatically.
- Model selection – picking the algorithmic family that fits the task.
In each stage, the framework inserts pairwise comparison tasks that let users quickly express preferences (e.g., "Transformation A is better than B for this dataset"). These preferences are then converted into quantitative signals that guide the next iteration of model training.
How can developers and researchers try the framework?
Grafi Research Lab has made the framework accessible through several resources:
- Interactive web demos – hosted at a public URL, allowing users to experiment with the pairwise comparison interface without installing anything.
- Source code – released under an open‑source license, enabling integration into existing pipelines or customization for specific domains.
- Datasets – the authors provide the data used in their experiments, so practitioners can reproduce results and benchmark their own implementations.
All three assets are linked from the paper’s arXiv page, giving immediate entry points for anyone who wants to explore the workflow hands‑on.
Applying the framework with Grafy tools
While the framework itself is model‑agnostic, Grafy’s suite of multimodal apps can streamline the HITL process for creators, developers and researchers.
- Reader – Load the arXiv PDF directly into Grafy Reader to search, annotate, and ask questions about the methodology. The AI‑assisted chat can surface specific sections on pairwise comparison design.
- Graph – Use the Graph app to map each iteration of the HITL loop: start with a data‑transformation node, branch into alternative feature‑selection nodes, and attach model‑selection outcomes. This visual history makes it easy to trace how human choices affect downstream performance.
- Code – Prototype the pairwise‑comparison engine in Grafy Code, where you can write, test, and run scripts that ingest the provided datasets and generate the comparison signals described in the paper.
- Chat – If you need quick clarification on how to adapt the framework to a specific domain, Grafi Chat lets you converse with multiple model back‑ends side by side, helping you decide which LLM best supports your workflow.
By combining these apps, a researcher can go from reading the paper to building an end‑to‑end HITL pipeline without leaving the Grafy workspace.
What are the broader implications for AI development?
Embedding human judgment at systematic checkpoints could become a standard practice for safety‑critical or high‑stakes applications, where blind reliance on black‑box models is unacceptable. The framework’s emphasis on pairwise comparisons also aligns with emerging research on preference‑learning and reinforcement‑learning‑from‑human‑feedback, suggesting a converging trend toward more transparent, controllable AI systems.
The availability of demos and open‑source code lowers the barrier for teams to experiment, potentially accelerating adoption across fields such as healthcare, finance, and environmental modeling, where domain expertise is indispensable.
Source: https://arxiv.org/abs/2611.20926
More news

Anthropic prices IPO at $83 a share, valuing the AI firm at $1.5 trillion
Anthropic filed its S‑1 on Nov 18, setting the IPO price at $83 per share and a $1.5 trillion valuation.
Study Finds Confidence Scores Don't Guarantee Better LLM Answers
Researchers show that confidence signals can rank correct responses but often fail to improve outcomes.
Largest US school districts weigh dropping Google Search over AI mandate
New York, Los Angeles and Chicago school districts are evaluating alternatives to Google Search after Google announced it will disable Search for schools.