Hybrid RAG Framework Boosts Deceptive Review Detection with RoBERTa‑LoRA and FAISS
A new Retrieval‑Augmented Generation system combining RoBERTa‑LoRA, FAISS retrieval and LLM reasoning hits 0.90 F1 in cross‑domain deceptive review detection.
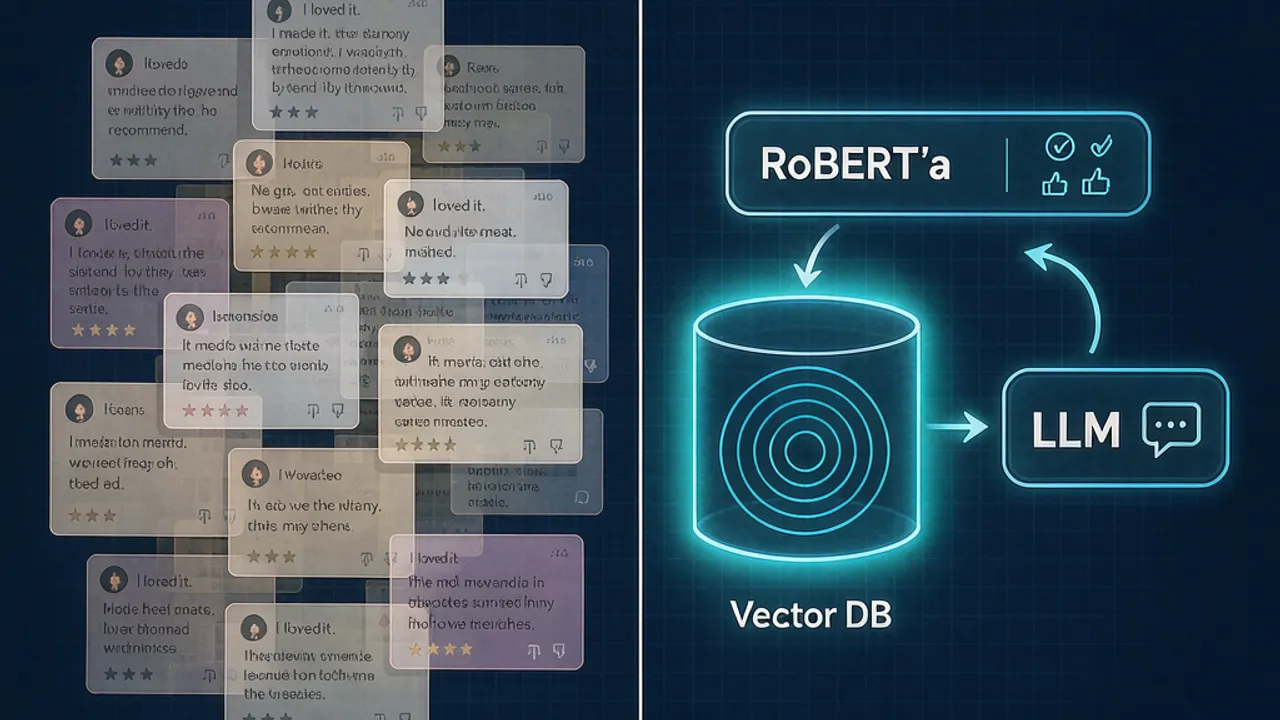 Source: Grafy Research Lab
Why detecting deceptive reviews matters now
The rise of fabricated opinions on e‑commerce platforms, travel sites and social media has become a measurable threat to consumer trust and market fairness. According to the authors of the paper, deceptive reviews can distort purchasing decisions, inflate reputations and even facilitate fraud. Early detection is therefore essential for both platform operators and researchers seeking to curb misinformation.
What is the hybrid Retrieval‑Augmented Generation (RAG) framework?
The research introduces a three‑stage pipeline that blends classification, semantic search and generative reasoning. First, a RoBERTa model fine‑tuned with Low‑Rank Adaptation (LoRA) acts as a lightweight classifier that quickly filters obvious spam. Next, the filtered texts are encoded into dense vectors and stored in a FAISS index, enabling fast similarity search against a curated corpus of verified reviews. Finally, a large language model receives the retrieved passages and the original review, then produces a final judgment explaining why the input is likely deceptive. The authors describe this combination as a "hybrid RAG" because it augments generative reasoning with external, task‑specific knowledge.
Which models and techniques are combined?
- RoBERTa‑LoRA classifier – RoBERTa provides a strong language understanding backbone, while LoRA adds a small set of trainable rank‑decomposed matrices, keeping fine‑tuning efficient. The paper reports that only five epochs of LoRA training were sufficient for robust domain transfer.
- FAISS vector retrieval – FAISS (Facebook AI Similarity Search) indexes the semantic embeddings of a large set of genuine reviews. During inference, the system retrieves the most relevant neighbor vectors, giving the downstream LLM concrete evidence rather than relying solely on internal knowledge.
- Large Language Model reasoning – The final stage uses an LLM (the specific model is not named) to synthesize the classifier’s label and the retrieved examples, generating a reasoned verdict and optional explanations that can be presented to end‑users or moderators.
How well does the system perform?
The authors evaluated the pipeline on two realistic test beds: a balanced dataset where deceptive and genuine reviews are equally represented, and a severely imbalanced set that mirrors real‑world conditions where spam is a small minority. In cross‑domain experiments—training on one product category and testing on another—the approach achieved an F1‑score of , demonstrating strong generalisation. The paper highlights that the five‑epoch LoRA fine‑tuning was enough to bridge domain gaps without extensive re‑training.
How creators and researchers can experiment with a similar workflow in Grafy
Grafy provides a suite of apps that let you assemble comparable pipelines without leaving the browser.
- Use Grafy Reader to upload the research paper, then ask the AI to summarise the methodology or extract the exact prompts used for RoBERTa‑LoRA fine‑tuning.
- Build the retrieval component with Grafy Code: the coding studio can run Python scripts that install FAISS, encode review texts with a RoBERTa checkpoint and populate an index. The environment supports the same open‑source libraries cited in the paper.
- Wire the three stages together in Grafy Graph, which lets you visualise a branching workflow of prompts, model calls and data transformations. You can attach the RoBERTa‑LoRA inference node, the FAISS search node and the LLM reasoning node, then iterate on parameters visually.
- Finally, test the end‑to‑end system with Grafy Chat, selecting the same LLM used in the study (or a comparable open‑source alternative) to see how it reasons over retrieved examples. This modular approach mirrors the paper’s architecture while giving you immediate feedback and the ability to tweak each component.
What are the limitations and next steps?
The authors note that the framework still depends on the quality of the underlying review corpus; noisy or biased reference data could mislead the LLM. Moreover, the study focuses on English‑language reviews, leaving multilingual extension as an open problem. Future work suggested by the paper includes exploring dynamic index updates as new reviews arrive and integrating stronger factual verification modules to further reduce false positives.
Source: https://arxiv.org/abs/2611.24049
More news
Study Finds Gender Stereotyping in LLM‑Generated Bedtime Stories Across 35 Countries
Researchers analyzed 62,873 stories from 16 large language models and uncovered gendered portrayals that vary by narrator role and country.
MIRAGE Introduces Multi‑hop Reasoning with Dynamic Knowledge Injection
Researchers unveil MIRAGE, a framework that lets large language models update and reason with conflicting and new knowledge across multiple hops.
RSI‑Prime Dataset Enables LLMs to Train Other Models
A new arXiv dataset, RSI‑Prime, provides 350 full training trajectories to teach large language models how to conduct model‑training.