LightTAR boosts multimodal tabular learning with cheap target‑aware embeddings
Researchers introduce LightTAR, a fast method that adds task‑aware features to PCA‑reduced embeddings.
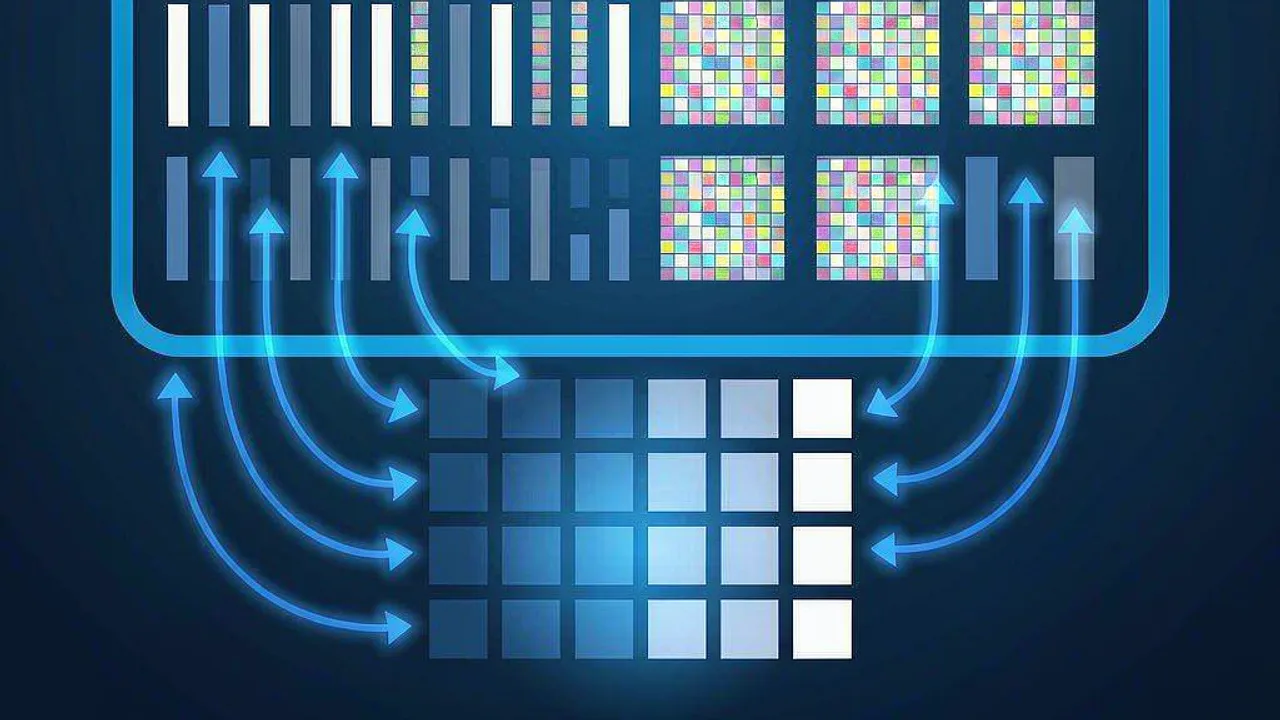 Source: Grafy Research Lab
LightTAR, a new technique for multimodal tabular learning, adds a small set of target‑aware features to the usual PCA‑reduced embeddings, delivering consistent predictive gains with only a modest runtime increase. The method matters because many real‑world tables contain text and images that are currently compressed in a way that ignores the prediction task, potentially discarding useful signals.
What is LightTAR and why it matters?
LightTAR stands for Light and Fast Target‑Aware Representations. According to the paper released by the Grafy Research Lab, multimodal tabular learning combines structured numeric and categorical columns with unstructured text and image fields. The standard pipeline encodes those unstructured fields with a frozen pretrained model, then applies principal component analysis (PCA) to shrink the high‑dimensional embeddings. PCA selects components based on input variance alone, which can discard information that is highly correlated with the target label. LightTAR addresses this gap by augmenting the PCA representation with a few additional features that are explicitly chosen for their covariance with the target. The result is a richer representation that retains most of the computational efficiency of PCA while being more predictive.
How does LightTAR work?
The algorithm consists of three steps (see Figure 1 in the paper):
- Encode the column – A frozen encoder produces a final‑layer embedding and an intermediate‑layer embedding for each text or image entry.
- Unsupervised reduction – PCA is fitted on the final‑layer embeddings of the training set, keeping a modest number u of components that capture the majority of variance.
- Supervised extraction – Regularized partial least squares (PLS) is applied jointly to the concatenated final‑ and intermediate‑layer vectors and the training labels. PLS returns s directions that maximize covariance with the target while still preserving input variance. These s target‑aware directions are projected onto the original embeddings and appended to the PCA features. The whole process is deterministic, requires no gradient updates, and can be performed on a CPU in seconds, making it compatible with existing tabular pipelines.
How does LightTAR compare to existing pipelines?
The conventional unsupervised pipeline relies solely on PCA, ignoring label information. An alternative is to fine‑tune the encoder on the downstream task (often via LoRA or full‑model updates). While fine‑tuning can improve performance, it incurs significant GPU cost and risks over‑fitting, especially when only a few layers are adapted. LightTAR occupies a middle ground: it injects supervision without altering the encoder weights. Compared to full fine‑tuning, LightTAR:
- Requires no GPU‑based training.
- Adds only a handful of extra features, keeping the overall dimensionality low.
- Avoids the instability of gradient‑based adaptation. In practice, the authors report that LightTAR improves predictive quality for every model they tested, while the total runtime grows only slightly relative to the pure PCA baseline.
What experimental evidence supports LightTAR?
The authors evaluated LightTAR on two benchmark suites:
- MulTaBench – a collection of multimodal tabular tasks where text or image columns carry predictive signal. LightTAR improved the average performance across 21 downstream learners, including tree ensembles (XGBoost, CatBoost), neural tabular models (RealMLP, TabM), and tabular foundation models (TabPFN, TabICLv2, Kumo‑Tabular).
- STRABLE – a control benchmark containing tables with string columns but not specifically selected for multimodal relevance. Even on this harder set, LightTAR delivered modest gains, demonstrating that the method does not rely on cherry‑picked datasets. The paper presents Elo‑rating analyses showing consistent wins over the PCA baseline, as well as runtime measurements indicating that constructing the LightTAR features adds only a few seconds per 1,000 examples. Sensitivity studies reveal that the method is robust to the choice of encoder size and to the regularization strength used in PLS.
Applying LightTAR concepts with Grafy
While Grafy does not yet host a built‑in LightTAR module, creators and researchers can explore the approach using existing tools:
- Grafy Reader (/reader) lets you upload the LightTAR arXiv PDF, ask natural‑language questions about the algorithm, and extract code snippets directly from the appendix.
- Grafy Code (/code) provides an AI‑assisted coding environment where you can prototype the regularized PLS step in Python, experiment with different u and s values, and benchmark the runtime on your own data.
- For quick brainstorming, Grafy Chat (/chat) can generate pseudo‑code for the LightTAR pipeline or suggest suitable pretrained encoders for your modality. These apps let you reproduce the paper’s experiments, adapt the method to new domains, or integrate the target‑aware features into a custom tabular workflow.
Source: https://arxiv.org/abs/2611.17600
Frequently asked questions
Does LightTAR require fine‑tuning the pretrained encoder?
No. LightTAR keeps the encoder frozen and only adds a small set of supervised projection directions, avoiding any gradient‑based fine‑tuning.
How many target‑aware features does LightTAR add to a representation?
The paper reports using a handful of features (denoted s in the algorithm). The exact number is a hyperparameter; the authors found that a small s (e.g., 5–10) already yields measurable gains.
Can LightTAR be used with any tabular learner?
Yes. LightTAR produces a standard numeric feature matrix that can be fed to tree ensembles, neural tabular models, or tabular foundation models without any modification to the downstream learner.
More news
Vision-as-a-Tool paradigm lets coding agents call external visual utilities
A new Vision-as-a-Tool paradigm lets multimodal and text‑only coding agents offload visual reasoning to external utilities.
Meta and NYU Show Encoder Pretraining Unnecessary for Multimodal Models
A joint study from Meta FAIR and NYU trained over 200 multimodal LLMs from scratch.
Edge‑Native Multimodal RAG Achieves Stable Generation on Consumer GPUs
A new arXiv paper shows that a 7B model can run retrieval‑augmented generation on Turing GPUs using NF4 quantization and a decoupled visual pipeline.