Linum trains text-to-image model for $21K, releases weights
Linum says it trained a 2B text-to-image model for $21,038 and released the weights under Apache 2.0. Here is what the run shows and why it matters.
 Source: Hacker News — front page
Linum, a two-person research lab, says it has trained a text-to-image model for about $21,000 in compute and released the model code and weights under Apache 2.0. The release matters because it offers a detailed, low-cost data point for how far a small team says it can push a modern image model without the budget usually associated with frontier training runs.
According to Linum, the model is called Pyramid-JiT, or P-JiT, and the work was published on November 4, 2026 by Sahil Chopra and Manu Chopra, the lab's co-CEOs. The post reached the front page of Hacker News, where it was presented as a research release rather than a commercial product. Linum describes the run as a pressure test and a stepping stone toward larger video models, not as a final image model.
What exactly did Linum release?
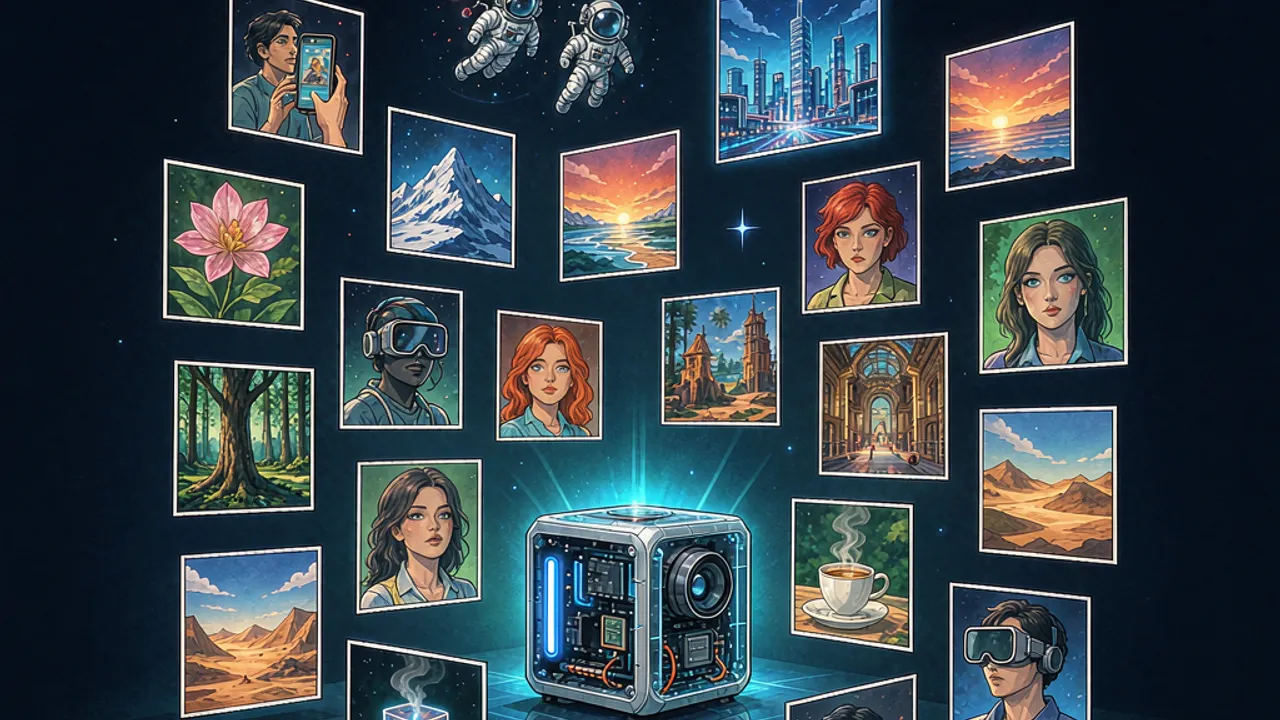
Linum says it released an experimental 2B-parameter text-to-image model, with code and weights available under Apache 2.0. The lab shared 249 sample images generated by the model, grouped by category. According to Linum, the sample set included 57 person images, 42 animal images, 20 building images, 43 product images, 19 landscape images and 68 stylized images.
The authors said they were surprised by the quality relative to the model's size, which prompted them to share the work publicly. That framing is important for readers: Linum presents the release as a proof of concept along the road to its planned Linum v3 video work. It does not present the model as a replacement for larger commercial image systems, and it lists several weaknesses that remain visible in the samples and in the authors' own assessment.
The broader context, according to Linum, is a long-running effort to train generative video models from scratch. The lab says its ultimate ambition is creative tools that make animation more accessible. It argues that current generative video models are too slow, too expensive and insufficiently controllable for iterative storytelling work, where creators need to make, tweak and refine repeatedly.
How much did the training run cost?
Linum puts the total compute cost at $21,038, based on 8,415 H100-hours priced at $2.50 per H100-hour, with restarts included. Pretraining accounted for $20,348 and 8,139 H100-hours, covering 610 million samples at 512-squared resolution followed by 50 million samples at 1024-squared resolution. Post-training accounted for $690 and 276 H100-hours.
That breakdown is central to the story. The headline figure is not a claim that a comparable model can always be built for the same amount, but a reported cost for this specific run, on 64 H100s for pretraining, under the pricing assumption Linum states. Readers comparing the number with other training efforts should note the sample count: about 660 million samples in total across the two resolution stages.
For post-training, Linum says it used a variant of Finite Difference Flow Optimization, known as FDFO, together with JEV-Image and human-in-the-loop judges. The lab describes post-training for diffusion models as a young discipline, and says it plans to discuss its full post-training stack in more detail later. The relatively small post-training spend, compared with pretraining, also shows where most of the reported cost went.
How does Pyramid-JiT work?
Pyramid-JiT is a pixel-space architecture, meaning it works directly with image pixels rather than relying on a separate variational autoencoder to compress images into a latent space first. According to Linum, removing the autoencoder should allow more aggressive compression and faster learning, because the diffusion model can learn a latent representation suited to its own task instead of using a representation built for reconstruction.
The lab says the design represents a 512-squared image using the same number of tokens previously used for a 256-squared image. In practical terms, it uses 32-by-32 patches and 32-by-32 token reduction, compared with 16-by-16 token reduction in Linum v2, which the authors describe as a more standard autoencoder plus diffusion transformer design. Linum says this gives a fourfold reduction in the attention context window, which matters because attention costs grow quadratically with sequence length.
At a higher level, the model uses a frozen Qwen3.5-4B text encoder, with text and image streams passing through refiner blocks before merging into a shared trunk of 22 diffusion transformer blocks. The image patches are projected from a 3,072-dimensional RGB representation into 1,024 dimensions, a three-to-one compression step before the refiner blocks. The model has about 2.18 billion parameters at sampling, rising to about 2.42 billion during training when training-only components are included.
Linum says two ideas helped the architecture converge in fewer samples. One is a noise schedule designed for pixel-space models, intended to help the model learn fine-grained detail. The other is a set of readouts along the trunk that predict lower-resolution versions of the final image, which the authors say strengthens gradient signals in earlier blocks. The training also used a curriculum: the noise distribution started concentrated at high noise for the first 80 million samples so the model could learn basic structure, then widened so it could learn finer detail.
The resolution transition also received specific treatment. When moving from 512-squared to 1024-squared training, Linum says it resumed from the 512-squared exponential moving average weights, started a fresh optimizer, doubled the noise scale, used rotary position embedding interpolation and delayed the start of the new moving average so the model could adjust to the higher resolution first.
What are the model's limitations?
Linum is explicit that the model cannot generate rendered text. It says the training data excluded images of rendered text, including infographics, PDFs, book pages and slides, because the lab does not consider that data useful for its animation goals. As a result, the model cannot reliably write text or generate posters, a limitation that will matter for anyone expecting a general-purpose image tool.
The authors also list weaknesses linked to the model's size. They say a 2B-parameter diffusion transformer with a 4B text encoder struggles in areas such as full-body generation, images with many entities, multi-person interactions and world knowledge. They note that the model can sometimes produce correct results in these categories, but that failures remain common enough to be a concern. They suggest that a larger model, for example around 7B parameters, and further post-training could reduce these problems, while making clear that this is an expectation rather than a demonstrated result.
Those caveats help explain the release's experimental status. The value of the work, as presented by Linum, lies less in claiming state-of-the-art image quality and more in showing what a pixel-space design, aggressive token reduction and a staged training regime can achieve at a reported cost of roughly $21,000.
What does this mean for creators and developers?
For creators, the release is a reminder that image models are still shaped heavily by training data and scale. A model filtered away from text-heavy images will not serve poster, document or infographic workflows well, even if it performs well on people, animals, products, landscapes and stylized scenes. For developers, the more transferable lesson is architectural: reducing the attention context window can change the economics of both training and inference, especially for future video models where sequence length is even more demanding.
Readers who want to explore image generation hands-on can use Grafy's Creator app to generate images and video from a prompt or a photo, and compare outputs across different models and styles. That is not the same as running Pyramid-JiT itself, and Grafy does not claim to offer that specific model, but it gives creators a practical way to test prompts, inspect failures and learn where current image models struggle. The branching workflow in Grafy's Graph app can also help when a reader wants to keep several prompt variations and outputs side by side instead of losing earlier attempts.
For researchers and developers who want to study the approach, Grafy's Reader app is a more direct fit for reading and questioning papers and PDFs with AI, while Grafy Chat can be used to compare explanations from multiple models side by side. Those tools do not reproduce Linum's training run, but they can help a reader work through the architecture, training settings and limitations described in the original post.
Frequently asked questions
How much did Linum say the full training run cost?
Linum says the full run cost $21,038 in compute. Pretraining cost $20,348 for 8,139 H100-hours, and post-training cost $690 for 276 H100-hours. Together, that is 8,415 H100-hours priced at $2.50 per hour, including restarts.
What resolution stages did Pyramid-JiT train at?
Linum says the model trained first at 512-squared resolution, then at 1024-squared resolution. The 512-squared stage covered about 610 million samples, and the 1024-squared stage covered about 50 million samples, for roughly 660 million samples in total.
Can the released model generate images with rendered text?
No. Linum says the training data excluded rendered text, including infographics, PDFs, book pages and slides. Because of that filtering, the authors say the model cannot write text or generate posters, even though it can sometimes handle other categories.
Source: Linum Field Notes via Hacker News
More news
MIT used GPT-6 Astra to edit Qwen weights, lifting math score sixfold
MIT researchers used GPT-6 Astra to edit Qwen's weights directly, lifting its MATH-500 score sixfold. What the results mean — and their limits.
Grimes to star in AI movie Gods Don't Give Gifts
Grimes will star in Gods Don't Give Gifts, an AI sci-fi anthology from Fable due December 4, billed as the first AI film for theatres. Why it matters.
OpenAI launches GPT-6 Cyber, a model better at staying in bounds
OpenAI says GPT-6 Cyber finds vulnerabilities better and went out of bounds under 1% in testing. What its Critical rating and scores mean for defenders.