LMEG-Doc Introduces Layout‑Grounded Evidence Graphs for Multimodal Long‑Document Retrieval
A new framework called LMEG‑Doc builds layout‑aware evidence graphs to improve retrieval from long.
 Source: Grafy Research Lab
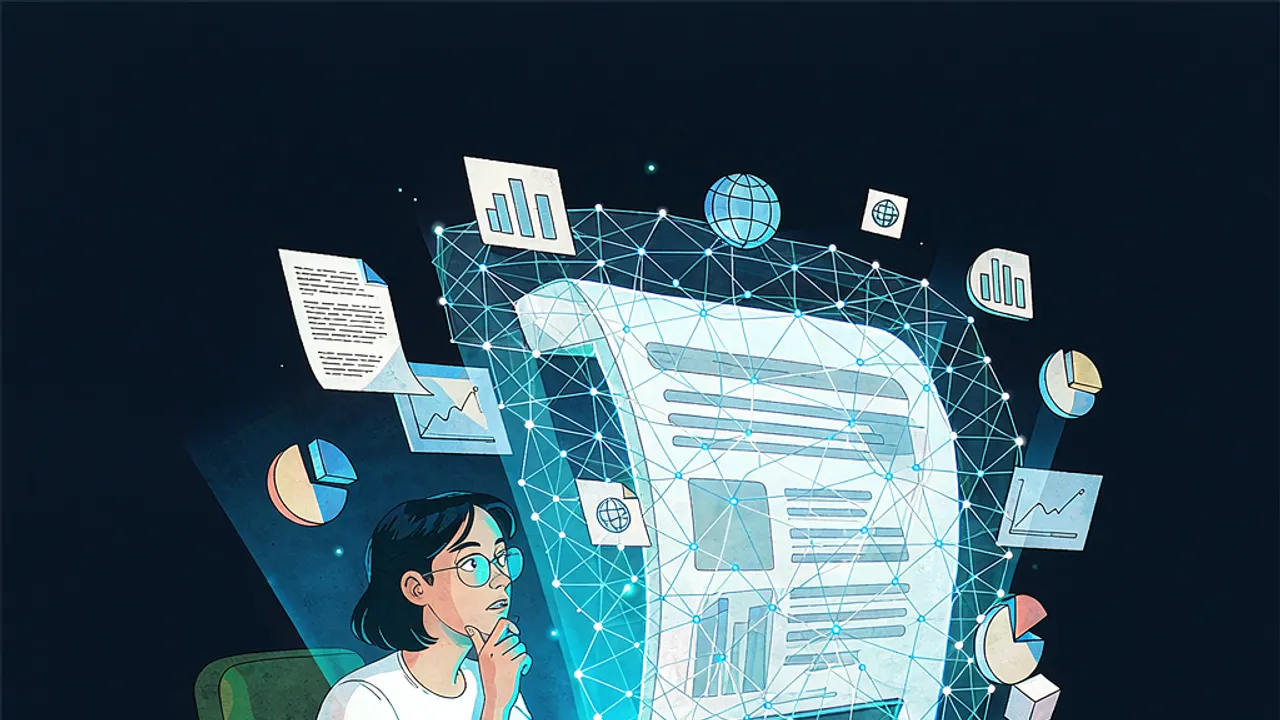
Retrieving the right pieces of information from long, multimodal documents—papers that mix text, tables, figures, and even video—has long been a bottleneck for AI‑assisted research. The newly posted pre‑print LMEG‑Doc: Layout‑Grounded Multi‑View Evidence Graphs for Multimodal Long‑Document Retrieval proposes a graph‑based approach that explicitly models the layout and cross‑modal relationships among document elements, aiming to surface the most relevant evidence for a given query.
Why is multimodal long‑document retrieval difficult?
Traditional retrieval pipelines treat each document element (a paragraph, a figure caption, a table) as an isolated vector and rank them by similarity to the query. When the answer to a question depends on several complementary pieces—say, a chart that visualizes data described in a nearby paragraph—those isolated scores often miss the connection. According to the paper’s abstract, this leads to “relevant figures and tables receiving low retrieval scores even when they contain essential information.” For creators, developers, and researchers who rely on precise evidence extraction, such oversights can waste time and produce incomplete analyses.
What do existing methods overlook?
Current methods focus primarily on individual similarity, ignoring the structural cues that PDFs and other document formats provide. Layout information—page numbers, column positions, proximity of a caption to its figure—offers a natural signal about which elements belong together. Moreover, multimodal cues such as visual similarity between a plot and a textual description are rarely combined in a single retrieval model. The authors of LMEG‑Doc argue that without a unified view of these relationships, retrieval systems cannot reliably surface the full set of evidence needed to answer complex questions.
How does LMEG‑Doc address the gap?
LMEG‑Doc (Layout‑Grounded Multi‑View Evidence Graph) constructs a multi‑view graph where nodes represent document fragments of any modality—text blocks, tables, images, or video snippets. Edges encode layout‑derived relationships (e.g., “same page,” “adjacent columns”) as well as semantic cross‑modal links (e.g., “caption describes figure”). By grounding the graph in the document’s physical layout, the framework can propagate relevance scores across connected nodes, allowing a low‑scoring figure to be boosted if its neighboring text is highly relevant. The paper describes the graph as “layout‑grounded,” meaning that the spatial arrangement of elements directly informs the edge creation process.
What practical benefits could creators and developers see?
For anyone building AI‑powered research assistants, literature‑review tools, or knowledge‑base extractors, LMEG‑Doc promises more faithful evidence retrieval. A developer could integrate the graph into a downstream pipeline that assembles a concise answer, complete with the supporting figure and its caption, rather than returning a disjointed paragraph. Researchers could query a large PDF collection and receive a structured set of evidence that respects the original document’s layout, reducing the manual effort required to locate the right figure or table. In addition, the graph‑based representation lends itself to visual debugging: developers can inspect which layout edges contributed to a final ranking, helping to fine‑tune retrieval heuristics.
How can Grafy users experiment with LMEG‑Doc concepts?
While Grafy does not yet host a built‑in LMEG‑Doc engine, the framework aligns closely with two existing Grafy apps. Grafy Reader (/reader) lets users upload PDFs and query them with AI, automatically extracting text and metadata. By exporting the extracted layout metadata (page numbers, bounding boxes) from Reader, a developer can construct a simple evidence graph using the Grafy Code studio (/code) to run Python libraries such as NetworkX. The resulting graph can then be visualized in Grafy Graph (/graph), where each node is a document fragment and edges illustrate layout relationships. This hands‑on workflow lets creators prototype the core idea of layout‑grounded relevance without waiting for a dedicated model.
What next steps are suggested by the authors?
The pre‑print is labeled as “Work in Progress,” indicating that the authors intend to evaluate LMEG‑Doc on benchmark datasets of multimodal long documents. Expected future work includes measuring retrieval accuracy against baseline similarity‑only models, exploring different edge‑weighting schemes, and possibly integrating large‑language‑model encoders that can ingest both visual and textual inputs. For the Grafy community, these upcoming experiments present an opportunity to contribute data, test alternative graph constructions, or even fine‑tune open‑source multimodal encoders within the Grafy Chat environment (/chat).
Source: https://arxiv.org/abs/2611.18901
Frequently asked questions
How does LMEG‑Doc differ from traditional similarity‑based retrieval?
LMEG‑Doc builds a graph that connects document fragments using layout cues (page, column, proximity) and cross‑modal semantics. Relevance scores are then propagated through this graph, allowing evidence that is spatially or semantically linked to a high‑scoring node to be boosted, whereas traditional methods rank each fragment in isolation.
Can I use LMEG‑Doc with Grafy without writing code?
Grafy does not yet include a turnkey LMEG‑Doc implementation. However, you can extract a PDF’s layout information with Reader, then experiment with graph construction and visualization using Code and Graph. This low‑code approach lets you explore the core idea of layout‑grounded evidence graphs.
What kinds of documents benefit most from a layout‑grounded approach?
Documents that combine multiple modalities—research papers, technical manuals, patents, or reports with embedded charts and tables—are prime candidates. In such files, the answer to a query often depends on a combination of text, figures, and tables that are linked by their visual placement on the page.
More news
Study Reveals Temporal Contamination Skews Language Model Forecasts of Central‑Bank Data
Researchers measured how language models leak future information when reading past FOMC statements, showing a hidden source of error for economic forecasting.
Jetriever Replaces Similarity Search with Utility Scoring for Agent Memory
A new retrieval method called Jetriever ranks memories by usefulness instead of similarity.
Mechanistic Interpretability Finds Partial Clues to Web Agent Hallucinations
A new arXiv paper shows that linear probes can predict and steer away web‑agent hallucinations.