Multimodal LLM System Automates Extraction from Handwritten Clinical Assessments
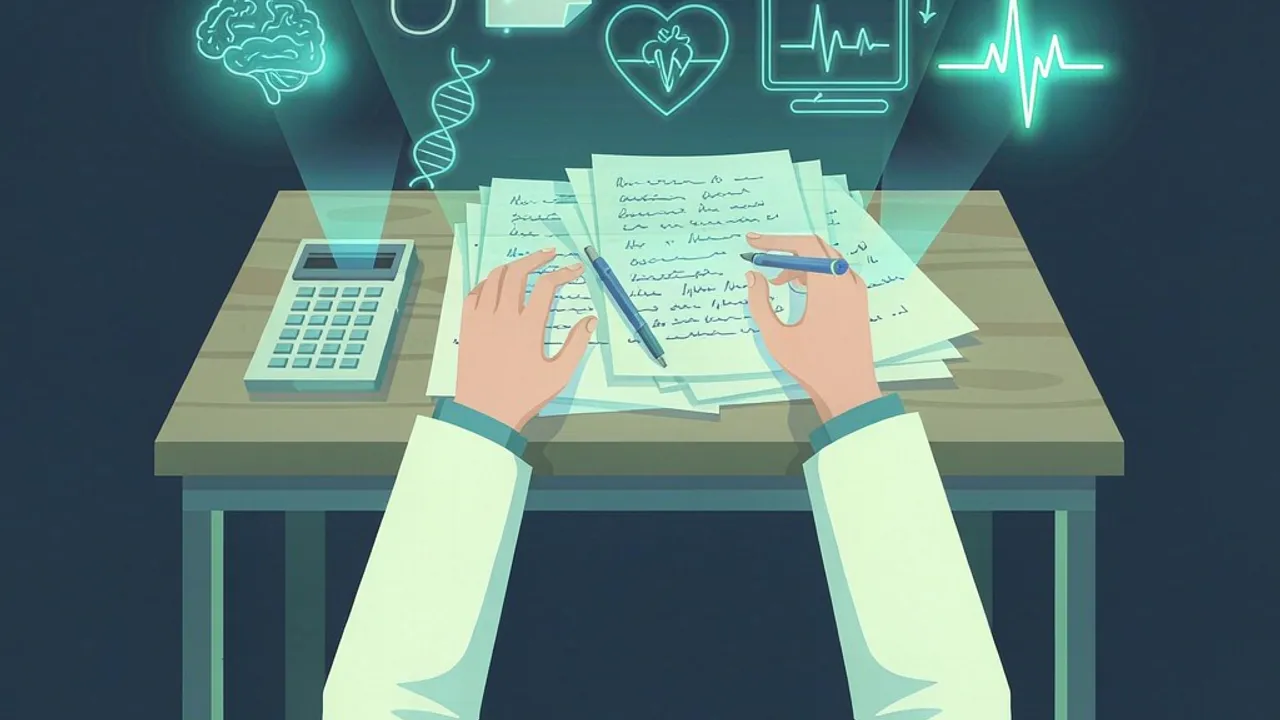
Researchers unveiled a modular multimodal LLM system that classifies and extracts scores from scanned cognitive and behavioral assessment forms.
 Source: Grafy Research Lab
What problem does the new system address?
Paper‑based cognitive and behavioral assessments such as the MMSE, MoCA, Mini‑Cog, and the NICHQ Vanderbilt are still widely used in clinical practice. Handwritten entries and scanning artifacts make large‑scale digitisation labor‑intensive and error‑prone. The authors of the study note that existing manual pipelines are costly and slow, limiting the speed at which structured data can feed clinical decision support tools.
How is the system architected?
The proposed solution is a two‑stage, modular pipeline that leverages multimodal large language models (LLMs) with a human‑in‑the‑loop safeguard.
- Form classifier – a multimodal LLM receives the scanned image of a page and predicts which assessment form it belongs to (e.g., MMSE vs. MoCA).
- Score extractor – a second LLM, conditioned on the identified form type, parses the image to locate fields, reads handwritten numbers or drawings, and writes the results into a predefined JSON schema.
Both modules run side‑by‑side on the same model family but are prompted differently to specialise in classification versus extraction. When the two LLMs produce conflicting outputs, a dual‑model validation step flags the page for human review. This selective review limits manual effort to only the most ambiguous cases.
How well does it perform on real assessments?
The authors report end‑to‑end accuracy of for the suite of cognitive assessments, with most individual form types exceeding . For the NICHQ Vanderbilt assessment, overall accuracy reached , and every form type scored above . Introducing the human‑in‑the‑loop mechanism boosted the cognitive‑assessment accuracy to while cutting the amount of manual work by .
A deeper look at the Mini‑Cog Clock Drawing task revealed that of extraction errors stemmed from ambiguous drawings. In those cases the LLMs still produced “reasonable” interpretations, suggesting that the model can handle a degree of visual uncertainty.
What practical impact does it have for clinicians and researchers?
Compared with traditional manual data entry, the system shortens processing time by a factor of ten to twenty and reduces costs by more than twelve times, according to the paper. The modular design means new assessment forms can be added by training a fresh classifier and extractor pair, without re‑engineering the whole pipeline. For health systems that still rely on pen‑and‑paper tests, the approach offers a scalable path to digitise legacy records and unlock them for analytics, research, and real‑time decision support.
Using Grafy to experiment with multimodal extraction
Grafy’s Reader app lets users upload PDFs or scanned images and interact with them using multimodal LLMs. While Grafy does not yet provide a turnkey version of the exact pipeline described in the paper, creators can prototype similar workflows:
- Upload a batch of scanned assessment pages to Reader.
- Prompt the built‑in multimodal model to classify the form type (e.g., “Identify which cognitive test this page belongs to”).
- Follow up with a second prompt that asks the model to extract specific fields into a JSON snippet.
- Use the Graph app to chain these prompts, capture model responses, and flag disagreements for manual review.
- For developers, the Code studio can be used to script the dual‑model validation logic and integrate Grafy’s API with external storage or EHR systems.
By leveraging Grafy’s multimodal models side‑by‑side, users can explore the same design principles—modular prompting, schema‑driven output, and selective human oversight—without building a custom stack from scratch.
Frequently asked questions
How does the dual‑model validation reduce manual effort?
When the classifier and extractor produce different predictions for a page, the system routes that page to a human annotator. Because disagreements are relatively rare (about 36% of cases after the first pass), reviewers only need to handle the most ambiguous inputs, cutting overall manual work by roughly .
Can the system be extended to new paper forms?
Yes. The architecture is modular: a new form requires training (or prompting) a classifier to recognise its layout and an extractor tuned to its specific fields. The authors emphasize that this plug‑and‑play approach enables seamless expansion to additional assessments.
What limitations remain for handwriting recognition?
The study found that ambiguous drawings, especially in the Mini‑Cog Clock Drawing task, still account for the majority of errors. While the LLM can often produce plausible readings, true accuracy depends on the clarity of the handwriting or drawing, and extreme illegibility may still need human interpretation.
Source: https://arxiv.org/abs/2611.22252
More news

Anthropic prices IPO at $83 a share, valuing the AI firm at $1.5 trillion
Anthropic filed its S‑1 on Nov 18, setting the IPO price at $83 per share and a $1.5 trillion valuation.

Learned Multigranular Memory Retrieval Boosts Small LLM QA Performance
A new paper introduces LMMR, a learned multigranular memory retrieval method that trims input to under 400 tokens while raising F1 scores on HotpotQA and other.
Just‑Enough Exploration Tuning Cuts Tool Calls in Code‑Repo QA Agents
Researchers introduce JET, a fine‑tuning approach that trims unnecessary tool calls in repository‑level QA agents while keeping answer quality high.