OmniDebias introduces bias‑centric fairness for omni‑modal LLMs
Researchers unveil OmniDebias, a bias‑centric method that unifies fairness across attributes and modalities in omni‑modal large language models.
 Source: Grafy Research Lab
OmniDebias, a new technique for reducing social bias in omni‑modal large language models (OLLMs), was presented by Runqi Lin, Suqin Yuan, Zihao Fu and Chris Russell in a pre‑print released on 18 Nov 2026. The work matters because OLLMs power a growing number of applications that combine text, image and video, and existing fairness tools struggle to keep up with the diverse ways stereotypes can appear across these modalities.
What is OmniDebias and why does it matter?
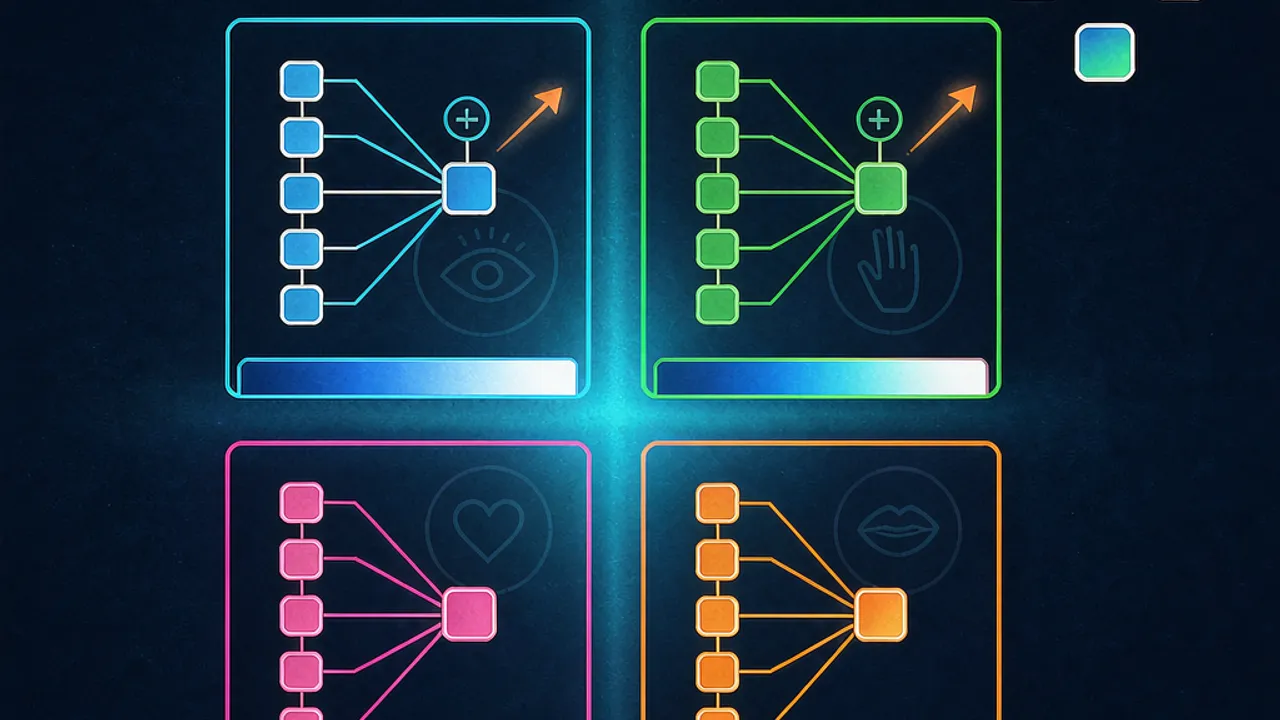
OmniDebias is one of the first methods designed specifically for omni‑modal models, which process and generate content across several media types in a shared embedding space. According to the authors, the method reframes fairness as a bias‑centric problem: instead of imposing separate constraints for each demographic attribute (gender, race, etc.) and each modality, it extracts a single, shared bias representation that can be mitigated globally. This approach promises scalable fairness that can also address attributes that were not seen during training, a scenario that attribute‑centric methods cannot handle well.
How does the bias‑centric formulation differ from attribute‑centric methods?
Traditional approaches fall into three families – prompt‑based, post‑hoc editing (PE) and fine‑tuning (FT) – but all require a distinct fairness target for every attribute‑modality pair. As the number of attributes grows, the models must satisfy many competing objectives, leading to interference and limited generalisation. The authors illustrate this contrast in Figure 1 of their paper: attribute‑centric pipelines replace biased directions with predefined “unbiased” ones for each case, while the bias‑centric pipeline isolates a common bias direction that is removed irrespective of the specific attribute. This unified target eliminates the need for attribute‑specific priors and enables the model to handle out‑of‑distribution (OOD) attributes.
What techniques does OmniDebias use to extract and neutralise bias?
The method consists of three steps:
- Bias Disentanglement – The authors exploit activation inconsistencies when swapping an attribute class across different semantic contexts. For example, the activation shift between male CEO and female CEO should be similar to the shift between male nurse and female nurse if the model were unbiased. In practice the shifts differ, revealing entangled stereotypes. These deviations are used to separate bias from legitimate knowledge.
- Bias Unification – After extracting bias vectors for several attributes, the method consolidates them into a shared representation. This unified bias captures common stereotypical patterns and can be applied to attributes that were not part of the original extraction.
- OmniDebias Intervention – The unified bias can be incorporated in two ways. In a post‑hoc editing setting, model parameters are projected onto the orthogonal complement of the bias direction at inference time, following the strategy of prior PE work. In a fine‑tuning setting, the residual bias is estimated on‑the‑fly from activations and penalised with a regularisation term, without requiring label supervision.
Both interventions rely only on internal activations, meaning they can be applied to frozen models or during continued training.
How effective is OmniDebias in experiments?
The authors report extensive experiments on several OLLMs, including the Janus and BAGEL families, covering text‑to‑text, text‑to‑image and image‑to‑text tasks. Their evaluation measures standard fairness metrics (e.g., demographic parity) across a suite of seen attributes (gender, ethnicity) and OOD attributes (age, nationality). Results show consistent improvements in fairness scores for both PE and FT variants, while generation quality – measured by BLEU, CLIPScore and human judgments – remains largely unchanged. An ablation study confirms that both the disentanglement step and the unification step contribute to the gains; removing either component degrades fairness performance.
Applying the ideas with Grafy
While Grafy does not yet ship a built‑in OmniDebias tool, the principles can be explored using existing apps:
- Grafy Reader (/reader) lets you upload the arXiv PDF and ask the model to summarise the methodology, compare bias‑centric versus attribute‑centric approaches, or extract the activation‑inconsistency examples used in the paper.
- Grafy Chat (/chat) enables you to experiment with prompt‑based fairness techniques on a multimodal model hosted in Grafy’s model zoo, and to test post‑hoc editing style interventions by requesting the model to re‑rank its outputs after a bias‑direction projection.
- Grafy Graph (/graph) can visualise the branching workflow of bias extraction, unification and intervention, helping developers prototype a custom pipeline that mirrors OmniDebias steps.
By combining these apps, creators and researchers can prototype their own bias‑centric pipelines, compare results against the published OmniDebias baselines, and iterate quickly without leaving the Grafy workspace.
Source: https://arxiv.org/abs/2611.22889
Frequently asked questions
How does bias disentanglement identify stereotypical activations?
The method looks at the activation shift caused by swapping an attribute (e.g., gender) in different contexts (e.g., occupations). If the model were unbiased, the shift would be consistent across contexts. Differences in these shifts signal entangled bias, which can then be isolated and removed.
Can OmniDebias be used with frozen models that cannot be fine‑tuned?
Yes. The authors provide a post‑hoc editing variant that projects model parameters onto the orthogonal complement of the unified bias direction at inference time, allowing bias mitigation without modifying the underlying weights.
Does removing the unified bias hurt the model’s performance on the original task?
According to the experimental results, fairness improves across all tested attributes and modalities while core performance metrics such as BLEU or CLIPScore stay within the original variance range, indicating that utility is largely preserved.
More news
FlashAttention beats kernelized attention; LARA++ closes quality gap
A NeurIPS‑2026 paper benchmarks kernelized attention against FlashAttention, showing lower memory use and faster training.
Token Commitment Introduced as a Steering Lever for Masked Diffusion Models
Researchers unveil counterfactual target‑aware commitment and adaptive budgets, turning token commitment into a controllable surface for masked diffusion.
TempQuant lets quantized LLMs regain accuracy by learning adaptive temperatures
Researchers introduce TempQuant, a method that learns temperature and top‑p settings for quantized language models, boosting performance without extra labels.