SIMQ Introduces a Single Graph Index to Speed Multi‑Vector Retrieval
A new framework called SIMQ builds a single graph index for token‑level vectors, cutting the cost of multi‑vector retrieval while keeping stable recall.
 Source: Grafy Research Lab
What is SIMQ and why does it matter?
The research team led by Yifan Lu and colleagues released SIMQ – Single Graph Index for Multi‑Vector Query – in a pre‑print on arXiv on 18 November 2026. According to the paper, SIMQ proposes a unified graph‑based index that can serve the token‑level vector representations used by state‑of‑the‑art multi‑vector retrieval models such as ColBERT. The importance of this work lies in its promise to dramatically lower the computational overhead that has kept these powerful models out of large‑scale production environments.
How do current multi‑vector retrieval models work and what are their limits?
Models like ColBERT break a document into a set of token embeddings, often hundreds per passage, and compare a query against every token vector using a MaxSim scoring rule. This approach yields top‑tier relevance but requires an exhaustive similarity computation for each query, a cost that scales linearly with both the size of the corpus and the number of tokens per document. Existing approximate solutions fall into two families:
- Centroid interaction matrix methods – They compute a dense interaction matrix between query centroids and document centroids at query time. This still demands a full matrix multiplication for every request and depends on GPU‑accelerated clustering to stay tractable.
- Data‑oblivious compression techniques – These compress token vectors without regard to the data distribution. While they reduce storage, the authors note that recall becomes unstable, often requiring repeated compensation steps that erode the speed gains.
Both families therefore face a trade‑off between speed and retrieval quality, limiting the practical deployment of multi‑vector systems on corpora larger than a few hundred million passages.
What is the core idea behind the Single Graph Index?
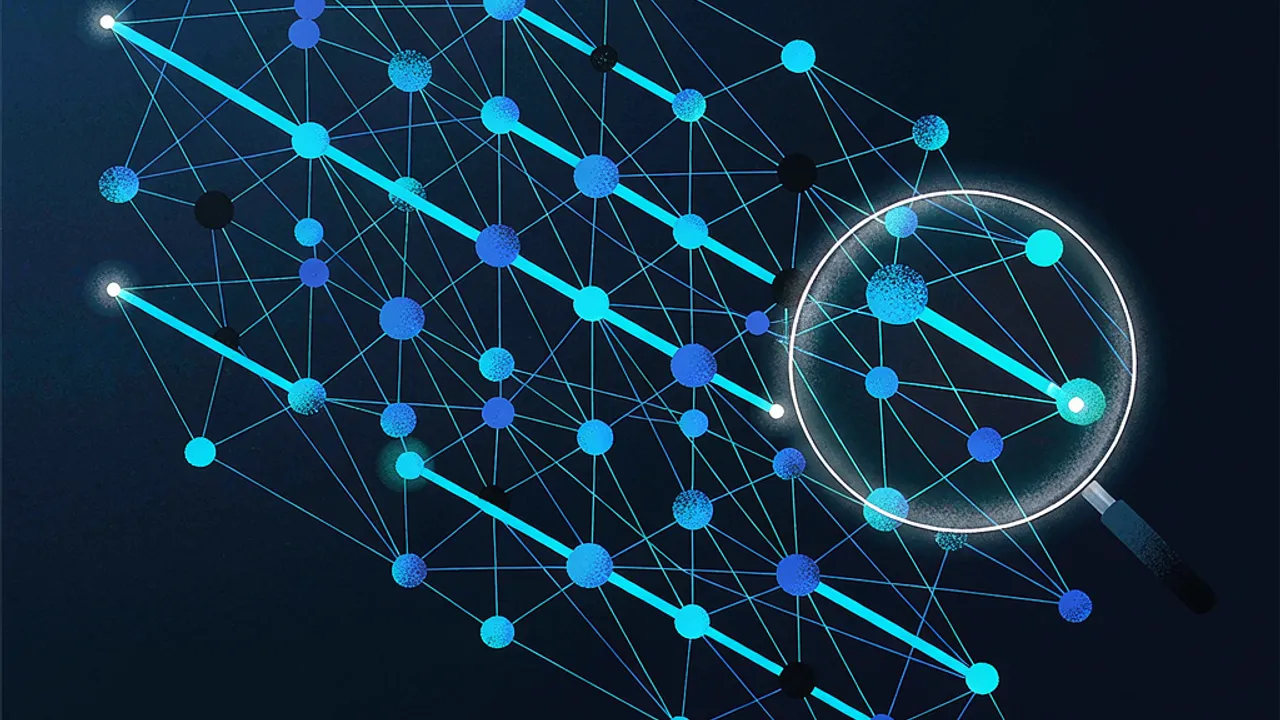
SIMQ builds a single, global graph that encodes the relationships among all token‑level vectors across the entire collection. Rather than constructing a fresh interaction matrix for each query, the graph enables a single‑pass traversal that directly surfaces the most relevant token clusters. In essence, the index treats each token vector as a node and connects it to its nearest neighbours, forming a structure similar to a k‑nearest‑neighbour (k‑NN) graph but optimized for the multi‑vector retrieval scenario.
During query time, the system maps the query vector onto the graph and follows the pre‑computed edges to locate high‑scoring token groups. Because the graph is built once offline, the per‑query work collapses to a lightweight graph walk, eliminating the need for costly matrix multiplications or on‑the‑fly clustering.
How does SIMQ improve recall and efficiency compared to prior approaches?
The authors report that SIMQ achieves stable recall comparable to exact MaxSim scoring while avoiding the erratic performance seen in data‑oblivious compression methods. By preserving the geometric relationships among token vectors in the graph, the index maintains the fine‑grained similarity information that is essential for high‑quality ranking.
From an efficiency perspective, the graph‑based search reduces the computational complexity from roughly – where is the number of documents and the average token count – to a sub‑linear traversal that depends on the graph’s degree and the depth of the walk. This translates into lower GPU utilization, smaller latency per query, and the ability to scale to corpora that were previously infeasible for multi‑vector models.
How can developers experiment with SIMQ using Grafy?
Grafy provides several tools that make it straightforward to explore the concepts behind SIMQ:
- Reader – Load the arXiv PDF directly into Grafy’s AI‑enhanced reading interface to ask detailed questions about the methodology, view extracted graphs, or get a summary of the experiments. Access it at /reader.
- Graph – Visualize the token‑level graph that SIMQ constructs. By importing the adjacency data (often provided as a CSV or JSON in the paper’s supplemental material), you can experiment with different traversal strategies and see how query vectors propagate through the network. Start a new project at /graph.
- Code – Implement a prototype of the SIMQ indexing pipeline using Grafy’s AI‑assisted coding studio. The platform lets you write, run, and debug Python code that builds a k‑NN graph, integrates with existing ColBERT embeddings, and benchmarks query latency. Begin coding at /code.
These apps let creators, developers, and researchers move from reading the paper to building a working proof‑of‑concept without leaving the Grafy workspace.
What are the next steps for the research community?
While the pre‑print demonstrates promising results on standard retrieval benchmarks, the authors acknowledge that further work is needed to evaluate SIMQ on truly web‑scale corpora and to integrate it with other multi‑modal retrieval pipelines. Open‑source release of the indexing code, along with a benchmark suite, would enable broader adoption and comparative studies against alternative approximation methods.
In the meantime, the Grafy community can contribute by reproducing the experiments, sharing performance metrics in the public gallery, and extending the graph construction to incorporate additional modalities such as image embeddings or audio fingerprints.
Frequently asked questions
Does SIMQ replace existing ColBERT pipelines or work alongside them?
SIMQ is designed as a drop‑in replacement for the indexing and retrieval stage of ColBERT‑style systems. It keeps the same token‑level embeddings, so the front‑end query encoding remains unchanged; only the backend index structure is swapped.
What hardware is required to build and query the SIMQ graph?
The offline graph construction benefits from a GPU for fast nearest‑neighbour computation, but the resulting index can be queried on CPU‑only servers. Because query latency depends on graph traversal rather than dense matrix multiplication, modest hardware can handle large collections.
Is the SIMQ implementation publicly available?
The authors intend to release the code alongside the arXiv paper. Until the official repository appears, interested users can follow the methodology described in the paper and implement their own version using Grafy’s Code studio.
Source: Grafy Research Lab — SIMQ: A Single Graph-based Index for Multi-Vector Query
More news

Anthropic prices IPO at $83 a share, valuing the AI firm at $1.5 trillion
Anthropic filed its S‑1 on Nov 18, setting the IPO price at $83 per share and a $1.5 trillion valuation.

Learned Multigranular Memory Retrieval Boosts Small LLM QA Performance
A new paper introduces LMMR, a learned multigranular memory retrieval method that trims input to under 400 tokens while raising F1 scores on HotpotQA and other.
Just‑Enough Exploration Tuning Cuts Tool Calls in Code‑Repo QA Agents
Researchers introduce JET, a fine‑tuning approach that trims unnecessary tool calls in repository‑level QA agents while keeping answer quality high.