TrustedRouter launches three encrypted fusion model presets
TrustedRouter launched three encrypted fusion presets that send a prompt to several models or one, with claimed savings near 60% and open questions.
 Source: VentureBeat — AI
TrustedRouter has added three encrypted “fusion” presets to its existing API, each of which either sends one prompt to a panel of models and synthesises a single answer or picks one model before generating, according to VentureBeat. The release matters because it packages multi-model routing as named, versioned products with published component rates, rather than leaving every team to wire up panels, judges and synthesizers itself.
What did TrustedRouter launch, and where do developers call it?
The three presets are Prometheus 4.0, Liberty 4.0 and Polyphemus 1.0, reachable through the New York Token Exchange with model IDs beginning nyte/, VentureBeat reports. Lore Hex Corp operates both services: TrustedRouter is the gateway that connects applications to models and hosting providers, while NYTE sells AI processing on demand and takes advance capacity reservations. The two API addresses share keys, account balances and routing behaviour, so the same preset can be called with either the nyte/ or trustedrouter/ prefix.
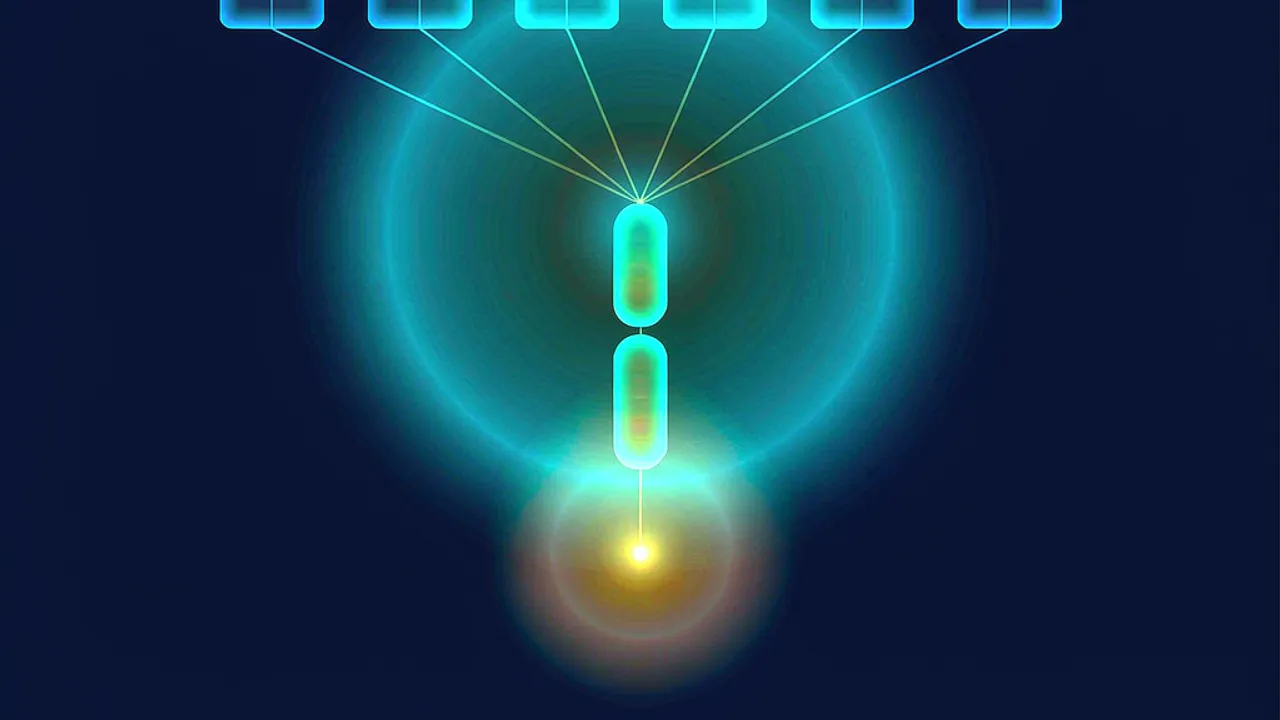
Prometheus 4.0 is the open-weight panel. Its published lineup is Xiaomi’s MiMo-V2.6-Pro, Z.ai’s GLM 5.3, Moonshot AI’s Kimi K3, DeepSeek V4.1 Flash, MiniMax M3 and Alibaba’s Qwen 3.8, with a one-million-token context window listed for the preset. The nyte/prometheus alias follows the latest version, while nyte/prometheus-4.0 pins this release. Liberty 4.0 draws only on U.S. developers: NVIDIA’s Nemotron 3 Ultra, Reflection AI’s Beam and Meta’s Muse Spark Open.
How do Prometheus 4.0 and Liberty 4.0 combine answers?
Both run their panellists in parallel and then make two further calls: a judge evaluates the answers and a synthesizer produces the final response, according to TrustedRouter. A full Prometheus request therefore uses eight model calls, and a full Liberty request uses five.
In Liberty, the Meta model does the combining, with Beam taking over synthesis if the Meta model is unavailable; if a panellist fails to answer, Liberty proceeds with the responses it has. The point is that a missed source or a wrong turn in a calculation can be caught against the other answers — but the synthesizer has to work out which answer is better supported, and if several panellists repeat the same mistake, agreement gives it little reason to overrule them. TrustedRouter has not said which model synthesises Prometheus’s production answers, how many panellists must finish before synthesis begins, or how the advertised one-million-token limit applies when component models have different limits.
What does Polyphemus 1.0 do differently?
Polyphemus decides before it generates. A selector reads the request, chooses one model, and that model answers in a single call, over the Responses API with a 65,536-token context window. It costs the chosen model’s normal charges plus $0.05 per million estimated selector input tokens; if the selector fails, the general TrustedRouter auto route handles the request and the selector fee drops away. A session can be resumed by reusing a session ID and resending the conversation history on each turn, which improves the chances of reusing cached input, and it expires after an hour of inactivity. The preset is documented with standard privacy. The selector’s eligible model pool, its decision criteria and its performance against a fixed-model baseline are all still open questions.
How private are the “confidential” routes?
All three presets use an encrypted connection to TrustedRouter’s gateway, but provider-side confidential processing is opt-in for Liberty 4.0 and Prometheus 4.0, and Polyphemus 1.0 uses standard privacy. On an eligible confidential route, a prompt stays encrypted until it reaches verified hardware at the provider running the model, and is decrypted inside a protected environment designed to keep it out of that provider’s operators’ hands. The protection depends on the route and the caller’s privacy settings.
Founder and CEO Joseph Perla told VentureBeat that the system uses confidential computing on NVIDIA GPUs to encrypt requests while they are being processed, which he says keeps infrastructure providers and the exchange itself from reading customers’ sensitive information. He also frames verification as a buyer protection: confirming which model actually served a request reduces the risk of paying for an expensive model and unknowingly receiving a cheaper one. “Everyone should use a router because no provider, no one provider is 100% reliable,” Perla said.
What do they cost, and how do they compare with OpenRouter, GitHub and Sakana?
TrustedRouter’s catalogue lists component-route rates of roughly $0.01 to $1.48 per million input tokens and $0.13 to $7.39 per million output tokens for Prometheus 4.0, and roughly $0.42 to $1.32 for input and $1.27 to $4.48 for output for Liberty 4.0. Those rates describe parts of a request, not the whole bill. The standard markup on prepaid text is 5.5% with no subscription; managed prepaid requests that opt into a signed inference receipt carry a 12% total service fee.
Against Claude Fable 5.1, TrustedRouter puts Fable at 2.3 to 2.9 times Liberty’s cost per request (roughly 60% savings for Liberty) and 2.5 to 3 times Prometheus’s (roughly 60% to 65%). For Polyphemus it estimates about 60% lower cost when the selector chooses Claude Opus 5.5 and about 80% lower when it chooses GPT-6.1 Sol. These are relative figures: underlying dollar costs, tasks, quality and latency measurements are not published, and it is unclear whether the Polyphemus estimates include the selector fee.
The most concrete benchmark result for the Prometheus line comes from an earlier version. In its July tests, TrustedRouter reports Prometheus 2.0 scoring 77.4 across all 100 tasks in Perplexity’s DRACO deep-research benchmark, against single-model reference scores of 65.3 for Claude Fable 5, 63.3 for GPT-5.5 and 60.3 for Claude Opus 4.8.
Rivals are converging on the same idea from different angles. GitHub Copilot Fusion chooses inside the coding agent, using one model, escalating after a quality check, or having one model review another’s draft, with enterprise administrators controlling eligible models; Artificial Analysis measured Fusion Max at an average $5.59 per coding task against $11.42 for Claude Code running Claude Opus 5.5 at its Max setting, with a two-point gap on the Coding Agent Index. Sakana AI’s Fugu Max and Fugu Ultra v2 also hide multi-model coordination behind an API. OpenRouter Fusion is the closest match to the panel design, with a documented pipeline that sends a prompt to several models in parallel, has a judge compare their work and passes that to the model that writes the answer — the difference is that developers configure the panel and judge themselves, while TrustedRouter ships named presets with a versioned ID.
How can you try the panel-and-judge pattern in Grafy?
Grafy does not resell TrustedRouter’s presets, but the pattern is reproducible in the workspace. Grafy Chat runs many cloud models side by side — OpenRouter, Vertex AI, fal and Replicate among them — so one prompt can go to several models and the answers compared directly, which is the manual version of what Prometheus and Liberty automate. The council of models walkthrough covers asking several models at once and letting a judge pick the best answer. For the Polyphemus case, spending the cheapest model that can still answer, see lowest-cost model routing. And because Graph keeps prompts, outputs and model history in a branching structure, it is a practical place to record which panellist produced which answer and which one the judge chose.
Frequently asked questions
Does Prometheus 4.0 combine six open-weight models into a single answer?
Yes. According to VentureBeat, Prometheus 4.0 sends a prompt to six open-weight models in parallel — MiMo-V2.6-Pro, GLM 5.3, Kimi K3, DeepSeek V4.1 Flash, MiniMax M3 and Qwen 3.8 — then makes a judge call and a synthesizer call, for eight model calls in a full request. TrustedRouter has not named the model that synthesises production answers.
Does Polyphemus 1.0 charge a selector fee on top of the model’s token charges?
Yes. TrustedRouter prices the selector at $0.05 per million estimated selector input tokens, added to the chosen model’s normal charges. That fee disappears if the selector fails and the general TrustedRouter auto route handles the request instead. Whether the company’s headline Polyphemus savings estimates already include the selector fee is not stated in the documentation VentureBeat reviewed.
Which model writes Liberty 4.0’s final answer?
Meta’s Muse Spark Open does the combining, according to TrustedRouter, with Reflection AI’s Beam taking over synthesis if the Meta model is unavailable. NVIDIA’s Nemotron 3 Ultra is the third panellist. If a panellist fails to answer, Liberty works with the responses it receives rather than failing the request, and a full run uses five model calls.
More news
Gemini Decisions API scores 1,000 multimodal questions in one pass
Google's Gemini Decisions API scores up to 1,000 multimodal questions in one pass, with low latency and no output-token charges. Here is what it changes.

Frontier3DBench Tests Whether Coding Agents Build 3D Worlds
Einsia's Frontier3DBench tests whether coding agents can build 3D objects, scenes and working worlds; GPT-6.1-sol led overall. See what it means.

Anthropic launches Claude Fable 5.2, Mythos 5.2, cuts API prices 20%
Anthropic's Claude Fable 5.2 and Mythos 5.2 top several third-party benchmarks and cut API prices 20%. Here's what the effort settings mean for your bill.