AWS launches Kiro bots with memory for recurring dev jobs
AWS has launched Kiro bots in Crew, persistent agents that remember decisions and handle recurring development jobs. Here's what it means for teams.
 Source: VentureBeat — AI
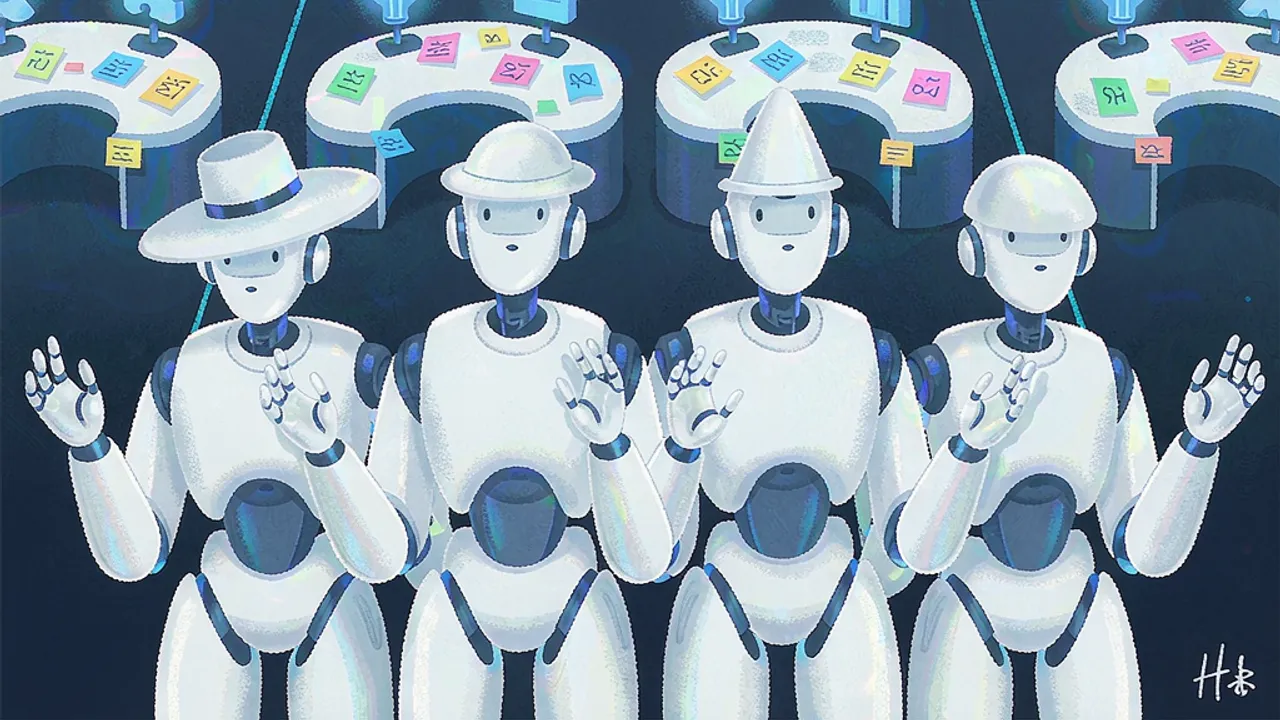
Amazon Web Services has made Kiro bots generally available in its Kiro Crew development workspace, adding persistent agents that can carry recurring responsibilities between human interventions. The launch matters because it shifts the pitch from generating code on demand to assigning ongoing ownership, with memory, schedules and supervision of other agent sessions.
According to VentureBeat, AWS is targeting a coordination problem that appears when developers hand several jobs to AI systems at once. Someone still has to identify stalled agents, reconcile their outputs and repeat the same requirements when work resumes. AWS proposes that a named bot can take on parts of that follow-up work.
What AWS announced on Thursday
AWS introduced Kiro bots on Thursday, November 5, 2026, according to VentureBeat. The feature is described as generally available rather than as a limited preview.
In AWS's framing, a developer might assign one bot to watch for failed builds, another to review proposed code changes and a third to check whether a release is ready. Each bot is intended to retain its own context and to direct multiple worker sessions, rather than acting as a single prompt that finishes and disappears.
For enterprise engineering leaders, according to VentureBeat, the proposition goes beyond faster code generation. The aim is for bots to carry parts of the development process forward between human interventions. Whether that reduces management overhead will depend, the report notes, on how reliably the bots follow instructions, escalate decisions and stay within the permissions set by their teams.
How a Kiro bot is meant to work
Each Kiro bot has a name, a continuing conversation, its own notes and a dedicated workspace, according to AWS. A developer can return to that conversation to change direction or review findings without reopening every worker session individually.
A bot can launch several sessions, track their progress, correct deviations and consolidate the output, according to AWS. When one branch of work needs a human decision, it can request that decision while continuing other tasks that do not depend on the answer.
Schedules can also be described conversationally. AWS gives examples of a bot investigating failures overnight or assembling a weekly summary of changes. Its activity log records routine work, while the conversation surfaces findings and questions that need attention.
AWS illustrates the feature with four possible assignments: categorizing incoming issues and identifying duplicates; checking build pipelines for new failures; reviewing proposed changes against earlier engineering decisions; and verifying tests and documentation before a release. VentureBeat stresses that these are examples of configurable workflows, not evidence that AWS has supplied four autonomous replacements for those engineering functions. Developers still define the job, provide access to relevant systems and determine what completion means.
A bot can also maintain a customized dashboard. In an example accompanying the announcement, a GitHub monitoring bot groups issues by topic and displays changes in the backlog, giving developers a way to inspect the work without reading every underlying exchange.
Memory, permissions and model choice
AWS ties each bot's memory to its particular assignment. Decisions about deployments can remain separate from the context a research bot accumulates, and users can inspect, revise or remove remembered information.
The announcement describes improvement through saved context, conversations and corrections. It does not establish that bots retrain their underlying models. The practical claim, according to VentureBeat, is that a developer should have to explain a recurring preference or constraint fewer times.
Permissions also vary by bot. AWS describes a research configuration that can inspect files without editing them and a deployment configuration that requests approval before making changes. Its example review bot can comment and request revisions but cannot approve or merge code. Users can subsequently adjust those boundaries.
That distinction matters because a bot's assigned responsibility does not automatically confer unrestricted authority. AWS says adding tools requires user approval, and the developer decides how much initiative each bot can take.
Model selection introduces another control. The coordinating bot and its workers can use different models, allowing a team to reserve a more capable model for planning while assigning repetitive checks to a cheaper option. Kiro's model catalog includes offerings from OpenAI and Anthropic, alongside open-weight alternatives, and availability and credit charges vary by model.
Bots can run through Crew on a laptop, a Mac Mini or an Amazon EC2 instance, according to the announcement. That gives users flexibility over where the workspace operates, although running the software on their own hardware should not be confused with running every underlying model locally.
How it compares with Cursor, Anthropic and OpenAI
AWS enters an established competition to automate work between user prompts. Scheduling, retained context and background execution already appear in rival products, according to VentureBeat, and the comparison focuses on recurring development work and adjacent workflows rather than treating every coding assistant as equivalent.
Cursor Automations launch agents from schedules or supported events, with persistent notes, code changes, reviews and computer interaction. Cursor's automation memory survives individual runs and can be edited or deleted, and agents can create pull requests, interact with external tools and demonstrate changes using screenshots or recordings. Persistent memory therefore does not, by itself, distinguish Kiro.
Anthropic's Claude Code scheduled tasks, formerly routines, support schedules, API calls and GitHub events, with Anthropic-hosted or organization-hosted execution. Anthropic still labels the capability a research preview. Its emphasis is on configuring repositories, connectors and triggers, and one task can combine several trigger types.
OpenAI distinguishes between desktop tasks that need an available local machine and web tasks that use uploaded context and connected services. ChatGPT and Codex scheduled work supports local projects through the desktop app, or web workflows with connected tools, with event triggers depending on plan and surface.
Kiro's proposed advantage is the combination: a continuing conversation around a specific responsibility, its own memory and authority, and a coordinator that supervises workers and maintains a view of their progress. VentureBeat describes that as a product-design distinction, not evidence that it outperforms competitors at equivalent work.
What it costs and what remains unproven
AWS's pricing page says Kiro subscriptions cover Crew as well as the IDE, CLI and web product, and the launch post does not announce a separate per-bot fee. The Free plan includes 50 credits, Pro costs $20 per month with 1,000 credits, and higher individual tiers cost $40, $100 or $200. Additional credits cost $0.04 each.
For teams of at least two, AWS lists pooled usage at $20 per seat per month, with each seat contributing 500 credits. That differs from the individual $20 Pro plan's 1,000-credit allowance. Extra team credits also cost $0.04 each.
A credit is not a completed task, according to VentureBeat, because consumption depends on complexity and model selection. Teams therefore cannot infer the monthly cost of a continuously scheduled bot from the subscription price alone. More frequent checks, larger repositories and repeated attempts can change the economics of unattended work. Separating the coordinating model from worker models gives Kiro users a possible cost-control mechanism, but AWS does not provide a measured savings figure for that arrangement in the announcement.
The launch post also does not provide comparative benchmarks, quantified productivity results or a measured rate of mistakes for the new bots. It describes capabilities and suggested workflows, leaving prospective users to establish how much oversight their own deployments require.
A useful evaluation would measure time spent reviewing and correcting the bot alongside work completed, unexpected actions and model consumption. A system that catches more build failures but produces too many unnecessary escalations may simply move the workload elsewhere. AWS's own examples suggest a practical starting point: assign a narrow recurring responsibility, constrain its authority and expand it only after reviewing the results.
How this relates to Grafy
For developers experimenting with persistent coding agents, Grafy Code is the closest Grafy surface for trying related workflows in an AI coding studio. Readers can use it to test how much of a narrow, recurring development task an agent can handle, what review burden remains with the human, and where permissions and escalation points need to be set before any wider rollout.
The broader lesson from the Kiro launch is about design rather than a single feature: give an agent a bounded responsibility, keep its memory inspectable, and measure the coordination work it actually removes. Readers exploring that idea across models can also compare approaches in Grafy Chat, while project memory in Grafy looks at how an AI can remember decisions over time.
Frequently asked questions
Do Kiro bots retrain their underlying models?
No. According to AWS's announcement as reported by VentureBeat, improvement comes through saved context, conversations and corrections. That does not establish that bots retrain their underlying models. The practical claim is narrower: developers should need to explain a recurring preference or constraint fewer times.
Can the example Kiro review bot approve or merge code?
No. AWS's example review bot can comment and request revisions, but it cannot approve or merge code. That limit illustrates how permissions can vary by bot. A research configuration may inspect files without editing them, while a deployment configuration requests approval before making changes.
Does running Crew on your own computer mean the models run locally?
No. AWS says bots can run through Crew on a laptop, a Mac Mini or an Amazon EC2 instance. That describes where the workspace operates. It should not be confused with running every underlying model locally, because model execution and workspace location are separate choices.
More news
Only four Uber rides were booked by AI agents in busiest week
Uber said only four rides were booked by AI agents in its busiest week, versus 320 million trips and orders. Here's what it signals for agents.
Qodo adds company context to Codex for AI‑powered code review
Qodo’s new Codex plugin injects a firm’s internal knowledge and coding standards into OpenAI’s Codex.

NVIDIA Releases Auto Ontology to Ground AI Agent SQL Queries
NVIDIA has launched Auto Ontology, an open-source library that creates a semantic layer for enterprise data. Learn how it improves AI agent accuracy.