Cerebras details wafer-scale deployment of trillion-parameter models
Cerebras has explained how it splits a 3T-parameter model across 59 wafer-scale chips, and why that pipeline matters for open-weight AI serving.
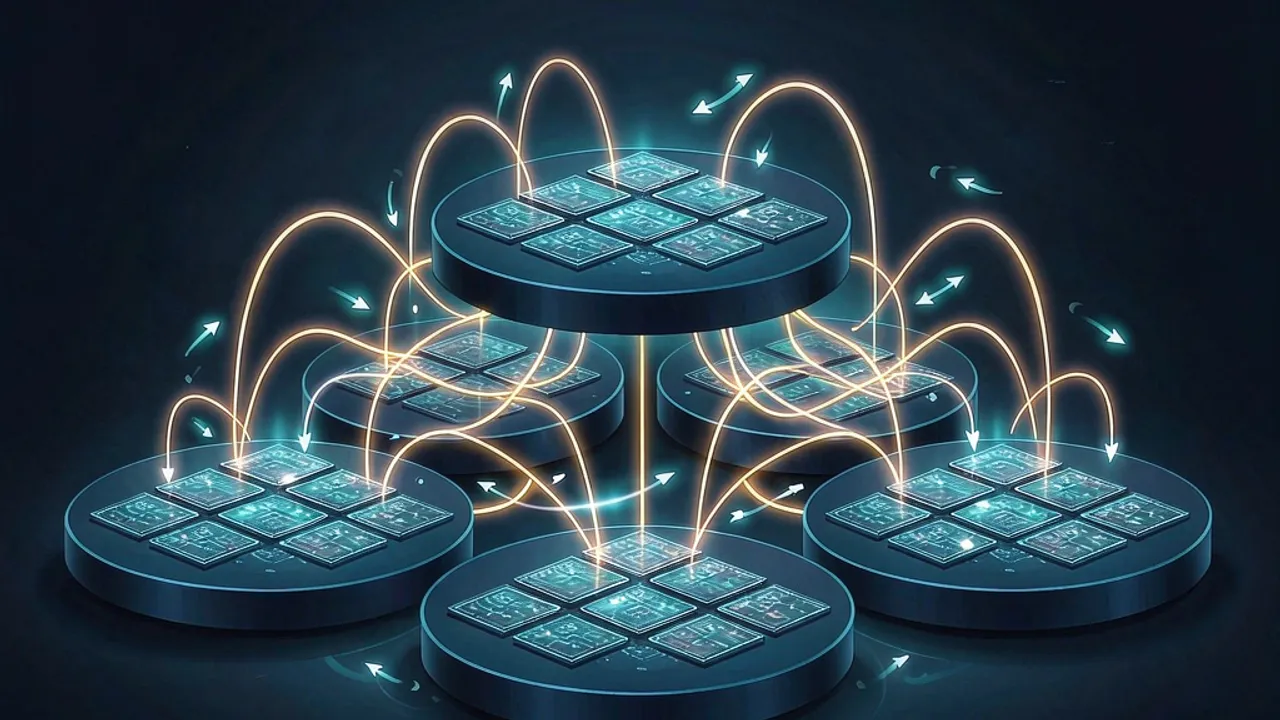
Cerebras has published a detailed account of how it runs multi-trillion-parameter models across dozens of wafer-scale processors, describing a pipeline in which model weights stay on chip and only activations travel between wafers at roughly two microseconds per hop. It matters because the post turns an abstract claim about frontier-scale inference into a specific architecture, with trade-offs developers can inspect and test.
In a blog post by Sarah Chieng, Cerebras explains how it splits a large frontier model across multiple WSE-3T wafers to run multi-trillion-parameter models at 1,000–2,000+ tokens per second, using the open-source Kimi K3 as its worked example. The original write-up is on Cerebras's blog.
How does Cerebras fit a 3-trillion-parameter model onto wafer-scale chips?
A single WSE-3T wafer provides 44 GB of on-chip memory, according to Cerebras, while trillion-parameter models need terabytes for their weights alone. The answer is to spread the model across many wafers rather than squeeze it into one.
The worked example is Kimi K3, described as an open-source model with about 3 trillion parameters, 69 linear-attention layers and 24 dense layers. Cerebras assumes 4-bit weight quantization, in the manner of the Hugging Face implementation, an 8-bit KV cache, and a 256k assumed average request size.
On those assumptions, each of the model's 93 layers comes to roughly 16 GB. Because a layer fits comfortably inside 44 GB, Cerebras can keep whole layers resident on a chip instead of splitting them across wafers.
Why do dense layers need a wafer to themselves?
Dense, full-attention layers store the keys and values for every token in every active request, so their cache grows with context and concurrency. Cerebras therefore places one dense layer on a wafer and leaves the remaining SRAM for its KV cache.
Linear-attention layers work differently: rather than storing keys and values per token, each keeps a small, fixed-size state per request regardless of context length. That leaves room for two linear layers per wafer — 2 × 16 GB = 32 GB — with no KV cache allocation needed.
The resulting mapping for Kimi K3 is 35 wafers for the 69 linear layers plus 24 for the dense layers, or 59 in total, according to the post.
How do the wafers pass work between them?
Cerebras executes models as a pipeline. Its compiler maps model layers across regions of wafers, and the runtime maps the path tokens travel between them. Only activations cross between wafers, over RDMA over Ethernet, at roughly two microseconds per hop; weights generally do not move at all.
The assembly-line analogy in the post: wafer 1 runs layers 1–2 and sends activations to wafer 2, which runs layers 3–4 and passes results to wafer 3, until the last wafer produces the next token. Cerebras says production deployments use much finer-grained stages than the illustration.
How does the pipeline handle many requests at once?
The post directly tackles the obvious objection: if a token must pass through every wafer in order, is the system effectively running at batch size one? Cerebras's answer is that the pipeline stays full with different requests. While stage 3 processes a token for request A, stage 2 can process one for request B and stage 1 one for request C. Each stage can also work on a micro-batch — a small group of requests — so requests in flight are roughly stages multiplied by micro-batch size. Smaller micro-batches make an individual request faster; larger ones raise total throughput.
Concurrency also has a hard ceiling. Every in-flight request needs its own KV cache on each dense-layer wafer, so the memory left for caching sets how many requests run at once. Cerebras's method: subtract one dense layer from a wafer's 44 GB, calculate the cache a single 256k request needs, then divide the available cache by that figure. Unlike a GPU batch, these requests stream through the pipeline continuously rather than waiting for one another to finish. The company also cautions that neither concurrency nor batch size describes efficiency on its own, pointing instead to token throughput per unit of power — tokens per second per megawatt — measured at the same output generation speed.
What does this mean for developers and researchers?
The example is not a toy model. As described in Cerebras's post, Kimi K3 scores 88.3% on Terminal-Bench 2.1, against 88.8% for GPT-5.6 Sol, and 91.2% on BrowseComp, against 90.4% for GPT-5.6 Sol. Open-weight models in the multi-trillion-parameter class are becoming servable at high token rates, and the architecture described here is a plausible reason why.
The caveat matters just as much. Cerebras notes that performance comparisons rest on third-party benchmarking or internal testing, and that observed speed improvements versus GPU-based systems may vary with workload, configuration, date and models tested. The method also scales: calculate memory for weights and request state, distribute across wafers, connect them into a pipeline. Each additional wafer adds compute and on-chip memory, allowing models larger than any single chip.
How can you explore this in Grafy?
Grafy runs many cloud models side by side through providers such as OpenRouter, Vertex AI, fal and Replicate, and Cerebras's post is best read as background on the serving layer beneath models of this class. Use Grafy Chat to compare how different models answer the same prompt; use Grafy Reader to read the post and related inference papers, then ask questions about the pipeline, the KV-cache arithmetic and the benchmark caveats; and use Grafy Code to prototype a scheduler or measure token throughput on your own workload. Grafy News has also covered Kimi's K3.1 Pro, a 3T-class open-weight model, useful context for the model used here. This is infrastructure background rather than a Grafy product update: Cerebras points developers to its own free API and sales team for direct access to its hardware.
Frequently asked questions
How many Cerebras wafers does the Kimi K3 example require?
Under the post's assumptions — 4-bit weight quantization, an 8-bit KV cache and a 256k assumed average request size — the mapping calls for 59 WSE-3T wafers: 35 to hold the model's 69 linear-attention layers, two per wafer, and 24 to hold its dense layers, one per wafer, leaving room for each layer's KV cache. The count is illustrative rather than a fixed recipe; different quantization, context assumptions or mappings change it.
Does splitting a model across many wafers add too much latency?
Not according to Cerebras's design. Because a layer fits inside a wafer's 44 GB of on-chip memory, weights generally stay put and only activations cross between wafers, over RDMA over Ethernet, at roughly two microseconds per hop. Individual request latency is governed more by micro-batch size than by the number of hops: smaller micro-batches favour per-request speed, larger ones favour total throughput.
Can I try Cerebras or Kimi K3 inside Grafy?
Grafy is not a Cerebras deployment, so treat this post as background on how large open-weight models are served rather than a Grafy feature announcement. Cerebras directs developers to its own free API and sales team for access to its hardware. Inside Grafy, use Chat to compare models side by side, Reader to work through the post and related papers, and Code to prototype throughput measurements on your own workload.
Source: Hacker News — front page — Cerebras Deploys Trillion-Parameter AI Models
More news
AI linked to loss of 200,000 U.S. creative jobs, analysis shows
Over 200,000 jobs have vanished from U.S.
Canva releases Canva Craft, its first in-house image model
Canva Craft, Canva's first in-house image model, generates 2K images in 30 aspect ratios and turns them into editable layered designs — here's what changes.
ThinkingCap trims Gemma-4 reasoning tokens 39% at flat accuracy
BottleCap AI's ThinkingCap-gemma-4-26B-A4B-it cuts reasoning tokens 38.9% on average across 12 benchmarks for 0.15pp of accuracy. Why builders care.