Compositional Random Forest Adds Two Likelihood Split Criteria
A new random forest framework for compositional data adds two likelihood split criteria to the Dirichlet; the tangent-normal one won two of three designs.
 Source: Grafy Research Lab
Researchers at Stellenbosch University have built a random forest framework for compositional responses — data whose components are non-negative and sum to a constant — that can be grown with three different likelihood-based split criteria rather than one. That matters because the split criterion decides what a tree is able to detect, and the best-established option for this data type, the Dirichlet, ties the covariance to the mean and needs an iterative maximum-likelihood fit at every candidate split.
What did the paper propose?
The preprint, titled "Compositional random forest" and posted on arXiv as 2611.14275 with a date of 10 November 2026, comes from Khaled Masoumifard, Stephan van der Westhuizen and Sugnet Gardner-Lubbe of the Department of Statistics and Actuarial Science at Stellenbosch University, who are also listed with the university's Centre for Multi-dimensional Data Visualisation (MuViSU). According to the authors, compositional data have been analysed in the literature from three main points of view: directly on the simplex, in log-ratio coordinates, and as directional data on the unit sphere. Their framework is designed to accommodate all three at once.
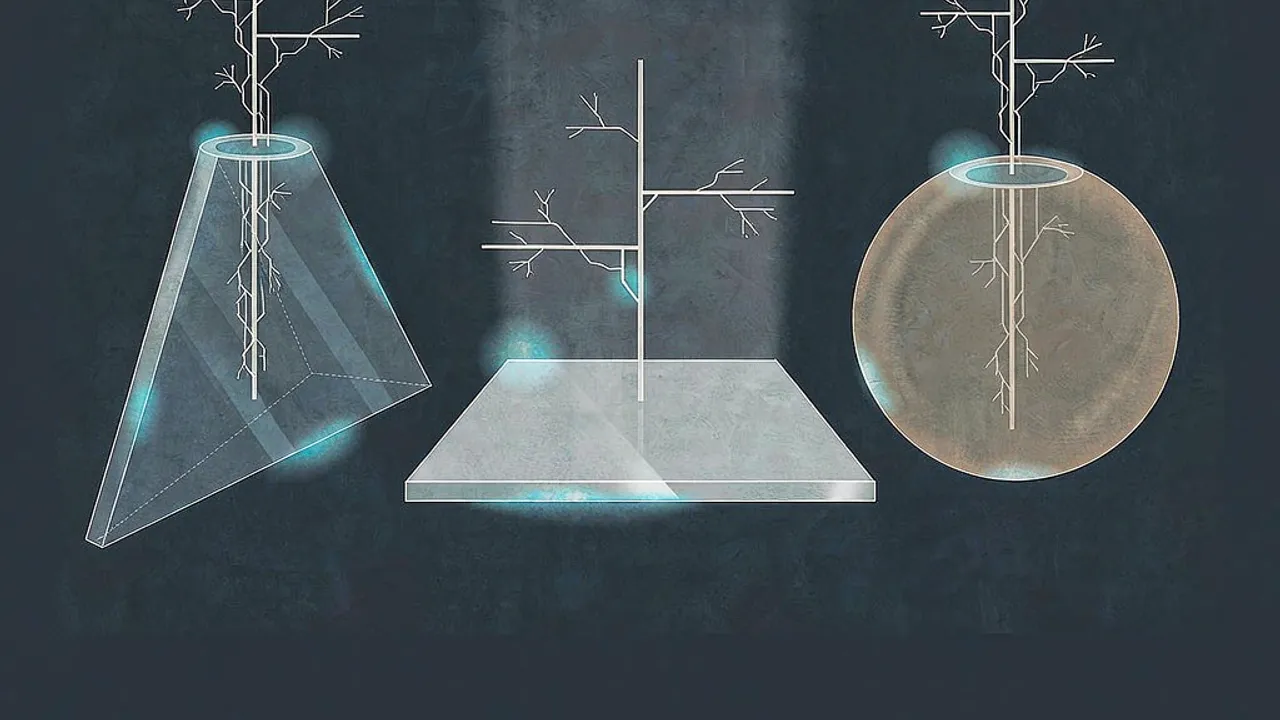
The mechanics are straightforward to state. A random forest is an ensemble of decision trees, and the split criterion determines how each tree grows. The authors use the log-likelihood gain as that criterion and pair it with distributions defined on each of the spaces in which a composition can be represented: the Dirichlet on the simplex, the multivariate logistic-normal (MLN) in log-ratio coordinates, and a new tangent-normal (TN) distribution on the sphere.
Why is compositional data awkward to model?
Compositional data are vectors of non-negative components that sum to a constant, so they lie in a simplex rather than in real space, and the paper notes that multivariate methods developed for real space are generally inappropriate there. How to model them has been the subject of a long methodological debate. The three established routes are distributions defined directly on the simplex, such as the Dirichlet; log-ratio transformations, which transfer the simplex to real space; and the square-root transformation, which transfers compositions onto the positive orthant of the unit sphere.
The paper recounts how that debate unfolded. Stephens modelled square-root-transformed proportions with the von Mises distribution on the sphere in 1982, and Watson and Philip represented compositions as unit vectors in the positive orthant in 1989, measuring differences between them by angles rather than log-ratios, prompting an exchange of comments and replies in which Aitchison defended the log-ratio approach. Log-ratio methods went on to become dominant. Scealy and Welsh have argued that this dominance reflects not only the merits of those methods but the way the debate was conducted: principles including scale invariance, subcompositional coherence and permutation invariance became a test of whether a method was acceptable, so methods failing them were treated as invalid regardless of their statistical properties or practical usefulness — a situation those authors describe as unusual in statistical data analysis. A practical reason keeps alternatives alive: log-ratio transformations are undefined when a component is zero, and for highly variable data near the boundary of the simplex, log-ratio and alternative methods can lead to substantively different conclusions.
What are the limits of the Dirichlet criterion?
Earlier work has already adapted random forests to compositional responses, either by mapping the data to real space with a log-ratio transformation first, or by basing the split criterion on a likelihood for the bounded or compositional response itself. Weinhold and colleagues developed a forest based on the beta distribution for bounded outcomes in 2020, and Masoumifard and colleagues proposed the Dirichlet random forest, whose criterion is the gain in Dirichlet log-likelihood.
According to the paper, the Dirichlet has two limitations. Its covariance matrix is determined by its mean up to a single precision parameter, so the criterion cannot capture changes in the relative variances of the components or in their dependence structure. And its maximum likelihood estimator has no closed form and must be computed iteratively for every candidate child node at every split — an expensive requirement inside a split search, where candidates are numerous.
What is new about the tangent-normal criterion?
The square-root transformation is attractive because directional distributions behave well near zero, where log-ratio coordinates can become highly variable. But the existing directional options — the Kent distribution, the scaled von Mises–Fisher distribution and the elliptically symmetric angular Gaussian distribution — also lack closed-form maximum likelihood estimators, which in a forest would have to be repeated for every candidate during the split search.
The authors' response is a new tangent-normal distribution on the sphere, which shares its parameters with the Kent distribution. Its split criterion computes the gain from additive sufficient statistics: the shape parameters are maximised out in closed form, up to an exponentially small truncation constant, so no parameter is estimated iteratively. The MLN criterion likewise has a closed-form maximised log-likelihood based on additive sufficient statistics, giving it a flexible covariance. The practical payoff is that both criteria respond to a shift of the mean, measured relative to the covariance, and to a change in the covariance itself — so unlike the Dirichlet criterion, they can react to covariates that alter the relative variances or the dependence structure of a composition.
What did the simulation study find?
The authors compared the three forests on simulated datasets across three designs, labelled in the paper for the distribution that generated them: Dirichlet, logistic-normal and Kent. The headline result is conditional rather than a clean sweep. The most accurate forest depended on the covariance structure of the composition, and the tangent-normal forest was the most accurate in two of the three designs. Additional designs and results are reported in the paper's appendix, along with the normalising constants of the tangent-normal and Kent distributions.
Where does Grafy fit?
Grafy does not ship a compositional-data modelling app, so there is no direct implementation of this framework to try. The genuine fit is at the reading stage. This is a derivation-heavy paper, and Reader is built to read, search and question PDFs and papers with AI, which makes it a reasonable way to work through the split-criterion sections or to ask what the additive sufficient statistics buy in practice — see also A reading room for papers, with the AI on tap. Anyone wanting to prototype a likelihood-based split criterion could sketch it in Grafy Code, the AI coding studio that installs packages and runs your code. For readers who follow this corner of the literature, Outliers Reshape Hard-Margin Linear SVM in High Dimensions covers another result about how classical estimators behave when data assumptions shift.
Frequently asked questions
Does the tangent-normal criterion estimate any parameter iteratively?
No. According to the paper, the tangent-normal split criterion computes its gain from additive sufficient statistics, with the shape parameters maximised out in closed form up to an exponentially small truncation constant, so no parameter is estimated iteratively. The mean direction is obtained from a moment estimate. That is the property the authors set out to achieve, since iterative fitting at every candidate node is what makes the Dirichlet criterion costly.
Was the tangent-normal forest the most accurate in all three simulation designs?
No. The tangent-normal forest was the most accurate in two of the three designs. Across the study, the authors report that the most accurate forest depended on the covariance structure of the composition, so no single criterion dominated everywhere. The three designs are labelled in the paper for the generating distribution: Dirichlet, logistic-normal and Kent, with further designs and results in the appendix.
Does the Dirichlet criterion respond to changes in the covariance of the composition?
Not to changes in relative variances or dependence structure. The paper states that the Dirichlet covariance matrix is fixed by its mean up to a single precision parameter, so its criterion cannot capture such changes. Its maximum likelihood estimator also has no closed form and must be computed iteratively for every candidate child node at every split. The MLN and tangent-normal criteria were designed to respond to covariance changes.
More news

Frontier3DBench Tests Whether Coding Agents Build 3D Worlds
Einsia's Frontier3DBench tests whether coding agents can build 3D objects, scenes and working worlds; GPT-6.1-sol led overall. See what it means.

Anthropic launches Claude Fable 5.2, Mythos 5.2, cuts API prices 20%
Anthropic's Claude Fable 5.2 and Mythos 5.2 top several third-party benchmarks and cut API prices 20%. Here's what the effort settings mean for your bill.
Chrome's Modern Web Guidance hits 1.0, adds Firefox and Edge
Chrome released Modern Web Guidance 1.0, giving coding agents expert web best practices, now backed by Firefox and Edge. Here's what changed.