DocFS Turns Complex Documents Into File Systems for AI Agents
A research framework called DocFS rebuilds long, image-heavy documents as file systems so AI agents navigate them faster and with far fewer tokens.
 Source: Grafy Research Lab
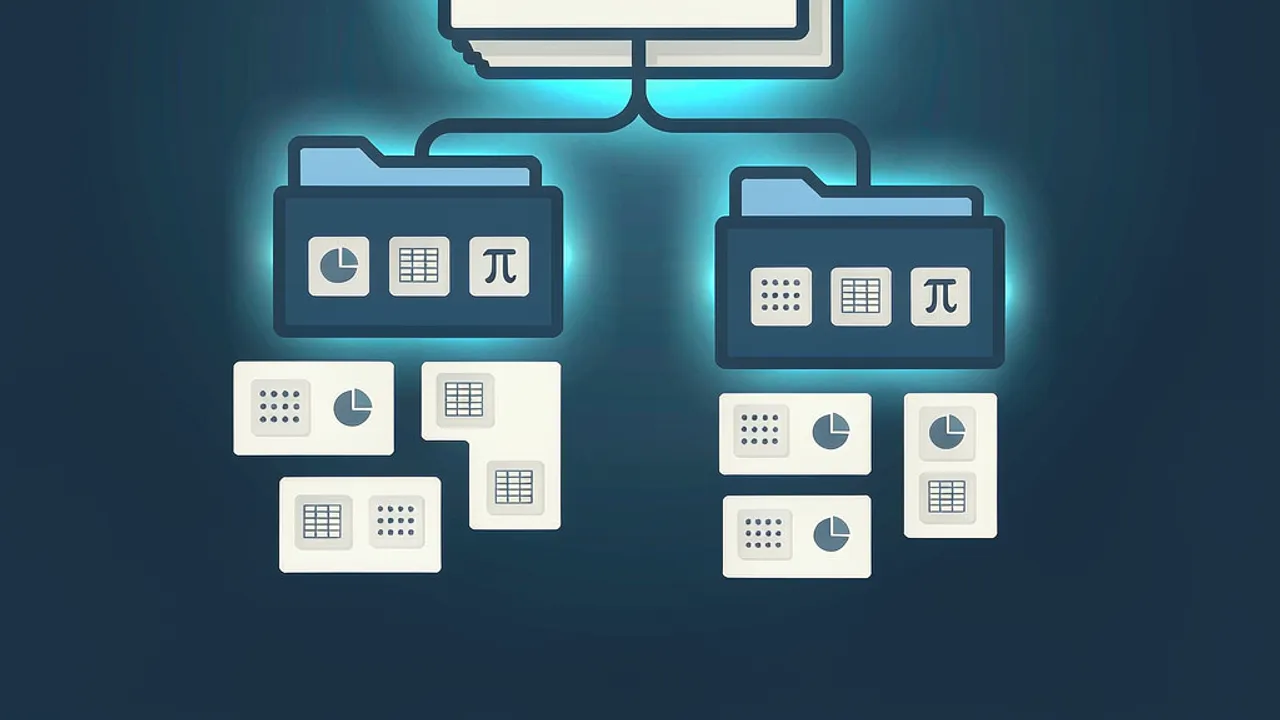
A team of researchers has proposed DocFS, a method that reorganizes long, image-heavy documents into file systems so that AI agents can browse them much as a person browses folders. The approach, described in an arXiv preprint, targets a stubborn weakness in how vision-language agents handle complex documents: the way information is laid out has outpaced the tools agents get for exploring it.
The work, posted to arXiv by Bingdian Zhang, Zixuan Li, Long Bai, Xiaolong Jin, Jiafeng Guo and Xueqi Cheng — researchers affiliated with the Institute of Computing Technology at the Chinese Academy of Sciences and its associated university — reframes document question answering as building a usable environment for an agent, not just an index to search.
What is DocFS trying to fix?
Vision-language model (VLM) agents work by interacting with an environment step by step, and how well they perform depends heavily on how that environment exposes information and what tools it offers, according to the paper. Complex multimodal document question answering is a hard case. A single document can run to many pages, with text, figures, tables and equations spread across nested sections and connected by cross-modal links. Prior work, the authors write, tends to organize documents into structured representations that solve only the "information" half of the problem, leaving agents without tools matched to that structure. The result is a gap: structure that exists on paper but cannot be freely explored during reasoning.
How does a document become a file system?
DocFS's central observation is that a file system already pairs organized information with tools built to use it. According to the paper, DocFS converts a raw document into a hierarchy of nested directories that mirror the document's section structure, then stores text, figures, tables and equations as individual files inside the matching folders. Cross-modal associations — the links between a passage and the figure or table it refers to — are made explicit rather than left implicit. The system adds two kinds of description files. Structure files, meaning index and relation files at both global and local levels, turn the section tree into navigation entry points and record relationships across sections and modalities. Image description files give each figure a text description mapped back to the original image, so visual content can be found by keyword.
What can the agent actually do inside the file system?
Because the document is now a file system, the agent uses ordinary file operations instead of a bespoke interface. The paper describes three: navigating the directory hierarchy to move between a global view and local detail, searching by keyword to locate candidate evidence, and reading files to understand each type of content. From there the agent runs an iterative reasoning loop the authors divide into evidence localization, evidence retrieval and expansion, and source-level verification. The point, according to the paper, is that these are well-established operations needing no specialized tooling, so the same structure stays directly usable throughout the agent's interaction with the document.
How well does DocFS perform?
According to the paper, DocFS paired with the Qwen3.5-Plus model reached state-of-the-art results on two benchmarks, MMLongBench-Doc and FinRAGBench-V, beating the strongest baselines by 2.9 and 4.3 percentage points respectively. The efficiency gains were larger still: the authors report DocFS was up to 10.3× faster and used up to 10.1× fewer tokens than the strongest baseline during reasoning. For anyone running document agents at scale, those numbers may matter as much as accuracy — fewer tokens and less time per question translate directly into lower cost.
Why do file systems work where other structures struggle?
The paper sorts existing approaches into two families. Flat organization keeps documents as page images or flat content units; it can preserve layout but does not expose hierarchy or cross-modal relations as things an agent can act on. Structured organization builds content trees, multi-granularity indexes or page-context graphs; it makes hierarchy explicit but often delivers it only as retrieved evidence, or binds access to a custom interface tied to one representation. A file system, the authors argue, sidesteps both problems, because directories, files and standard file operations are already a shared, general-purpose vocabulary — structure and tools arrive together.
How could you explore this with Grafy?
If you work with long PDFs and want AI to answer questions grounded in them, Grafy Reader is the closest match: it lets you read, search and question PDFs and papers with AI. The DocFS idea — keeping a document's structure and figures navigable rather than flattening everything into one blob — is the same problem Reader is built around, and you can try it on a dense report or paper of your own. For preparing the files themselves, Grafy Files handles PDF, image and audio conversions and tools. And if you want to see which parts of a document an answer came from, the walkthrough on chatting with a PDF and knowing what was read shows how to keep AI answers tied to the source.
Frequently asked questions
What benchmarks did DocFS set state-of-the-art results on?
According to the paper, DocFS reached state-of-the-art performance on MMLongBench-Doc and FinRAGBench-V when paired with the Qwen3.5-Plus model. It outperformed the strongest baselines by 2.9 percentage points on MMLongBench-Doc and 4.3 percentage points on FinRAGBench-V, the two benchmarks the authors used to measure complex multimodal document question answering.
How much faster and cheaper is DocFS during reasoning?
The authors report that DocFS is up to 10.3× faster and consumes up to 10.1× fewer tokens than the strongest baseline during reasoning. Those figures come from the paper's efficiency analysis, and they matter because lower latency and fewer tokens per question translate into reduced cost when document agents are run at scale.
How does DocFS organize a document for an AI agent?
DocFS converts a raw document into a hierarchical file system: nested directories mirror the section hierarchy, and text, figures, tables and equations are stored as element-type files in the matching folders. Index and relation files expose navigation paths and cross-modal links, while image description files make figures searchable by keyword. The agent then navigates, searches and reads.
Source: arXiv:2611.12957
More news
United Won't Let AI Agents Book Flights on Its Site
United says AI assistants can browse its flights but can't complete bookings, citing privacy and regulatory worries. Here's what it means for agents.
Pomerado Turns Websites Into Agent APIs, Claims 7x Speedups
Pomerado launched on Hacker News with an open-source MCP server that turns any website into an API for agents.
Plurai Raises $13M to Simulation-Train AI Agents on Digital Twins
Plurai raised $13M in seed funding to test and post-train AI agents inside digital twins of a company's own systems. Here's what that means for builders.