FrontierReplay optimizes hybrid model prefix caching
Researchers introduce FrontierReplay to solve prefix caching inefficiencies in hybrid models, significantly reducing latency and increasing capacity.
 Source: Grafy Research Lab
Researchers have introduced a new system called FrontierReplay that significantly improves how hybrid language models handle prefix caching. By addressing the specific limitations of recurrent layers in these models, the system reduces latency and increases service capacity without sacrificing the accuracy of long-context tasks.
Why is prefix caching difficult for hybrid models?
Hybrid language models, such as Jamba or Qwen3.5, combine standard self-attention layers with recurrent layers like Mamba-2 or Gated DeltaNet. While self-attention uses a key-value (KV) cache that can be truncated at any point, recurrent layers maintain a fixed-size state that summarizes the entire history. According to the research by Zekun Wang and Yizhuo Wang from the Beijing Institute of Technology, this state is updated in-place as each token is processed. Consequently, a cache can only reuse a recurrent state if it is saved at the exact position where a new request begins.
Existing serving engines like vLLM often use a coarse grid to save these states. This approach frequently misses the optimal reuse points, forcing the model to recompute large portions of the prompt. While finer-grained caches exist, they often require "cutting" the prefill forward pass at specific checkpoints to save the state. This process introduces additional scheduler steps that can negate the performance benefits of caching under heavy workloads.
How does FrontierReplay solve the caching problem?
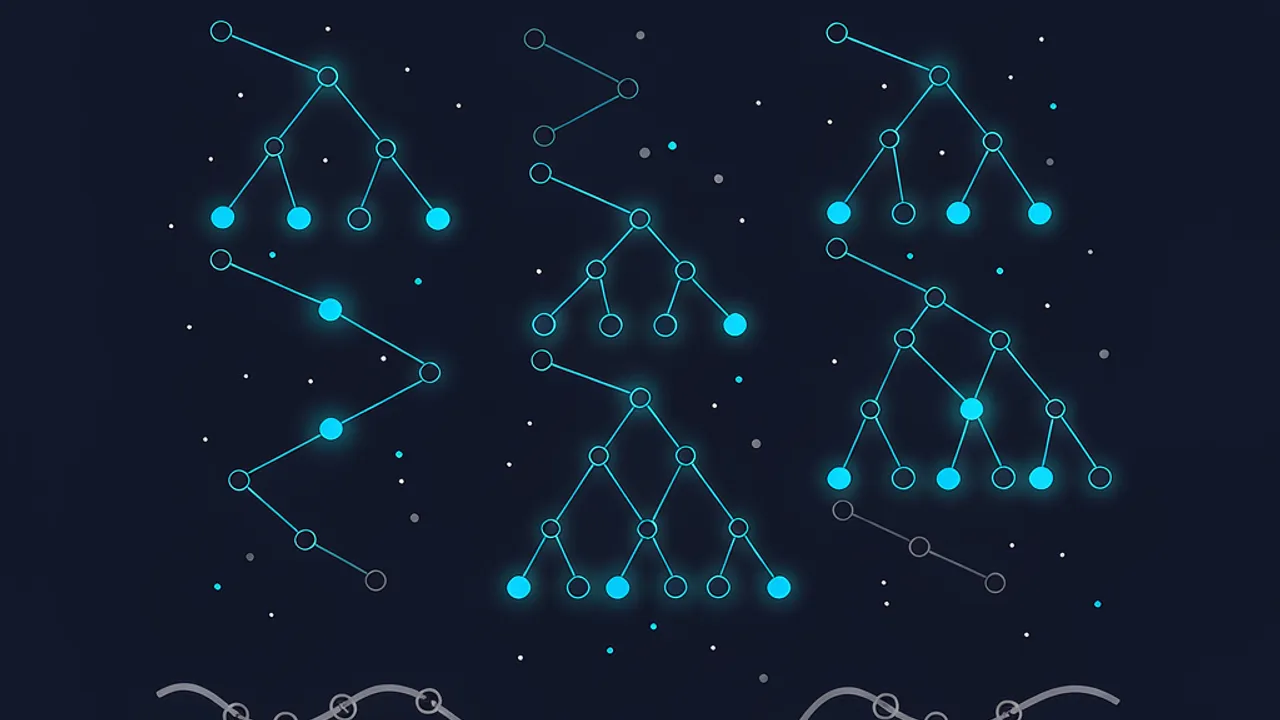
FrontierReplay utilizes a "split-free" checkpointing mechanism. Instead of interrupting the forward pass to save a state, the system allows the prefill process to run continuously. While the model processes the prompt, the system logs a short window of inputs for the recurrent layers. After the forward pass, a specialized state-only replay kernel recomputes the necessary updates to build an exact checkpoint at the target boundary.
According to the authors, this replay method is 6 to 37 times cheaper per token than a full recomputation because it skips the attention, MLP, and output projection layers. This allows the system to create exact checkpoints at predictable structural boundaries—such as the end of a chat turn or a known branching point in a tree search—without the overhead of stopping and starting the model's execution.
What are the performance benefits of this method?
In evaluations conducted on various hybrid architectures and model scales (from 4B to 34B parameters), FrontierReplay demonstrated substantial improvements over existing baselines. The researchers reported that the system can lower the median time to first token (TTFT) by 16% to 89%. For instance, on the Falcon model during SWE-agent tasks, the median TTFT dropped from 1.1 seconds to 125 milliseconds.
Beyond latency, the system also improves throughput and capacity. The study found that FrontierReplay can increase 80% service-level objective (SLO) capacity by up to 1.73 times and improve overall goodput by up to 4.26 times compared to vLLM. Importantly, unlike approximate replay methods that can cause accuracy drops of up to 17% in long contexts, FrontierReplay maintains exact task accuracy by providing mathematically precise states.
How does the system manage memory and cache retention?
Because recurrent state checkpoints are relatively large—ranging from 49 to 67 MiB—efficient memory management is critical. FrontierReplay employs a "frontier-aware" retention policy. This policy uses a boundary planner to identify which checkpoints are most likely to be reused.
It prioritizes "active anchors" and proven branch points while identifying "dead" checkpoints—those whose associated KV cache has already been evicted. To maximize efficiency, the system can lend the memory slots previously occupied by dead checkpoints to the attention KV cache pool. This tiered approach ensures that the most valuable parts of the conversation history remain available for immediate reuse.
How can researchers apply these findings?
For researchers working with large-scale document analysis or complex agentic loops, these findings highlight the importance of structural boundaries in prompt engineering. Since reuse often ends at turn boundaries or known branch points, optimizing how these points are handled can drastically change inference efficiency.
While FrontierReplay is a system-level optimization for model serving, readers interested in exploring the complexities of long-context reasoning and hybrid model behavior can use Grafy Reader to perform deep research over academic papers and technical documentation. This allows for a more structured way to synthesize how different architectural optimizations impact real-world AI performance.
Frequently asked questions
Does FrontierReplay change the accuracy of the model?
No, FrontierReplay does not change the model's accuracy. Unlike approximate replay methods that rebuild a state using only the last few hundred tokens, FrontierReplay uses a state-only replay kernel to produce an exact checkpoint. This ensures that the model's outputs remain identical to a full recomputation, even in very long contexts.
Does FrontierReplay require modifying existing model kernels?
No, the system is designed to be split-free and does not require modifying native forward kernels. It works by logging recurrent-layer inputs during a standard forward pass and then using a separate, cross-layer replay kernel to reconstruct the state. This decoupling makes it easier to integrate into existing serving frameworks like vLLM.
Is FrontierReplay faster than full recomputation?
Yes, the state-only replay mechanism used by FrontierReplay is significantly faster than recomputing the entire prompt. The authors note that the replay process is between 6 and 37 times cheaper per token than a full recomputation because it avoids the computational cost of the attention, MLP, and output projection layers.
Source: Zekun Wang and Yizhuo Wang, "FrontierReplay: Split-Free Exact Prefix Caching for Hybrid Language Models"
Source: Grafy Research Lab — FrontierReplay: Split-Free Exact Prefix Caching for Hybrid Language Models
More news
Anthropic goes public on Nasdaq with $1.5 trillion valuation
Anthropic has officially begun trading on the Nasdaq under the ticker ANT. Learn about its massive valuation, financial losses, and safety commitments.
Apple recruits engineers to develop agentic AI assistants
Apple is seeking engineers to build AI agents capable of web browsing and app interaction. Discover what this means for the future of agentic AI.
AutoMaster makes the same model a better teacher
Researchers have introduced AutoMaster, a system that uses natural-language skills to improve the quality of teacher demonstrations during post-training.