NeurIPS 2026 Paper Introduces Causal Concept Wrapper Network for Trustworthy AI Explanations
A new NeurIPS‑accepted study proposes CCW‑Net, a causal‑based framework that aligns concept explanations with model decisions.
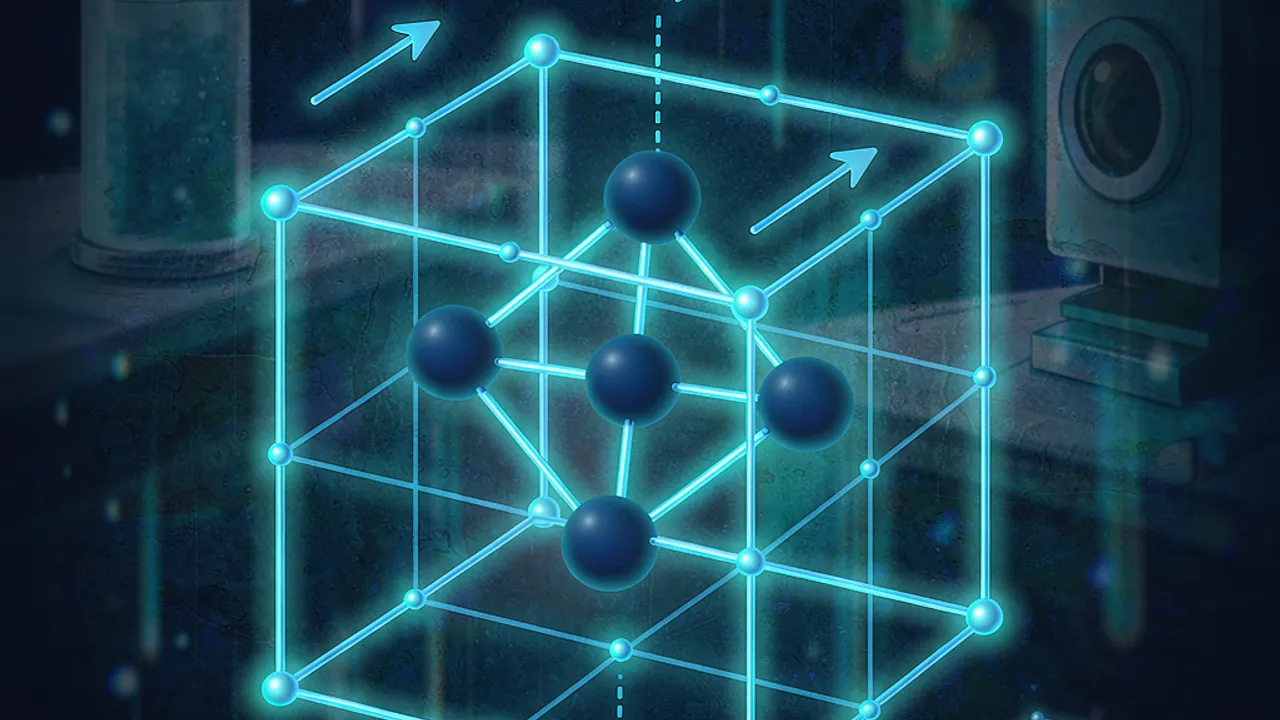 Source: Grafy Research Lab
Concept‑based explanations have become a cornerstone for developers building trustworthy autonomous systems, yet most existing methods only show statistical correlations. On November 11, 2026, a team from the Grafy Research Lab announced a new approach—Causal Concept Wrapper Network (CCW‑Net)—that brings causal reasoning into the explanation pipeline. The work, accepted at NeurIPS 2026, argues that without causal guarantees a “concept explanation” can appear correct while actually being irrelevant to the model’s output.
Why causal reasoning matters for AI interpretability
According to the paper’s abstract, traditional concept explanations tell what a model is looking at but not whether those concepts are necessary or sufficient for a decision. This gap can mislead engineers, auditors, and regulators who rely on explanations for certification or debugging. By treating concepts as variables in an interventional mediation analysis—an approach borrowed from economics, medicine, and epidemiology—the authors aim to test whether manipulating a concept changes the model’s prediction in a predictable way. In practice, such tests could expose spurious correlations that would otherwise pass unnoticed.
What is the Causal Concept Wrapper Network (CCW‑Net)?
CCW‑Net is described as the first architecture that incorporates interventional mediation as a training objective. Rather than only minimizing classification loss, the network also optimizes a causal loss that penalizes explanations which fail to satisfy two criteria:
- Necessity – removing the concept should degrade the target prediction.
- Sufficiency – activating the concept alone should be enough to produce the prediction.
The authors implement these checks by inserting a "wrapper" around the concept layer that can intervene on concept activations during training. By repeatedly sampling interventions and measuring downstream effects, the model learns representations that are aligned with causal influence, not just statistical co‑occurrence. The paper reports nine tables of quantitative results across image‑classification benchmarks, showing improved alignment between extracted concepts and true causal drivers.
How the study was evaluated
The NeurIPS submission spans 28 pages, includes one illustrative figure, and presents nine tables of experimental data. The authors compare CCW‑Net against several baseline concept‑extraction methods, such as TCAV and Concept Bottleneck Models, on standard datasets (e.g., ImageNet subsets). While the exact numbers are not reproduced here, the authors claim statistically significant gains in causal fidelity—a metric they define to measure how well intervened concepts predict changes in model output. The paper also provides a public code repository, enabling the community to replicate the experiments.
Practical implications for developers and researchers
If CCW‑Net lives up to its claims, it could become a new standard for building interpretable models where safety and compliance are non‑negotiable. For example:
- Autonomous vehicles could verify that lane‑keeping decisions are truly driven by lane‑marker concepts rather than incidental background textures.
- Medical imaging AI could demonstrate that a diagnosis relies on clinically relevant visual cues, satisfying regulatory requirements for explainability.
- Regulators could request causal concept audits as part of certification processes, moving beyond superficial heat‑maps.
The framework also opens research avenues, such as extending causal interventions to multimodal models or integrating CCW‑Net with reinforcement‑learning agents that must justify their actions.
Trying CCW‑Net with Grafy tools
While Grafy does not yet host a dedicated CCW‑Net module, the research can be explored using two existing apps:
- Reader – Upload the arXiv PDF to Grafy Reader (/[reader]) to ask the AI to summarize sections, extract the causal loss formulation, or compare CCW‑Net to other methods. This lets you dive into the technical details without leaving the workspace.
- Chat – Use Grafy Chat (/[chat]) to experiment with prompting the model to generate pseudo‑code for the wrapper‑intervention loop described in the paper. By chaining multiple model responses you can prototype a small‑scale implementation before committing to a full training run.
These tools let creators, developers, and researchers get hands‑on with the concepts without needing a custom codebase, and they illustrate how Grafy’s multimodal environment can accelerate interpretability research.
Limitations and future directions
The authors acknowledge several constraints. First, the causal interventions are performed on internal concept activations, which presupposes that the model already exposes a clean bottleneck layer. Second, the method adds computational overhead because each training step requires sampling multiple interventions. Finally, the current experiments focus on vision tasks; extending the approach to language or audio models remains an open challenge.
Future work could address these points by developing more efficient intervention schedulers, designing generic bottleneck architectures, or integrating causal concept learning with large‑scale foundation models. As the field of causal interpretability matures, we may see hybrid pipelines that blend CCW‑Net‑style training with post‑hoc explanation tools.
Source: Grafy Research Lab, “Causal Concept Explanations for Deep Neural Models,” arXiv preprint, https://arxiv.org/abs/2611.14407.
Frequently asked questions
Does CCW‑Net guarantee that every extracted concept is causally relevant?
CCW‑Net improves the alignment between concepts and causal influence, but it does not guarantee perfect causality. The method reduces spurious correlations by penalizing non‑causal explanations during training, yet residual biases can remain, especially if the underlying data distribution is limited.
Can the causal loss be combined with other interpretability objectives?
Yes. The authors design the causal loss as an additive term to the standard classification loss, meaning it can coexist with objectives like sparsity, disentanglement, or fairness. Practitioners can weight each term to balance performance and interpretability.
How can I experiment with CCW‑Net without writing code?
Grafy Reader lets you upload the paper PDF and ask the AI to extract the algorithmic steps, while Grafy Chat can generate scaffold code based on those steps. This no‑code workflow lets you prototype the wrapper‑intervention logic before implementing it in a full training pipeline.
Source: Grafy Research Lab — Causal Concept Explanations for Deep Neural Models
More news
MicroLens Lets Researchers Read and Rewire AI
The new MicroLens viewer lets researchers read and rewire AI model states with two lenses. It could change how interpretability work is done.

Frontier3DBench Tests Whether Coding Agents Build 3D Worlds
Einsia's Frontier3DBench tests whether coding agents can build 3D objects, scenes and working worlds; GPT-6.1-sol led overall. See what it means.

Anthropic launches Claude Fable 5.2, Mythos 5.2, cuts API prices 20%
Anthropic's Claude Fable 5.2 and Mythos 5.2 top several third-party benchmarks and cut API prices 20%. Here's what the effort settings mean for your bill.