OpenAI, Google, Microsoft, Anthropic Back Opt‑Out Scraping Standard
OpenAI, Google, Microsoft and Anthropic will support a shared robots.txt token that lets publishers opt out of AI scraping.
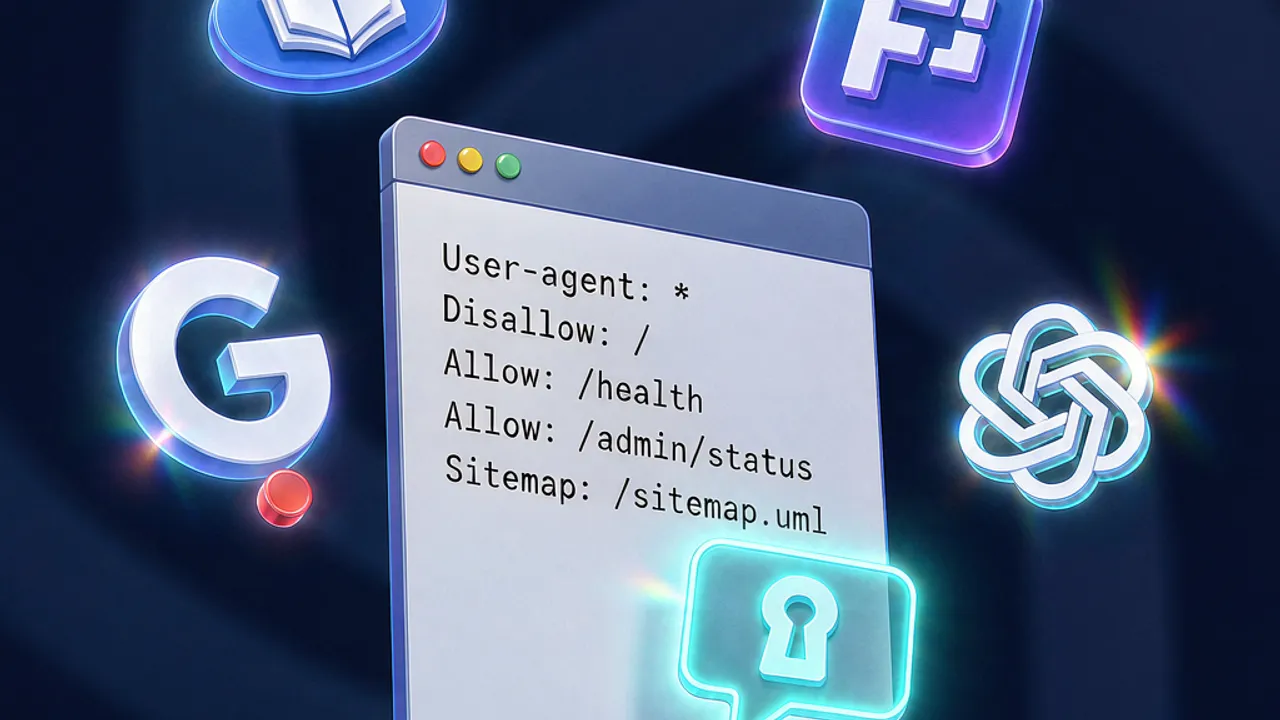
What is the new opt‑out standard for AI scraping?
A joint proposal from several leading AI companies introduces a policy token that lives inside a site’s robots.txt file. When a crawler encounters the token, it must respect the publisher’s wish to stay out of AI‑training pipelines. The idea is to give content owners a single, machine‑readable signal rather than having to negotiate separate agreements with each AI provider. The proposal is being advanced through the Internet Engineering Task Force (IETF) and was first outlined by Kevin Kelley, a technical lead for standards at Anthropic.
Which AI firms are backing the proposal and when will it be active?
According to The Verge report, OpenAI, Google, Microsoft and Anthropic have pledged to honor the token. Anthropic has already implemented the check in its crawlers, while Google and Microsoft plan to add support sometime in 2027. OpenAI says it will roll out the feature in the “coming months.” Meta’s communications head Andy Stone expressed support for the concept, but the company has not confirmed whether its own crawlers will obey the token.
How does the policy token work technically?
The token is a line added to robots.txt, the same file that tells search engines which parts of a site may be indexed. Instead of the traditional User‑Agent directives, the token uses a new syntax defined by the IETF draft. When a crawler reads the file and sees the token, it must stop any activity that would collect data for model training or grounding.
- Granular control – Microsoft’s implementation will let publishers choose between blocking only training data collection or also blocking “grounding,” the process of pulling verified sources at inference time.
- Search visibility – Both Microsoft and Google have said that honoring the token will not affect a site’s appearance in ordinary web search results; the restriction applies solely to AI‑training pipelines.
- Fallback mechanisms – Existing mechanisms such as the Really Simple Licensing (RSL) standard, which lets sites charge crawlers, and Cloudflare’s default block on AI bots remain usable, but the new token aims to simplify the workflow.
Why does this matter for publishers, creators, and researchers?
Content creators have been alarmed by the rapid growth of AI models that ingest publicly available text, images, and video without explicit permission. The lack of a unified opt‑out has forced publishers to negotiate with each vendor individually, a process that is both time‑consuming and legally ambiguous. By providing a single signal that multiple AI companies recognize, the token reduces administrative overhead and makes it easier to enforce content‑use policies.
For researchers, the token offers a clearer boundary: datasets built from web crawls can be filtered to exclude sites that have opted out, improving compliance with copyright and data‑ethics guidelines.
How can developers and researchers experiment with the token using Grafy?
Grafy’s multi‑model environment makes it straightforward to test whether a crawler respects the new signal.
- Create a test site – Host a simple static page and add a
robots.txtfile containing the policy token line suggested by the IETF draft. - Run a crawl with Grafy Chat – Open the Grafy Chat app and select a model that offers web‑search capabilities (e.g., a GPT‑4 based agent). Prompt the model to retrieve information from your test URL. Observe whether the model returns content or reports the site as blocked for training.
- Verify with Grafy Reader – Upload the same
robots.txtfile into Grafy Reader and ask the AI to explain the token’s meaning. This helps confirm that the token is being parsed correctly. - Monitor with Grafy Watch – Use Grafy Watch to keep an eye on any changes to the
robots.txtfile of a real‑world site that has announced participation. The tool will alert you when the token is added or removed, giving live feedback on compliance.
These steps let you see the practical effect of the standard without waiting for the major providers to fully roll out their crawlers. The workflow also demonstrates how Grafy can serve as a sandbox for policy‑compliance testing.
What are the current limitations and open questions?
While the token promises a streamlined opt‑out, several uncertainties remain:
- Adoption timeline – Google and Microsoft have only announced future support; until the feature ships, crawlers from those firms may continue to scrape content.
- Enforcement – The standard relies on voluntary compliance. There is no technical guarantee that a non‑cooperating crawler will honor the token.
- Scope of “grounding” – Microsoft’s granular options raise the question of whether a site that blocks grounding will still be used for inference‑time citation, a nuance that may affect SEO‑related visibility.
- Meta’s stance – Although Meta expressed support, the company has not confirmed implementation, leaving a large portion of the AI ecosystem unaccounted for.
- Legal weight – The token’s legal standing varies by jurisdiction; publishers may still need to pursue contractual or statutory remedies.
Understanding these gaps will be essential for anyone planning a long‑term content‑protection strategy.
Frequently asked questions
How quickly can a publisher expect the token to be respected?
OpenAI intends to enable support within a few months, while Google and Microsoft target 2027. Until then, publishers should continue using existing tools like RSL or Cloudflare blocks for immediate protection.
Does opting out affect my site’s ranking in regular web search?
Both Google and Microsoft have stated that honoring the token will not impact a site’s appearance in standard search results. The restriction applies only to AI‑training and grounding pipelines.
Can I test the token on existing sites that already use robots.txt?
Yes. Add the policy token line to the existing robots.txt file and use Grafy’s Chat or Watch apps to see whether AI‑enabled crawlers respect the new directive. If a model still returns content, the crawler may not yet support the standard.
Source: The Verge — AI — The biggest names in AI are backing a new way to opt out of scraping
More news
AI Agent Performs Brain Injection on Live Mouse
A biotech startup let an Anthropic Claude model direct a robotic arm to inject a gene‑therapy drug into a live mouse’s brain.
Prime Intellect launches Prime Mega MoE, a trainable fused MoE kernel
Prime Intellect unveiled Prime Mega MoE, a trainable fused MoE kernel that speeds forward passes 3.11× and cuts Qwen3 training time by up to 34%.
Mistral releases open‑weight trillion‑parameter model for cybersecurity
Mistral has published the weights for its trillion‑parameter ML4 model, letting organizations run a sovereign AI for cyber defense on‑premises.