Paper Argues 'Positionality,' Not Bias, Describes How LLMs Speak
A new preprint argues bias is the wrong grammar for general LLM use, proposing 'positionality' — a layered account of where a model speaks from.
 Source: Grafy Research Lab
Four researchers are proposing that the field stop treating "bias" as the master term for what large language models do, and use "positionality" instead — the located, articulated, owned and contestable position from which a model's output is taken to come. The argument, set out in a preprint posted on arXiv (arXiv:2611.14079) and submitted to ACM FAccT 2027 in Porto, matters because it changes the question we ask of a model: not how far its output deviates from a neutral standard, but who is speaking and from where.
The authors are Dave Murray-Rust, Elisa Giaccardi, Federico Bomba and Maria Luce Lupetti, and the paper was surfaced by Grafy Research Lab. According to the preprint, the contribution is conceptual rather than empirical: a critical grammar, a framework for placing existing work inside it, and a closing discussion of what follows for how models are made, read and held accountable. The listed keywords are positionality, language models, bias and feminist epistemology.
Why do the authors say bias is the wrong grammar for LLMs?
Bias, as the paper reads the literature, is a deviation from a standard. In decision-making systems that standard can be supplied from outside — a law, a protected attribute, a benchmark, a statistical property — and that external reference is what makes an audit possible. The authors argue that even there the word is used as shorthand, carrying a silent "relative to" that is rarely spelled out.
General-purpose language use removes the external standard altogether. There is no decision to audit, no counterfactual output to compare against and no protected attribute to test around, according to the paper. Bias can still be measured in narrow setups — the authors point to work inserting pronouns into template documents, round-trip translation, gender and style choices in generated images, and studies of expressed ideology — but they treat these as special cases rather than the norm. In cultural production specifically, they argue, having a voice is the objective, so deviation from neutrality is what is being valued rather than a defect to be minimised.
The paper also traces how overloaded the term has become: a statistical sense of estimator error, an electronics sense of setting a circuit's zero point, Friedman and Nissenbaum's 1996 import into computing as systematic and unfair discrimination (preexisting, technical and emergent), and the more recent framing of algorithmic bias as disparate performance across groups. It cites work describing bias as under-defined, the "formalism trap" in fairness research, and fairness as an essentially contested construct. Positionality, the authors write, arrives with practices already attached — owning, articulating, costing and contesting a position — and does not presuppose that an unbiased position exists to fall short of.
What is "laminar" positionality?
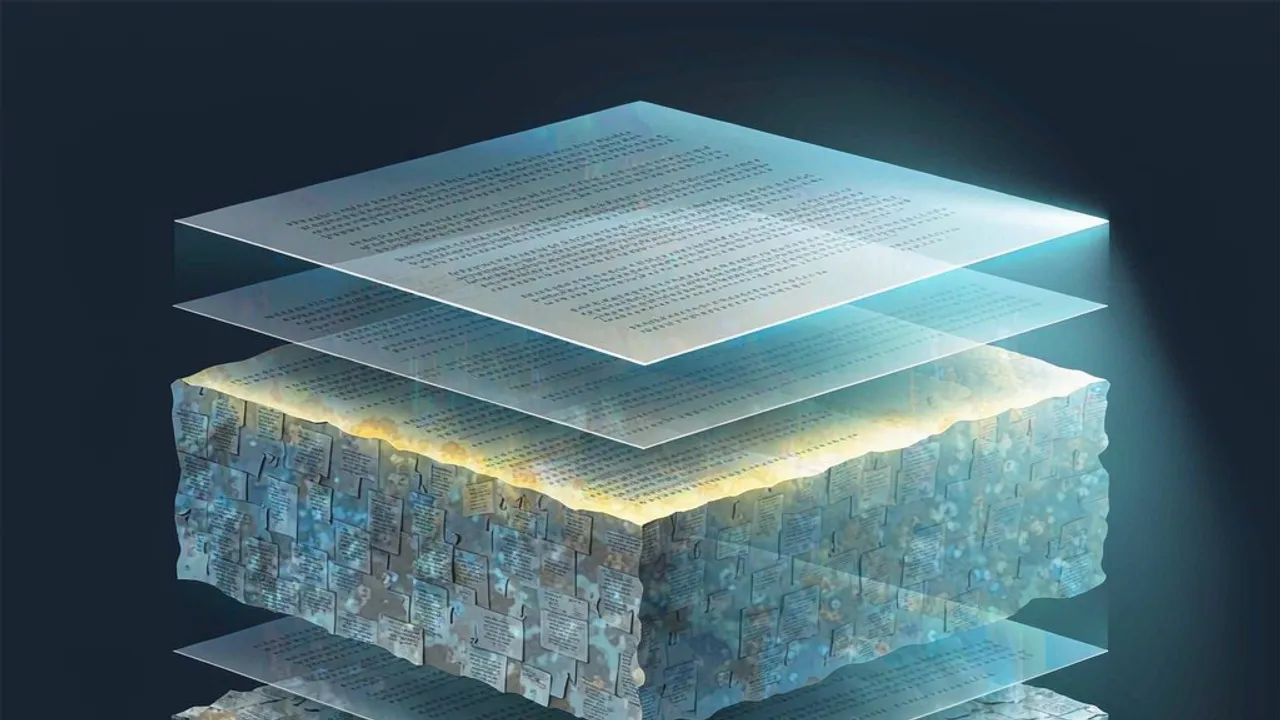
The paper's central image is a stack. A model's positionality is laminar, laid down in layers rather than fixed at a single point, and the section headings name the strata: ground, corpus, training and finetuning, system prompts, application and presentation, and interaction. Each layer inherits from the one beneath it, and the authors are most interested in what they call ruptures and collapses — the places where that inheritance is disavowed, where a deployed system projects a stance its training data does not support, or the reverse.
What is the positionality matrix?
The second contribution is a separation of three things usually collapsed into one. There is the positionality of a model's creators, the positionality they intend the artefact to have, and the positionality the running system actually enacts. The matrix is then used to situate existing research — on encoded ideologies, on the values models embody, on representational shortcomings — in one cell rather than another, on the argument that a finding about intended behaviour is not the same finding as one about enacted behaviour.
Where do the authors say models speak from?
They weigh three answers. The vendors' default is nowhere: even-handed, apolitical instruments whose only issue is some removable bias, approximating neutrality. Against that, the paper cites Neuman's argument for everywhere — models as holding "representations of many social identities without personally inhabiting any one of them", offering a "moral standpoint unavailable to individual human reasoners", and acting as "condensates of human culture".
The authors find that compelling but argue for somewhere. When a model is taken as-if speaking, they contend, it speaks from a particular, sedimented, composite position that can be located and contested even without a singular human social position behind it. They connect this to what they call credibility excess: models being treated as more authoritative than they have earned, which is precisely why the somewhere matters. Models are not accountable speakers, the paper is careful to say, yet positionality can still describe them and the way they are believed beyond their warrant. Philosophically the framing draws on Stengers' cosmopolitics — keeping divergent worlds open rather than flattening everything to one consensus.
How can you explore this with Grafy?
Two of the paper's questions are practical enough to test on your own work. Start with Reader: the arXiv PDF can be read, searched and questioned directly, which is the quickest way to check whether a claim attributed to the paper here is actually made there, and to see how the authors place a specific study in their matrix.
Then try the comparison the paper implies. Chat runs many models side by side, so the same prompt can be put to several of them and the differences in stance read as positionality rather than as error to be corrected away. If you want a record of which layer produced which output, Graph keeps prompts, outputs and model history in a branching structure — a rough working analogue of the strata the paper describes, in your own projects rather than in a vendor's.
Source: From Bias to Positionality: A critical grammar for Large Language Models (arXiv:2611.14079)
Frequently asked questions
Does the paper argue that bias is the right grammar for language models?
No, it argues the opposite. The authors contend that bias is the wrong grammar for what large language models do and how we relate to them, because bias needs a standard supplied from outside and general language use supplies none. They keep bias as a workable frame for decision-making systems, where a law, protected attribute or benchmark can anchor an audit, and propose positionality for everything else.
Does the paper claim language models are accountable speakers?
No. The preprint states that models lack the conditions of accountability required to be a true speaker, and that this is exactly why positionality has to be handled carefully. Its claim is narrower: when a model is taken as-if speaking, its positionality can be located, articulated and contested, and that description also covers the way models are believed beyond their warrant.
Which layers does the paper say make up a model's positionality?
According to the preprint, positionality is laminar and laid down across corpus, tuning, system prompt, application and the live conversation. The paper's sections expand this into ground, corpus, training and finetuning, system prompts, application and presentation, and interaction. Each stratum inherits from the one below, with ruptures and collapses where that inheritance is disavowed.
Source: Grafy Research Lab — From Bias to Positionality: A critical grammar for Large Language Models
More news

Frontier3DBench Tests Whether Coding Agents Build 3D Worlds
Einsia's Frontier3DBench tests whether coding agents can build 3D objects, scenes and working worlds; GPT-6.1-sol led overall. See what it means.

Anthropic launches Claude Fable 5.2, Mythos 5.2, cuts API prices 20%
Anthropic's Claude Fable 5.2 and Mythos 5.2 top several third-party benchmarks and cut API prices 20%. Here's what the effort settings mean for your bill.
Chrome's Modern Web Guidance hits 1.0, adds Firefox and Edge
Chrome released Modern Web Guidance 1.0, giving coding agents expert web best practices, now backed by Firefox and Edge. Here's what changed.