SkillMem Cuts Multi‑Agent AI Storage and Boosts Speed with Tiny External Memories
Researchers unveil SkillMem, a compact external memory that stores reusable AI skills in just 9.6 KB each.
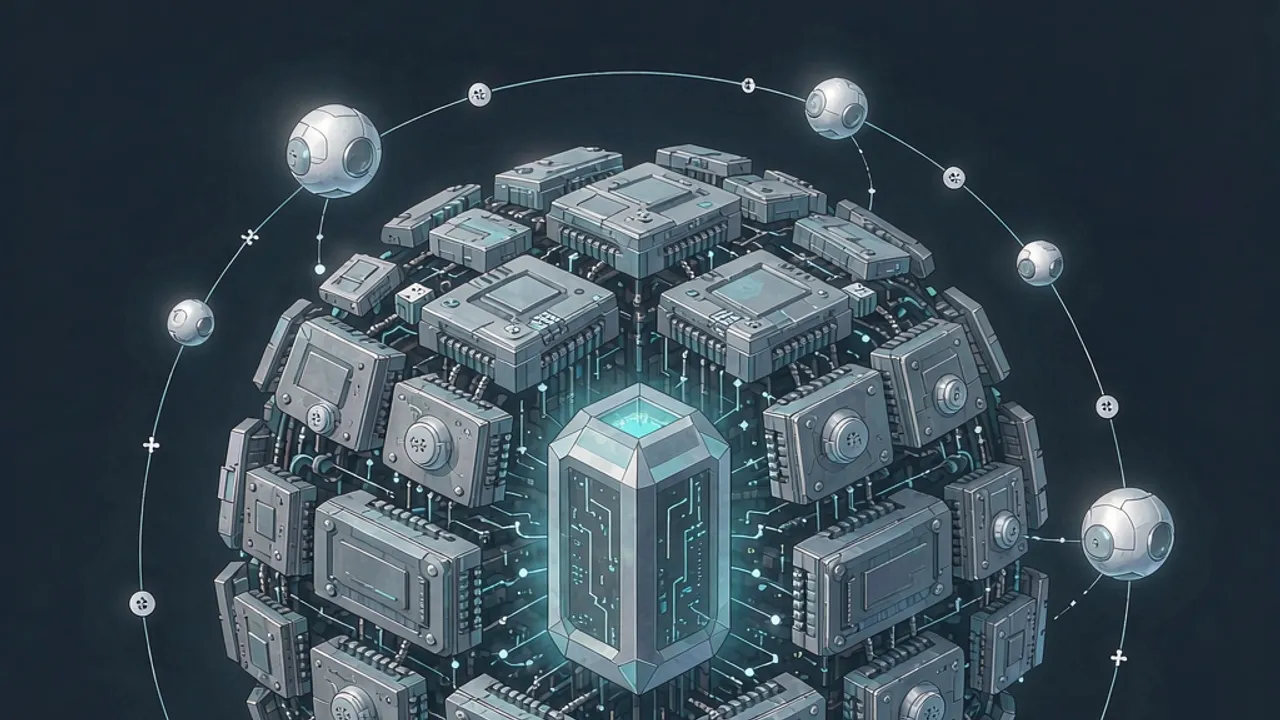
SkillMem, a new method for representing reusable AI skills as tiny external latent memories, promises dramatic reductions in storage and inference cost for latent multi‑agent systems. The approach, described in a pre‑print posted to arXiv on 27 October 2026, shows up to a 4.23× speedup and more than a 38× storage saving while keeping the backbone model frozen.
What is SkillMem and why does it matter?
Latent multi‑agent architectures keep the intermediate reasoning of each agent in continuous vector spaces, allowing agents to communicate without repeatedly invoking the full language model. However, when an agent needs a specific procedural skill—such as “parse a table” or “plan a route”—the skill is traditionally injected as plain text or as a set of model‑specific key‑value caches. Those representations either require the model to re‑process the text each time or demand a large per‑skill footprint in memory.
SkillMem replaces those bulky representations with a compact external memory block. Each skill is stored in an 8×256 latent matrix, amounting to roughly 9.6 KB of data per skill, including a retrieval embedding. The memory is accessed through a role‑conditioned cross‑attention reader that can steer the same skill to agents with different responsibilities, based on their current hidden states. By decoupling skill storage from the model’s parameters, SkillMem lets dozens or hundreds of procedures coexist without exploding memory usage.
How does the external memory work?
The core of SkillMem is a shared cross‑attention module that reads from the external memory. When an agent reaches a point where a skill should be applied, the agent’s role token and its hidden state are used as queries to the memory. The attention mechanism retrieves a skill‑specific vector, which is then injected back into the agent’s latent stream, influencing the next token predictions.
Training follows a behavioral distillation recipe. The authors first run a pair of trajectories—one successful, one failed—on a baseline latent multi‑agent system that receives the skill as plain text. The difference in token‑level predictions induced by the textual skill becomes the supervision signal. The memory vectors and the shared reader are optimized to reproduce that change while the underlying backbone model remains untouched. This strategy lets SkillMem learn to emulate the effect of textual skills without ever storing the full text.
Reported performance gains
Across six benchmark suites and a family of Qwen‑3 models ranging from 4 B to 14 B parameters, SkillMem delivers consistent improvements, especially for the smaller backbones. The authors highlight three quantitative results:
- Storage efficiency – With a fixed 8×256 configuration, each skill occupies only 9.6 KB. For a library of 100 skills, the total storage is reduced by more than 38× compared with conventional layer‑wise key‑value caches or full‑parameter skill modules.
- Inference speed – End‑to‑end latency drops by up to 4.23×, because the model no longer needs to re‑process textual prompts for each skill call.
- Scalability – The same memory layout works unchanged from 4 B to 14 B models, demonstrating that SkillMem can be layered on top of existing latent multi‑agent pipelines without architectural redesign.
These numbers suggest that compact procedural memories can be reused across agents and tasks while preserving the low‑cost inference that latent multi‑agent systems are designed for.
What this means for developers of AI agents
For teams building autonomous assistants, tool‑using bots, or collaborative agent swarms, SkillMem offers a practical pathway to embed a growing repertoire of capabilities without blowing up GPU memory. Instead of shipping a new fine‑tuned model for each added function, developers can compile the function into a 9.6 KB memory slot and let the shared reader surface it on demand. The role‑conditioned design also means that the same skill can be repurposed for agents with different responsibilities—e.g., a planning skill used by both a navigation agent and a resource‑allocation agent—simply by changing the role token.
Because the backbone remains frozen, SkillMem can be retro‑fitted onto existing latent multi‑agent deployments. Organizations that have already invested in Qwen‑3 or similar models can augment them with new skills without retraining the entire system, reducing both computational cost and engineering overhead.
How to explore SkillMem with Grafy
While Grafy does not yet host a dedicated SkillMem module, creators and researchers can investigate the concept using two of Grafy’s core apps:
- Reader – Upload the SkillMem PDF (or the arXiv link) to the Grafy Reader at [/reader] and ask the built‑in chat to summarize sections, compare memory footprints, or extract the training pipeline details. The AI can also help you locate the code repositories linked from the paper’s supplemental material.
- Chat – Use Grafy Chat at [/chat] to experiment with prompting a latent multi‑agent model (e.g., a Qwen‑3 variant) and see how injecting a textual skill differs from a hypothetical external memory call. While Grafy does not provide a ready‑made SkillMem layer, the multi‑model interface lets you contrast performance across models of different sizes.
For developers who want to prototype the external memory themselves, Grafy’s Code studio at [/code] can be used to write a small cross‑attention module, load the 8×256 tensors, and hook it into an open‑source latent multi‑agent framework. The modular nature of Grafy’s cloud model routing (OpenRouter, Vertex AI, Replicate, etc.) makes it straightforward to test the same memory on several backbones without changing hardware.
Future directions and open questions
SkillMem opens several research avenues. One open question is how the memory size scales when moving beyond 100 skills—does the 8×256 layout remain sufficient, or will hierarchical memory be needed? Another area is dynamic skill creation: can agents generate new memory slots on‑the‑fly from observed successes, turning the external memory into a lifelong learning repository? Finally, the role‑conditioned attention could be extended to multi‑modal agents (e.g., vision‑language bots) where the same procedural knowledge guides both textual and visual reasoning.
The paper’s authors suggest that the external memory design is compatible with other latent reasoning paradigms, hinting at broader applicability beyond Qwen‑3. As the AI community continues to experiment with agent swarms, tool‑using bots, and autonomous pipelines, compact skill stores like SkillMem may become a standard component for keeping systems both lightweight and versatile.
Source: SkillMem: Compact External Skill Memory for Latent Multi‑Agent Reasoning
Frequently asked questions
How does SkillMem differ from traditional prompt‑based skill injection?
Traditional approaches feed the skill as plain text each time it is needed, which incurs token‑level processing cost and occupies memory for the entire prompt. SkillMem stores the skill as a fixed‑size latent vector that the model can read directly via attention, eliminating repeated parsing and drastically shrinking storage.
Can SkillMem be used with models other than Qwen‑3?
The authors demonstrate compatibility across Qwen‑3 models from 4 B to 14 B parameters, but the underlying mechanism—cross‑attention over an external memory—does not depend on a specific architecture. In principle, any latent multi‑agent system that maintains continuous hidden states could adopt the same reader module.
Do I need to fine‑tune my model to use SkillMem?
No. SkillMem is trained while the backbone model stays frozen. Only the external memory slots and the shared reader are updated via behavioral distillation, meaning you can add new skills without re‑training the entire language model.
Source: arXiv AI — SkillMem: Compact External Skill Memory for Latent Multi-Agent Reasoning
More news
Meta’s Muse Agent Sparks Cautious Optimism Across Industries
Meta’s Muse shopping assistant has attracted millions of users but early data shows modest sales.
AI Agent Performs Brain Injection on Live Mouse
A biotech startup let an Anthropic Claude model direct a robotic arm to inject a gene‑therapy drug into a live mouse’s brain.
Vercel Labs releases agent‑desktop, open‑source Rust CLI for AI agents
Vercel Labs has open‑sourced agent‑desktop, a Rust CLI that lets any AI agent control macOS.