Verify by Doing lets AI agents self‑improve without external feedback
Researchers unveil Verify by Doing, a method that co‑evolves an agent’s execution and its own verification to learn from internal signals.
 Source: Grafy Research Lab
Verify by Doing (VbD) introduces a way for autonomous AI agents to improve their own behavior when no external ground‑truth or benchmark score is available. The approach matters because many real‑world deployments lack reliable test‑time feedback, leaving agents to guess whether they succeeded and risking harmful updates.
What is Verify by Doing and why does it matter?
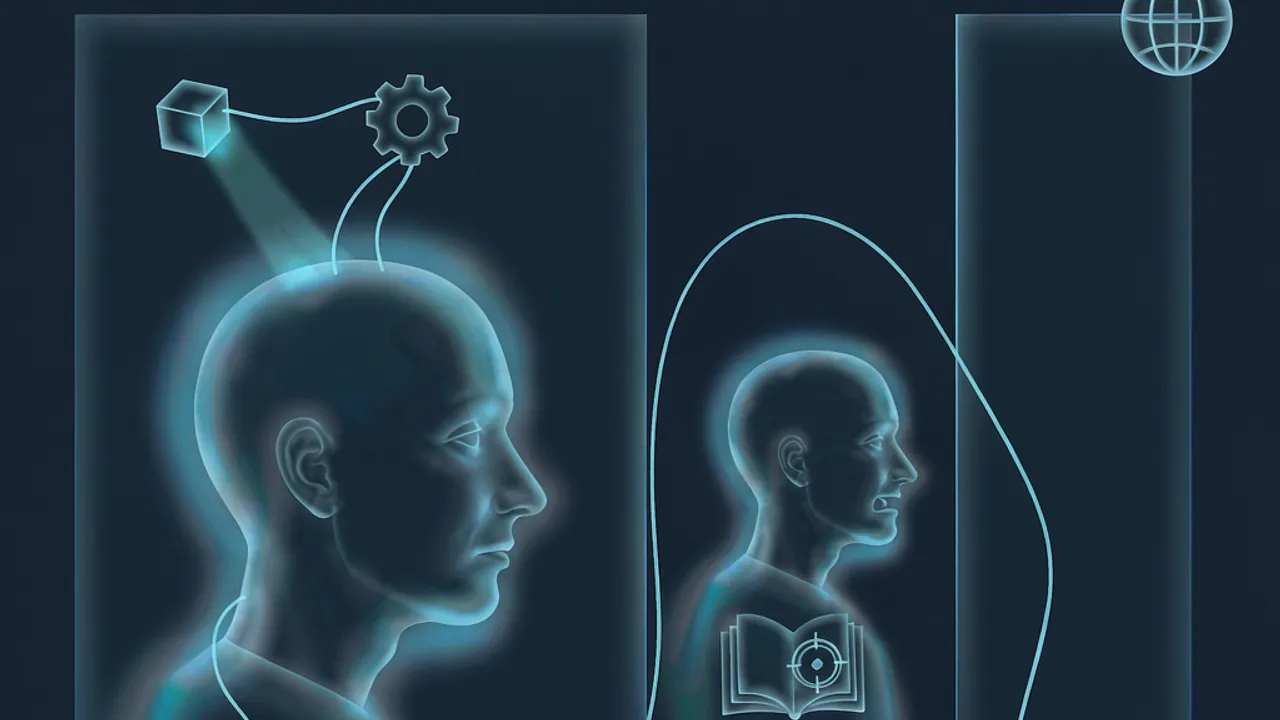
VbD is a framework that keeps the underlying model weights fixed while allowing two separate harnesses—an Actor that carries out a task and an Evaluator that inspects the resulting artifacts—to evolve together. According to the Grafy Research Lab paper, the Evaluator gathers evidence from the environment using tools, records which requirements are satisfied, violated, or unresolved, and turns those findings into an internal signal that guides both output selection and future harness updates. This internal feedback loop removes the dependence on external labels, which are often unavailable for bespoke or privacy‑sensitive tasks.
How does VbD co‑evolve execution and verification?
The process starts with an initial pair of harnesses. The Actor runs a trial, producing an execution record, a final state, and a deliverable. Simultaneously, the Evaluator runs its own harness on the same trial, generating a verification report that lists evidence for each requirement. After the trial, a comparative review pits the new Evaluator against the retained one on the same candidate set. The retained Evaluator’s findings decide which candidate output is chosen, while the Actor adopts a new harness only if its fresh output receives sufficient support from the Evaluator. An editor component then uses the combined evidence to propose further edits to either harness, enabling a continuous, within‑task co‑evolution.
What evidence does VbD use to decide success without external feedback?
VbD’s Evaluator performs active verification: it invokes tools to query artifacts (e.g., spreadsheet cells, UI elements) and recomputes derived values such as expense totals or after‑tax revenue. The findings are categorized as satisfied, violated, or unresolved, forming a structured evidence set. This evidence replaces a traditional binary success flag and becomes the basis for a preference signal that ranks candidate outputs. By comparing how much evidential support each candidate receives, VbD can select the most trustworthy result even when no external rubric is present.
How does VbD perform compared to existing methods?
The authors evaluated VbD on three benchmark suites—AutomationBench, Banking, and selected GDPval tasks. Across all three, VbD achieved the highest overall scores among the compared baselines, which include methods that keep verification static or rely on external feedback. Ablation studies showed that removing active verification or the Evaluator’s evolution consistently reduced performance, confirming that both contributions are essential. Moreover, when the candidate pool was held constant, the evolved Evaluator improved pass rates and partial credit over the initial Evaluator, demonstrating better selection from identical outputs.
Applying VbD concepts with Grafy
While Grafy does not yet embed a full VbD engine, creators and researchers can experiment with its underlying ideas using existing tools. The Grafy Reader app lets you upload the VbD paper (PDF) and query it with natural language, reproducing the authors’ experimental setup or extracting the verification harness details. For hands‑on prototyping, the Grafy Code studio can be used to script a simple Actor‑Evaluator loop: write an execution function, attach tool‑based checks, and iteratively update the verification logic based on recorded evidence. Visualizing the evolution of prompts and harnesses is straightforward with the Grafy Graph view, which can map each trial, its evidence report, and subsequent harness edits as nodes in a branching graph. Together, these apps provide a sandbox for exploring VbD‑style self‑improvement without needing a dedicated research framework.
For a deeper dive into the original methodology, consult the full arXiv paper (https://arxiv.org/abs/2611.15276).
Frequently asked questions
How does Verify by Doing differ from methods that use external benchmark scores?
VbD replaces external scores with an internal evidence‑driven signal generated by an active Evaluator. Instead of comparing outputs to a hidden ground truth, the Evaluator inspects the task artifacts directly, records requirement satisfaction, and uses that record to rank candidates. This allows agents to improve even when benchmark labels are unavailable.
Can the Evaluator’s harness be updated without changing the Actor’s harness?
Yes. VbD separates the retention decisions for the Evaluator and the Actor. The Evaluator undergoes comparative review on the same candidate set, and its adoption is decided independently of whether the Actor adopts a new execution harness. This separation lets verification improve even if execution remains static.
What kind of tools does the Evaluator use for active verification?
The paper cites examples such as spreadsheet cell retrieval, recomputation of totals, and UI state inspection. In practice, any tool that can query the environment—APIs, database lookups, or UI automation scripts—can be incorporated into the Evaluator’s harness to gather concrete evidence about task requirements.
More news
Study Shows AI Develops Distinct Proof Style When Reproving Euclid’s Elements
Researchers asked three large language models to reprove all 465 propositions of Euclid’s Elements and found AI‑generated proofs show citation patterns.
Prefix‑Guided Sampling Cuts Test‑Time Costs While Boosting LLM Reasoning
A new method called Prefix‑Guided Sampling (PreG) uses early confidence signals to prune low‑quality reasoning paths.
Sparse Teacher Support Cuts LLM Distillation Cost Without Losing Accuracy
Researchers show that keeping only 0.01% of a language model's vocabulary during forward‑KL distillation preserves MMLU‑Pro performance while slashing training.