Local LLMs Excel at Textbook Retrieval but Stumble on Fresh Research Papers
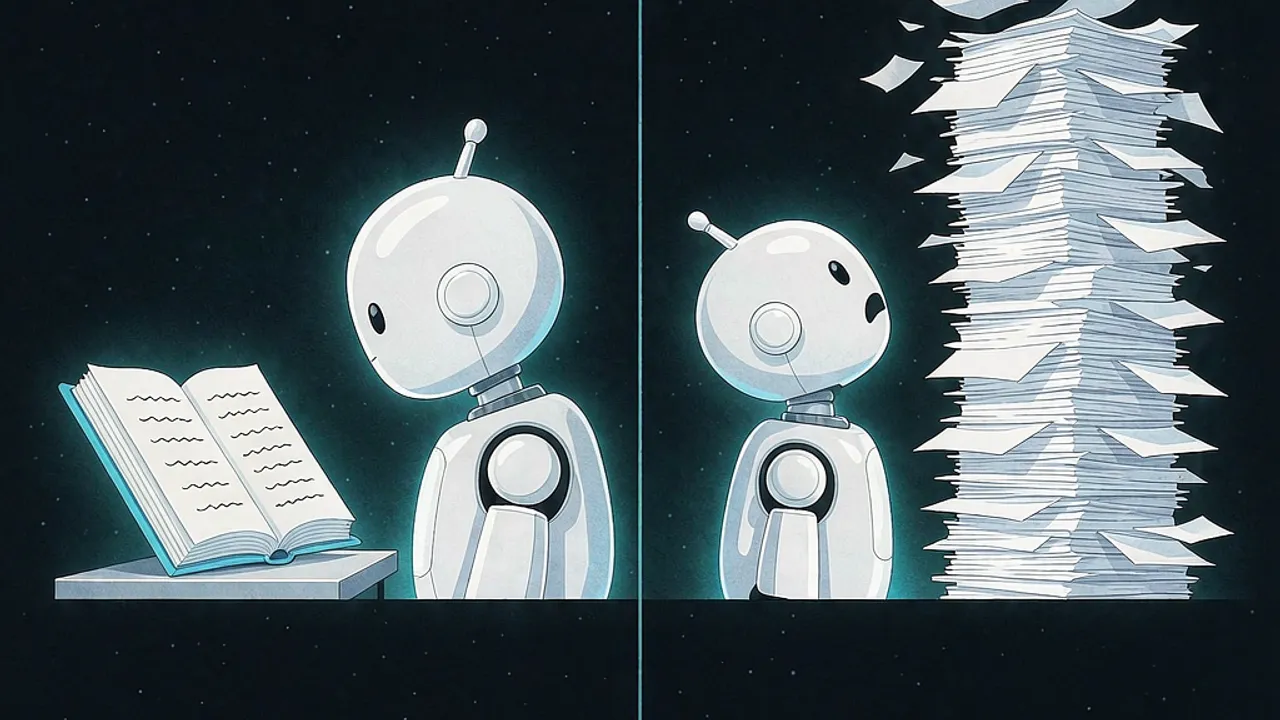
A recent Towards Data Science test shows local large language models score 12‑20/20 on textbook RAG tasks but drop to 0‑9/15 on a brand‑new research paper.
 Source: Towards Data Science
Local large language models (LLMs) achieved near‑perfect scores on textbook‑style Retrieval‑Augmented Generation (RAG) tasks but performed poorly on a newly published research paper, according to a recent post on Towards Data Science. The gap reveals how quickly model knowledge can become outdated and why developers need to pair local inference with fresh data pipelines.
What was the experiment?
The author set up five different configurations of locally hosted LLMs and ran a blind‑grading test that compared two knowledge domains. One set of queries was drawn from standard textbook material, while the other set consisted of questions based on a research paper released earlier this year. The grading pack was hidden from the models, ensuring that the scores reflected genuine understanding rather than memorised answers. All five setups used the same retrieval backend, but varied in model size and prompting strategy.
How did the models fare on textbook material?
When the same local LLMs were asked to answer textbook questions, they consistently earned high marks. Scores ranged from 12 to 20 out of a possible 20 points, indicating that the models could retrieve relevant passages, synthesize information, and generate accurate responses for well‑established knowledge. The results suggest that, for static curricula or legacy documentation, a locally run LLM with an appropriate vector store can be a reliable and cost‑effective alternative to cloud APIs.
Why did the models struggle with a new research paper?
The second half of the test painted a starkly different picture. The same five configurations were evaluated on questions derived from a research paper published this year, and their scores fell to a range of 0 to 9 out of 15. The author attributes the drop to two main factors:
- Temporal gap – Local models were trained on data that pre‑dated the paper, so the underlying language model simply did not contain the concepts or terminology introduced in the latest work.
- Sparse retrieval signals – Fresh papers often contain dense, domain‑specific jargon and novel citations that are poorly represented in the vector index built from older corpora. The retrieval step therefore returned less relevant chunks, leaving the generator with insufficient context.
These findings echo a broader concern: even the most capable retrieval pipelines cannot compensate for a language model that lacks exposure to the newest literature.
What does this mean for creators, developers, and researchers?
For creators building AI‑powered tutoring or documentation assistants, the takeaway is clear: local LLMs can handle static, well‑curated content with impressive accuracy. However, any application that relies on up‑to‑date scientific knowledge—such as literature review tools, hypothesis generators, or domain‑specific chatbots—will need a strategy to keep the underlying model current.
Developers can mitigate the gap by:
- Hybrid pipelines that combine a local LLM for fast, low‑cost inference with a cloud‑based model that receives periodic updates.
- Dynamic indexing that continuously ingests new PDFs, arXiv pre‑prints, or conference proceedings, ensuring the retrieval layer reflects the latest information.
- Fine‑tuning or LoRA adapters trained on recent papers, which can inject fresh terminology without retraining the entire model.
Researchers should treat local RAG evaluations as a baseline rather than a definitive measure of a model’s research‑reading ability. The test underscores the importance of aligning model freshness with the pace of scientific discovery.
How to explore this issue with Grafy
Grafy provides two apps that let you reproduce and extend the experiment without leaving the platform.
- Reader (/reader) lets you upload PDFs, index them, and ask natural‑language questions directly against the document collection. By loading a textbook and a recent paper side by side, you can observe how retrieval quality changes.
- Chat (/chat) enables you to run the same local LLMs used in the study, compare their answers, and switch instantly to a cloud model for contrast. Because Grafy supports multiple models in parallel, you can benchmark cost versus performance in real time.
A practical workflow might look like this: ingest a set of textbook chapters into Reader, generate a knowledge graph, then query the graph with Chat using a local model like Llama‑2‑7B. Next, add a fresh research PDF to the same index and repeat the queries with a cloud‑hosted Claude or GPT‑4. Grafy’s Graph view (/graph) can visualize the prompt‑output lineage, helping you pinpoint where retrieval fails.
By leveraging these tools, creators can decide whether a purely local stack meets their needs or whether a hybrid approach is warranted.
Looking ahead
The experiment highlights a fundamental trade‑off in AI‑augmented knowledge work: locality offers speed, privacy, and cost advantages, but it comes at the price of temporal relevance. As the research community continues to publish at an accelerating rate, developers will need to build pipelines that automatically refresh both the retrieval index and, where feasible, the language model itself.
Future work may explore:
- Continuous fine‑tuning pipelines that ingest new papers nightly.
- Modular retrieval that combines dense vector search with sparse keyword matching to capture novel terms.
- Model‑agnostic adapters that can be swapped in without retraining the base model.
Until such solutions become mainstream, the safest bet for mission‑critical, up‑to‑date AI assistants is a hybrid design that pairs the efficiency of local LLMs with the freshness of cloud‑based updates.
Source: https://towardsdatascience.com/local-llms-handle-textbook-rag-but-fail-on-new-research-papers/
Source: Towards Data Science — Local LLMs Handle Textbook RAG but Fail on New Research Papers
More news
Edge‑Native Multimodal RAG Achieves Stable Generation on Consumer GPUs
A new arXiv paper shows that a 7B model can run retrieval‑augmented generation on Turing GPUs using NF4 quantization and a decoupled visual pipeline.
EvoX Introduces a Runtime Policy to Boost LLM Agent Reliability
The new Rust‑based EvoX runtime applies a second, operational policy to LLM agents.
LightTAR boosts multimodal tabular learning with cheap target‑aware embeddings
Researchers introduce LightTAR, a fast method that adds task‑aware features to PCA‑reduced embeddings.