Small Models Narrow Accuracy Gap for AI Coding Agents, Study Finds
A new study shows that recent small open‑weight models can match larger counterparts on a software‑engineering benchmark.
 Source: Grafy Research Lab
What did the researchers investigate?
The paper titled Reducing Inference Cost of Coding Agents with Timeout Cascades examines the growing expense of running AI‑driven coding assistants. According to the authors – Boxi Zhou, German Sviridov, Dmitrii Ustiugov, and Haris Javaid – these agents rely on large language models that consume significant GPU resources, limiting both profitability and scalability. To address this, the study evaluated 36 popular open‑weight models released since 2024 on a standard software‑engineering benchmark. The goal was to see whether newer, smaller models could deliver comparable accuracy while lowering inference costs.
How do small models compare to larger ones?
The results indicate that the performance gap between large and small models is shrinking. The authors report that recent small models are “closing the accuracy gap compared to their large counterparts.” While the paper does not provide exact percentage points, the observation suggests that developers may no longer need to default to the most massive models for coding tasks. This finding is especially relevant for teams that must balance model quality against operational budgets.
Why does inference cost matter for coding agents?
Inference cost encompasses the GPU compute time required to generate a response. For coding agents that operate interactively, each query can trigger a full forward pass through a large transformer, consuming dozens of dollars of cloud compute per hour. High costs restrict the deployment of such agents in continuous‑integration pipelines, educational tools, or low‑margin SaaS products. By demonstrating that smaller models can achieve similar accuracy, the study points to a path for making AI‑assisted development more economically viable.
What methods were used to analyze the gap?
Beyond benchmarking, the authors probed the structure of the accuracy discrepancy. They examined how different model sizes handle varied coding scenarios, such as bug fixing, code synthesis, and documentation generation. By dissecting performance across these sub‑tasks, the paper identifies where small models still lag and where they match larger peers. This granular view helps pinpoint opportunities for targeted improvements, such as fine‑tuning on specific code domains or employing hybrid inference strategies.
How can Grafy users apply these findings?
Grafy’s AI coding studio, Grafy Code, lets you switch between multiple models for a single project. Armed with the study’s insights, you can experiment with smaller, cheaper models for routine code suggestions while reserving larger models for complex refactoring tasks. Additionally, the Reader app lets you import the arXiv paper, search its sections, and ask follow‑up questions directly to the AI, streamlining the research‑to‑implementation workflow. By iterating on model selection within Grafy, developers can achieve a balance between cost efficiency and code quality, mirroring the paper’s conclusions.
Frequently asked questions
Do smaller models truly match the accuracy of large models on all coding tasks?
The study finds that recent small models close the overall accuracy gap, but performance still varies by sub‑task. For straightforward code completion they can be comparable, while more intricate reasoning may still benefit from larger models.
How many models were evaluated in the research?
A total of 36 open‑weight models released since 2024 were benchmarked, covering a range of sizes and architectures.
Can I use Grafy to test the cost differences between models myself?
Yes. In Grafy Code you can select different models for the same prompt and monitor token usage and latency, giving you a practical view of inference cost versus output quality.
Source: Grafy Research Lab — Reducing Inference Cost of Coding Agents with Timeout Cascades
More news

Learned Multigranular Memory Retrieval Boosts Small LLM QA Performance
A new paper introduces LMMR, a learned multigranular memory retrieval method that trims input to under 400 tokens while raising F1 scores on HotpotQA and other.
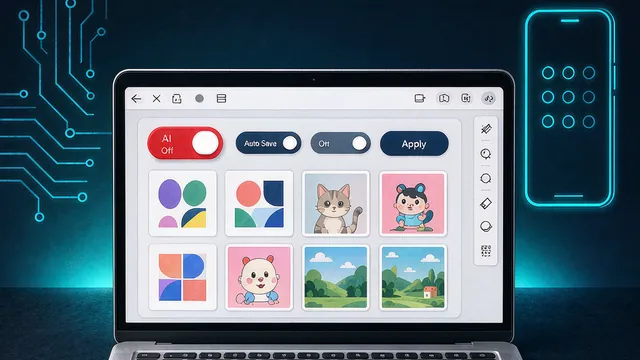
Canva introduces an AI “off” toggle for its design suite
Canva now lets users disable most generative AI tools via a new toggle, addressing complaints about AI overload while keeping essential helpers active.
Claude Code and Other Coding Agents Now Run Cloud‑Based 24/7
A Towards Data Science guide shows two ways to keep Claude Code and similar coding agents online continuously—either via a ready‑made cloud toggle.