Stanford Open-Sources Memorilla, a 16‑Token Memory Module for Frozen LLMs
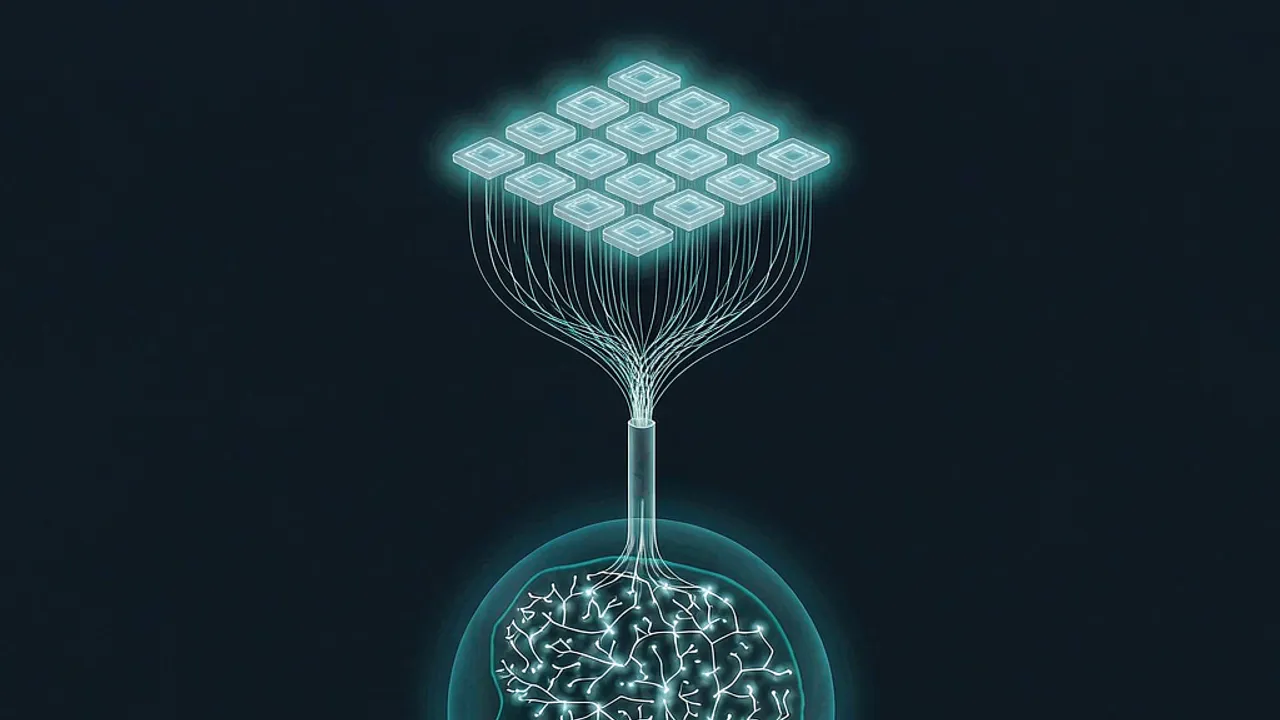
Stanford researchers released Memorilla, an open‑source module that compresses a document collection into just 16 memory tokens for frozen Qwen3‑8B.
 Source: MarkTechPost
What is Memorilla and how does it work?
Memorilla is a latent memory module introduced by researchers at Stanford University. The system learns to compress an entire document collection into a fixed set of 16 memory tokens. Those tokens are then appended to the prompt of a frozen large language model—in the paper’s experiments, the Qwen3‑8B model—so the model can retrieve relevant information without expanding its context window. The module is trained separately from the LLM and can be dropped in as a plug‑in, keeping the underlying language model unchanged.
How does Memorilla perform compared to full‑context retrieval?
According to MarkTechPost, Memorilla reaches accuracy on the FactKG benchmark while using fewer document tokens than feeding the full collection into the model’s context. This dramatic reduction in token count translates into lower inference latency and cheaper compute, while still preserving most of the factual recall that a full‑context approach would provide.
Why does a frozen LLM benefit from a separate memory module?
Frozen LLMs cannot be fine‑tuned on new corpora without expensive retraining. By attaching an external memory that stores compressed knowledge, developers can extend the model’s knowledge base on the fly. The memory acts as a learned index: it selects the most salient pieces of information and encodes them into a small token set that the frozen model can attend to directly. This approach sidesteps the need for costly model updates and keeps the inference pipeline lightweight.
How can developers integrate Memorilla into their projects?
The Memorilla codebase is released under an open‑source license on GitHub. Developers can clone the repository, train the memory encoder on their own document set, and then prepend the resulting 16 tokens to any prompt sent to a compatible LLM API. Because the module works with a frozen model, integration requires only a small wrapper that handles token generation and concatenation. For teams using Grafy, the Grafy Code studio offers a ready environment to run the repository, install dependencies, and test the end‑to‑end pipeline without leaving the browser.
Where does this fit within Grafy’s ecosystem?
Grafy users can experiment with Memorilla in several ways:
- Use Grafy Code to clone the open‑source repo, train the memory encoder on a custom corpus, and script the token‑injection step.
- Leverage Grafy Reader to ingest the original Stanford paper, ask questions about the methodology, and generate summaries directly in the workspace.
- Test the combined system with Grafy Chat by loading the frozen Qwen3‑8B model alongside the 16‑token memory, then compare responses with and without the memory module.
These tools let creators, developers, and researchers explore the benefits of latent memory without needing a separate hardware setup.
Source: MarkTechPost (https://www.marktechpost.com/2026/11/14/stanford-memorilla-memory-system-16-memory-tokens/)
Source: MarkTechPost — Stanford Research Open-Sources Memorilla, a Latent Memory Module for Frozen LLMs
More news
Bolt PCHIE releases deterministic, tamper‑evident safety harness for AI agents
Developer James Dean Wentworth released Bolt PCHIE, an open‑source harness that logs every AI agent decision in a tamper‑evident hash chain.
MIGRO Introduces Decoupled Long‑Term Memory for Evolving Language Models
Researchers unveiled MIGRO, a decoupled long‑term memory system that lets successive language models share exact user histories while using compact storage.
Active Learning Model Cuts LLM Retrieval Energy by 96% for Long Queries
Researchers introduced the LLM Active Approximation Model (LAAM), a hybrid retrieval system that preserves most of the relevance of full LLM reranking.