guardscope Framework Quantifies Runtime Control Coverage for LLM Agents
A new arXiv study introduces guardscope, a two‑stage framework that measures how many of an LLM agent's action paths are inspected by runtime controls.
The AI news that matters for people who make things — what happened, and how to put it to work in Grafy.

A new arXiv study introduces guardscope, a two‑stage framework that measures how many of an LLM agent's action paths are inspected by runtime controls.

Researchers analyzed 2,400 runs of ten LLMs on four public‑service scenarios and found agents read files 97% of the time but only produce useful output.

A new arXiv study shows 38‑82% of AI coding agents produce a correct patch on their first edit but then waste up to 60% of steps before stopping.

A new benchmark, WordInferBench, challenges AI agents to infer formatting changes from Word document context.

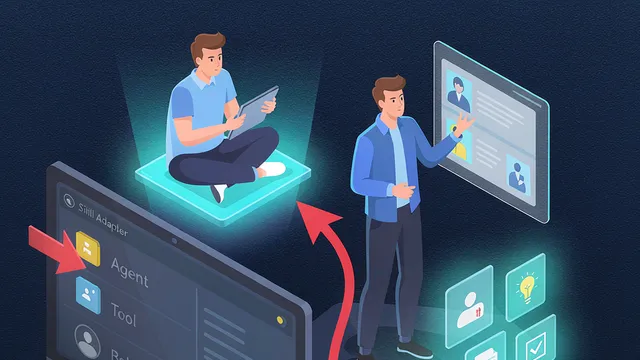
Researchers unveiled Skill Adapter, a framework that personalizes general‑purpose skills and routes them online.

A new Towards Data Science guide walks developers through creating an EV purchase adviser and a support bot with the OpenAI Agents SDK.

Liquid AI unveiled LFM3, a multimodal family of small open-weight models for specialized intelligence, with benchmarks and edge focus.