Study Finds Confidence Scores Don't Guarantee Better LLM Answers
Researchers show that confidence signals can rank correct responses but often fail to improve outcomes.
Try in Readerllmconfidenceevaluationai
The AI news that matters for people who make things — what happened, and how to put it to work in Grafy.
Researchers show that confidence signals can rank correct responses but often fail to improve outcomes.
Researchers unveiled VisualArtifactSpec 1.0, a 211‑task benchmark spanning presentations.
DetourBench, a new benchmark, measures interactive AI agents by the exact number of actions needed.
A new arXiv survey defines Agent-as-a-Judge, an active evaluator that gathers missing evidence.
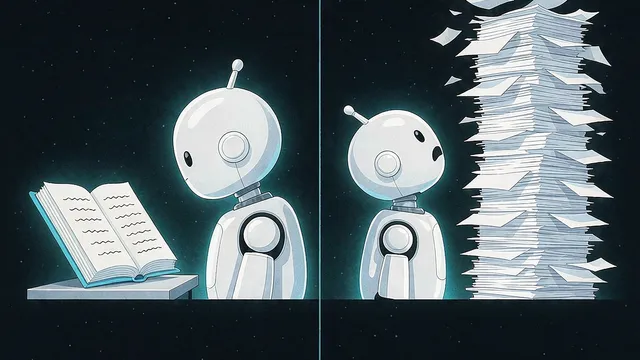
A recent Towards Data Science test shows local large language models score 12‑20/20 on textbook RAG tasks but drop to 0‑9/15 on a brand‑new research paper.
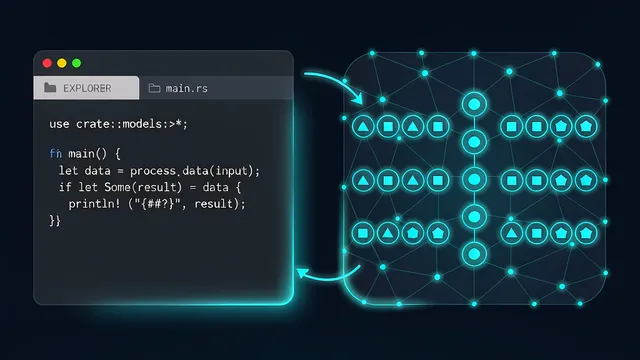
The new Rust‑based EvoX runtime applies a second, operational policy to LLM agents.
A new arXiv paper introduces Seq@K, an evaluation protocol that measures a language model’s ability to solve tasks within K sequential attempts using feedback.
Researchers unveil FilingLoop, an interactive benchmark for LLM agents that review SEC filings.